Workflow Configuration
Workflows provide flexible orchestration capabilities. You can freely arrange workflow processes and customize execution steps. This article describes the related configuration options.
# Creation Methods
# Create a Blank Workflow
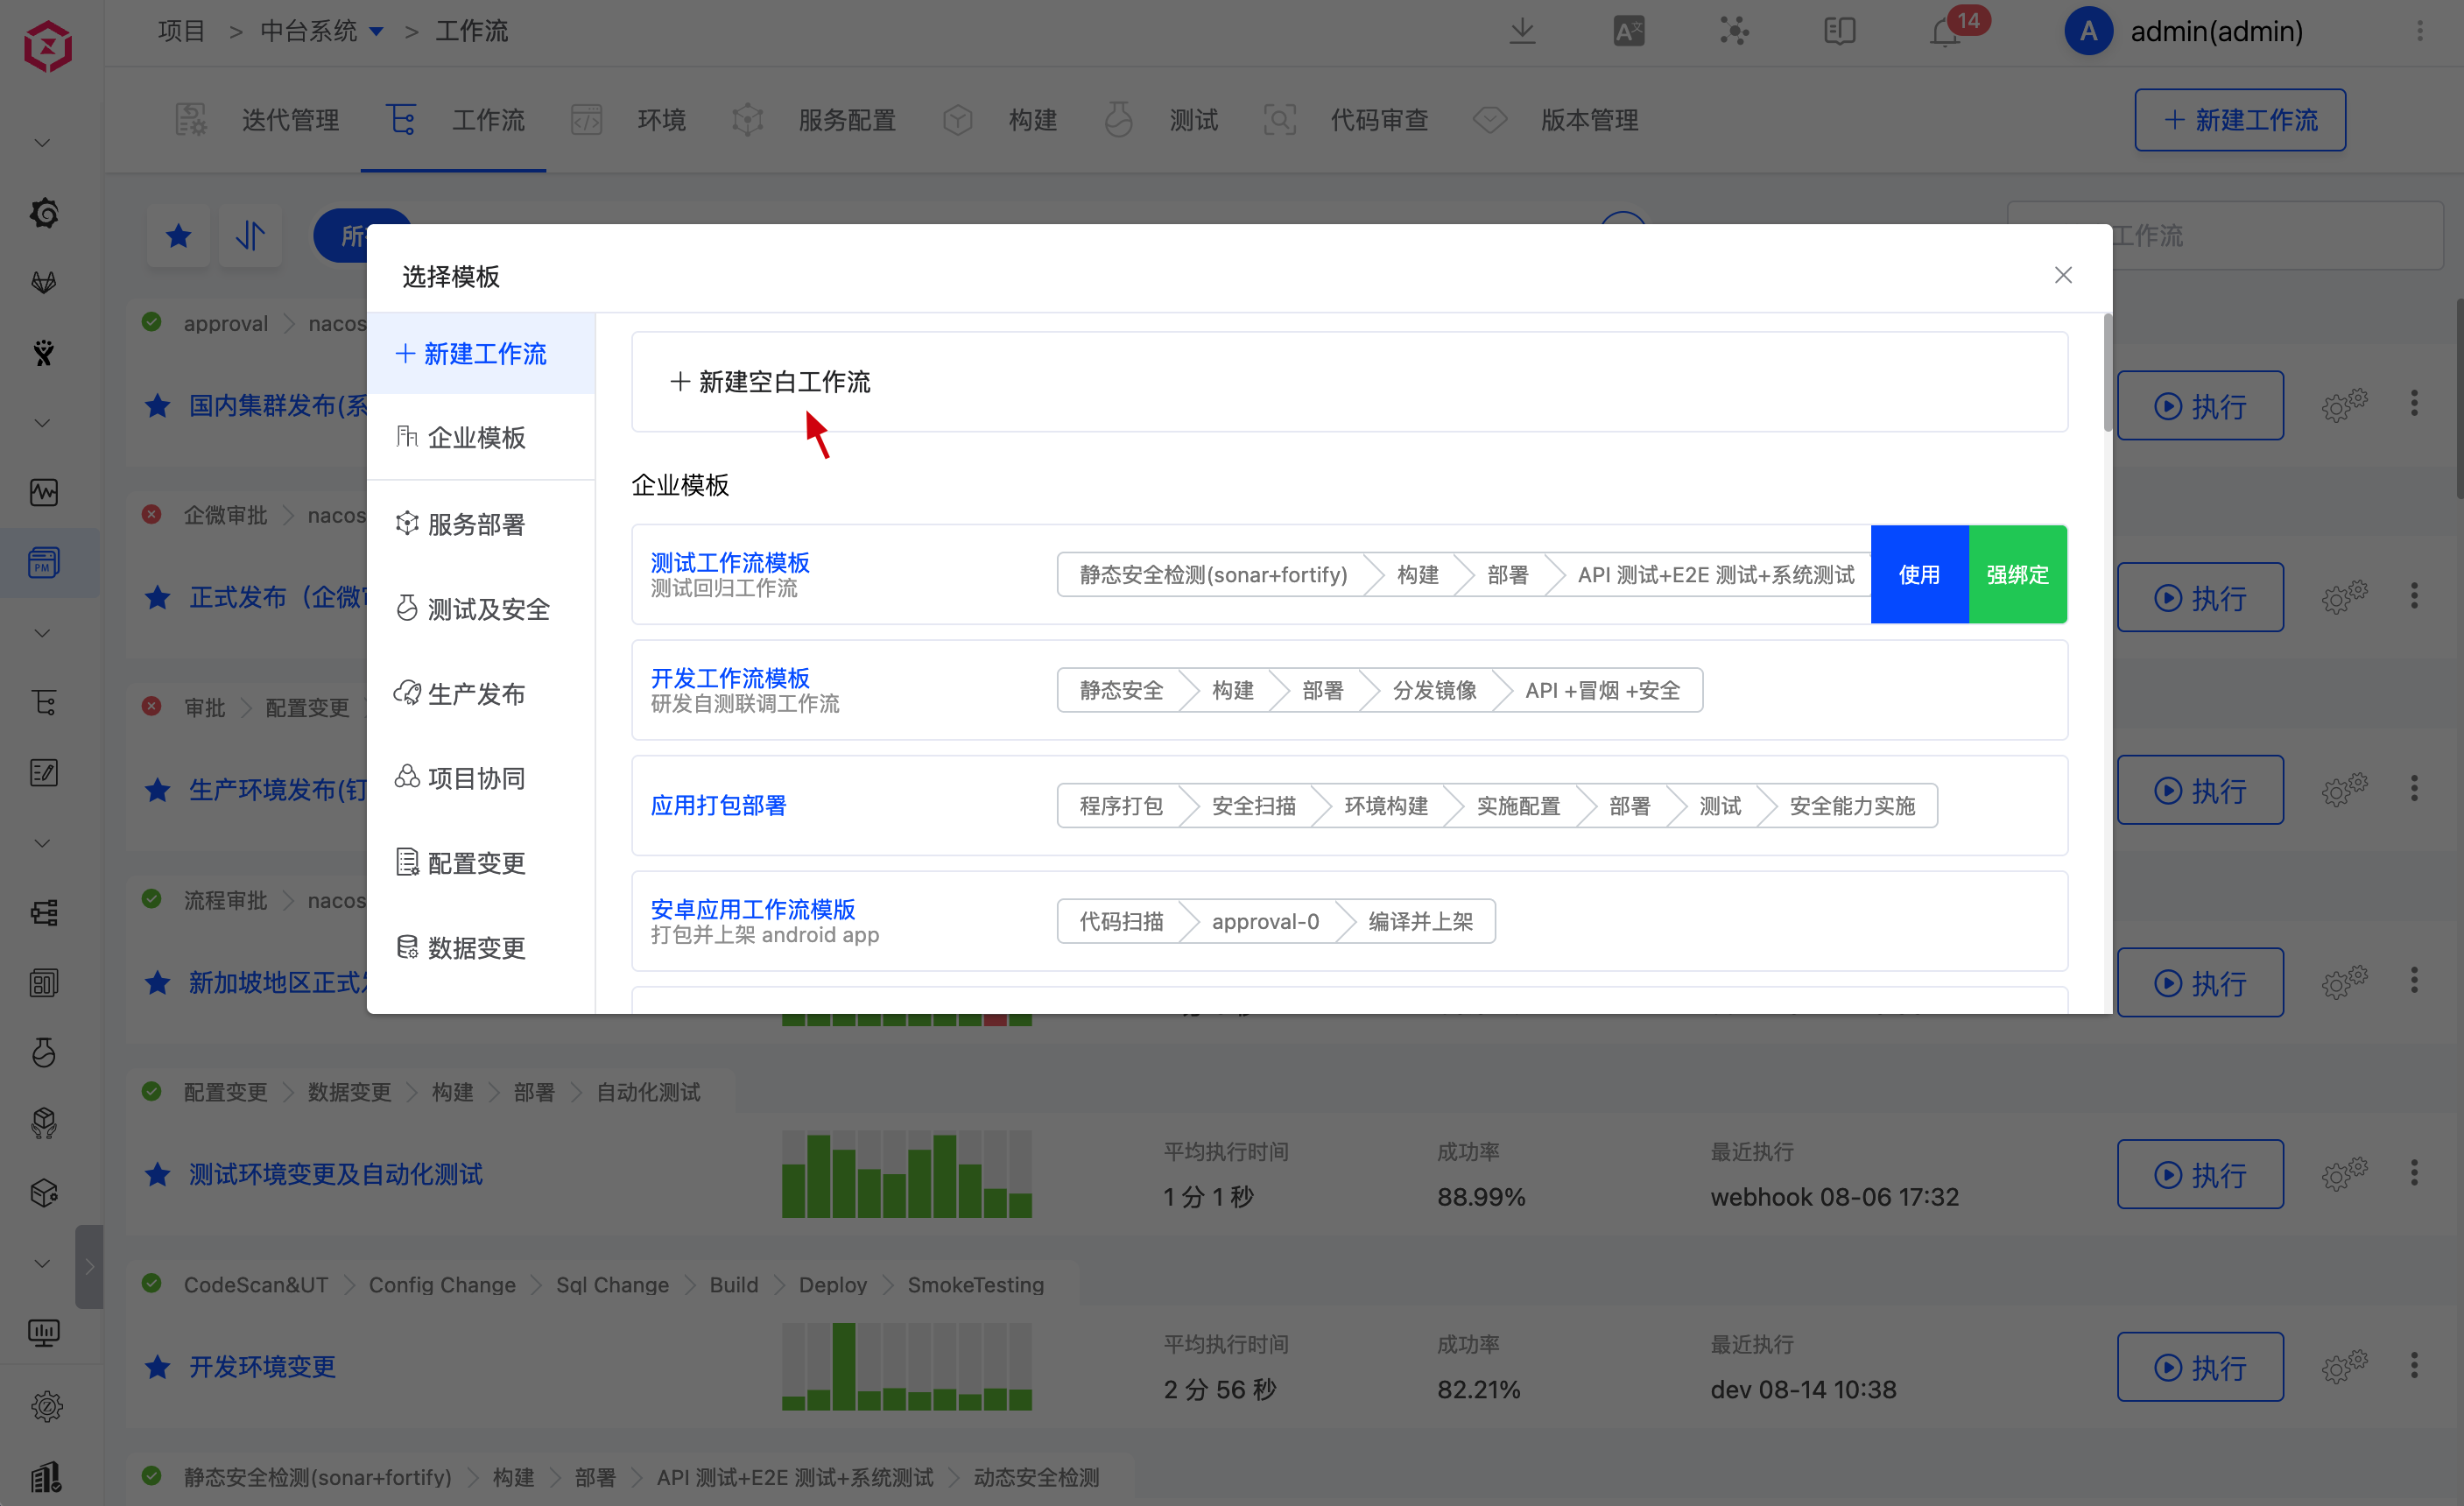
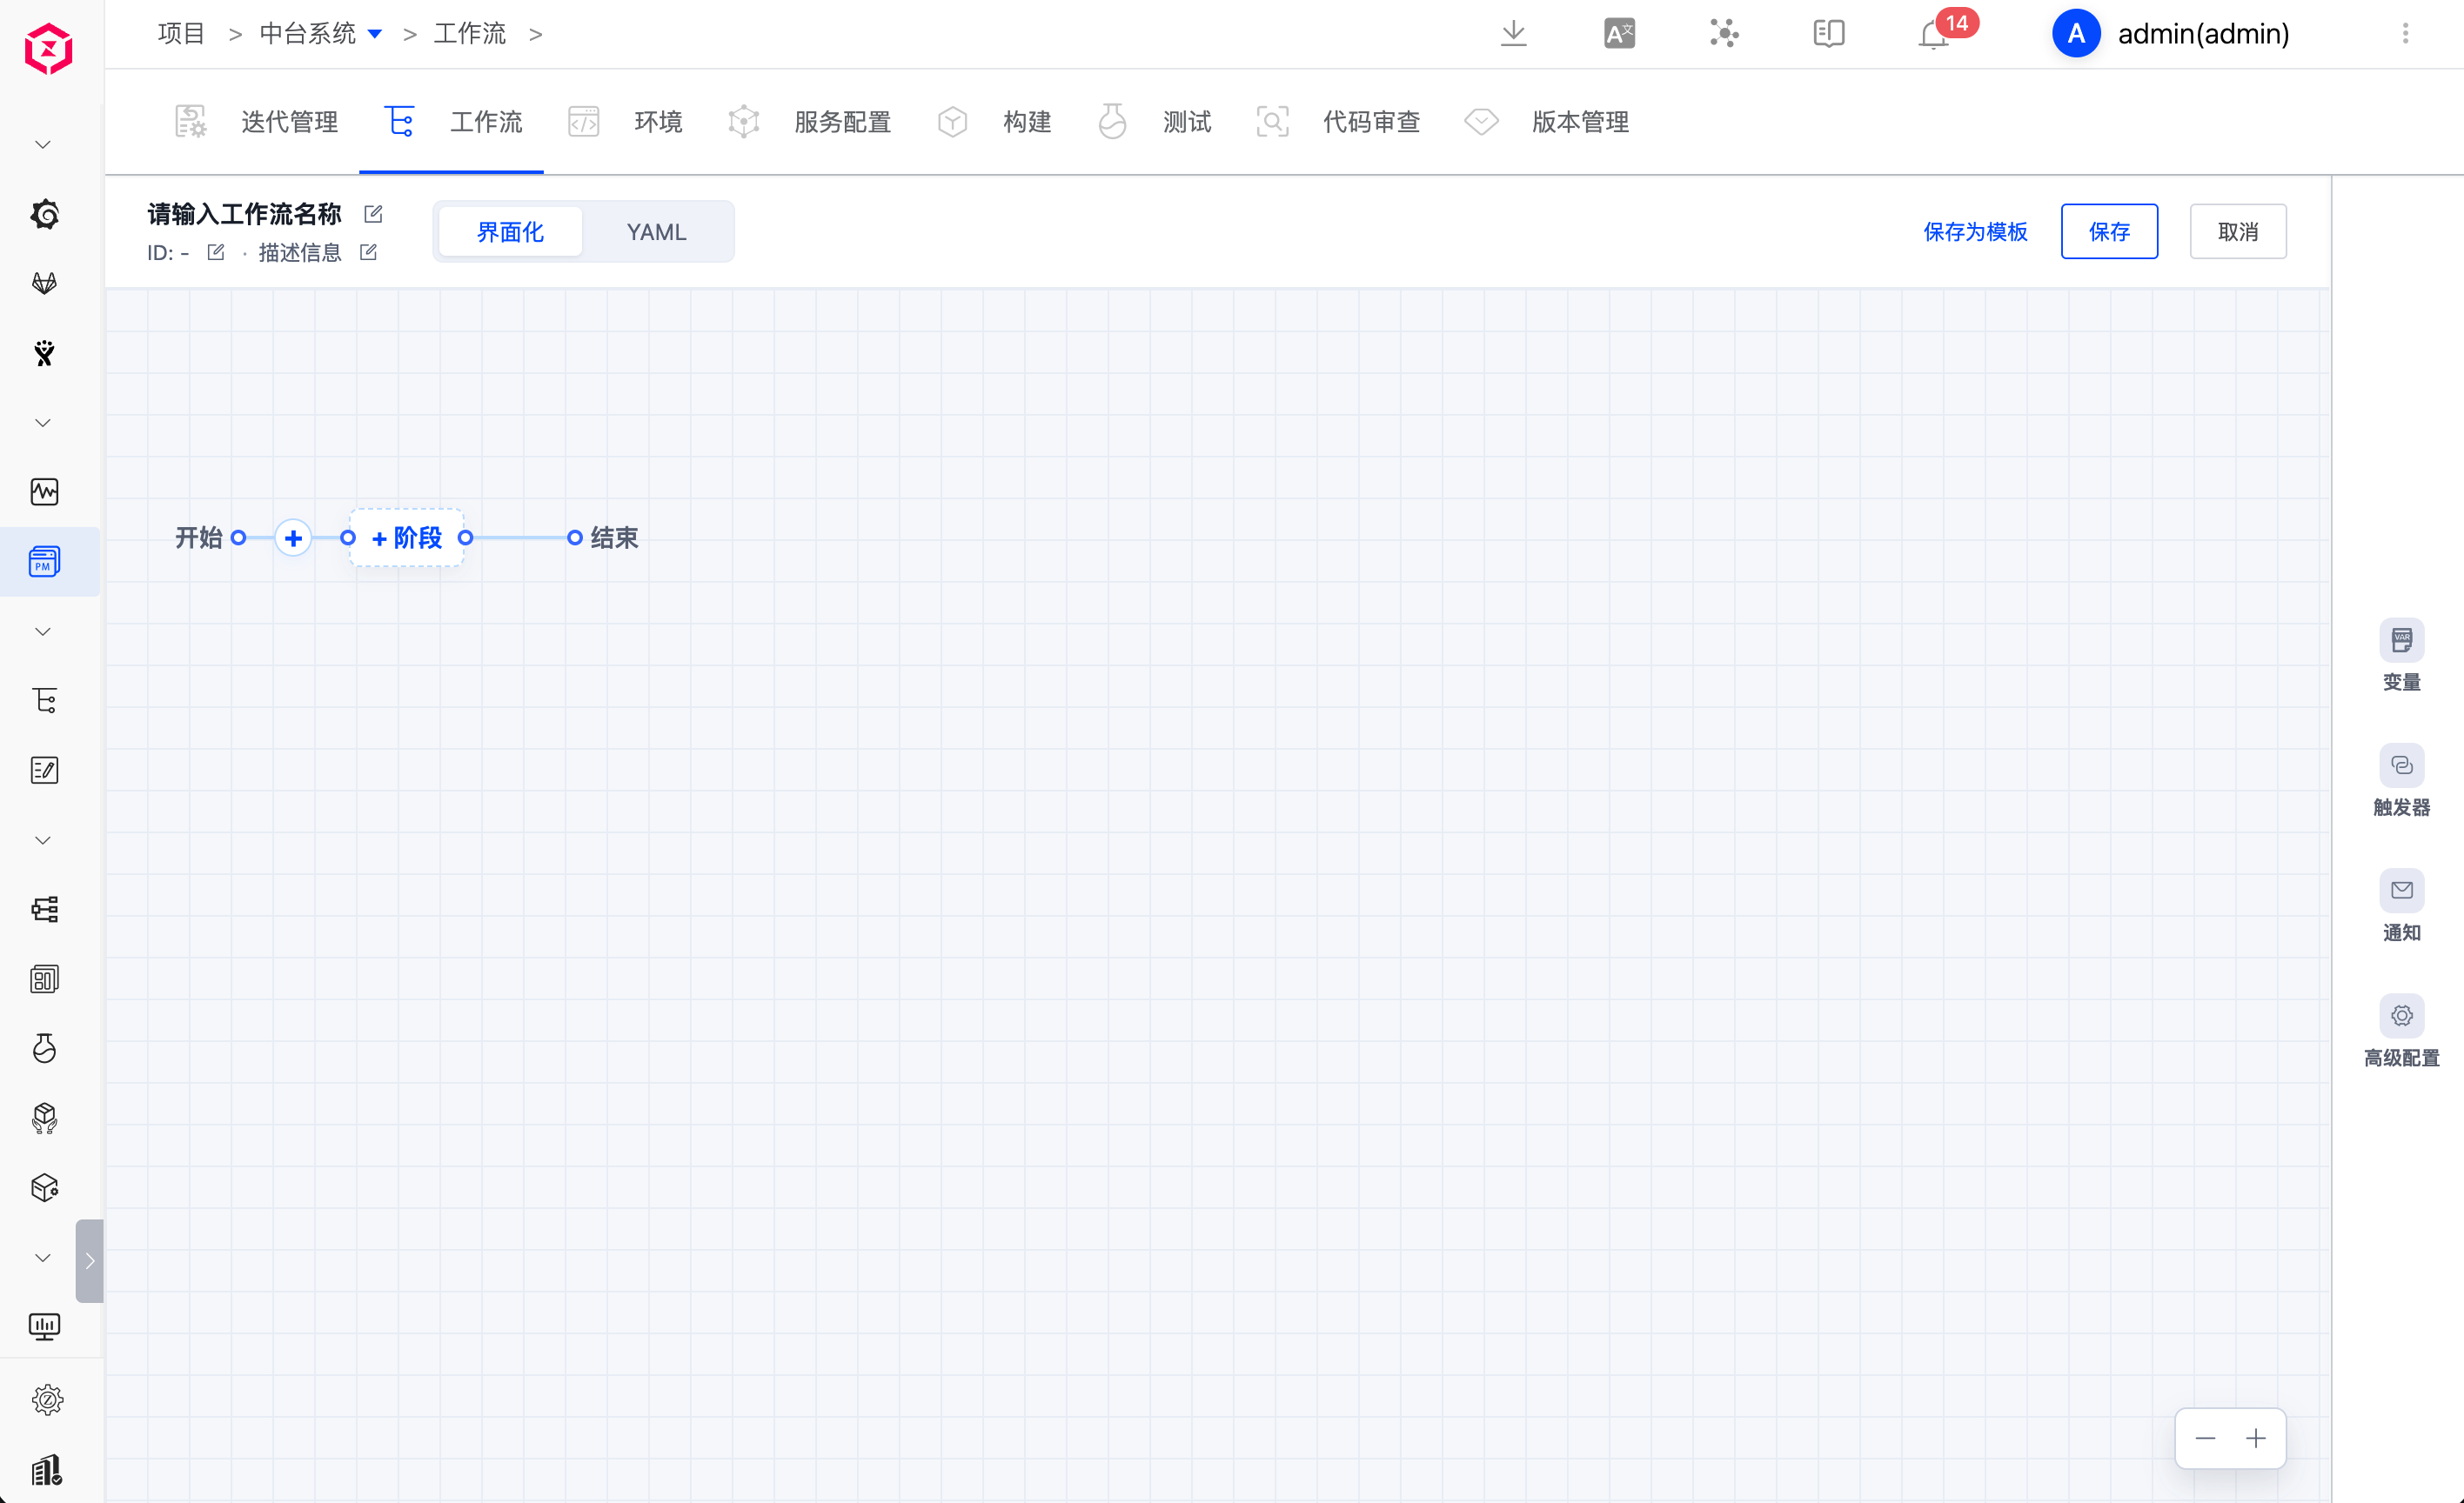
Enter a project and click Create Workflow. Zadig provides two configuration modes: GUI and YAML.
# Create from a Template
When creating a workflow, you can select a custom enterprise template or a system built-in workflow template, as shown below.
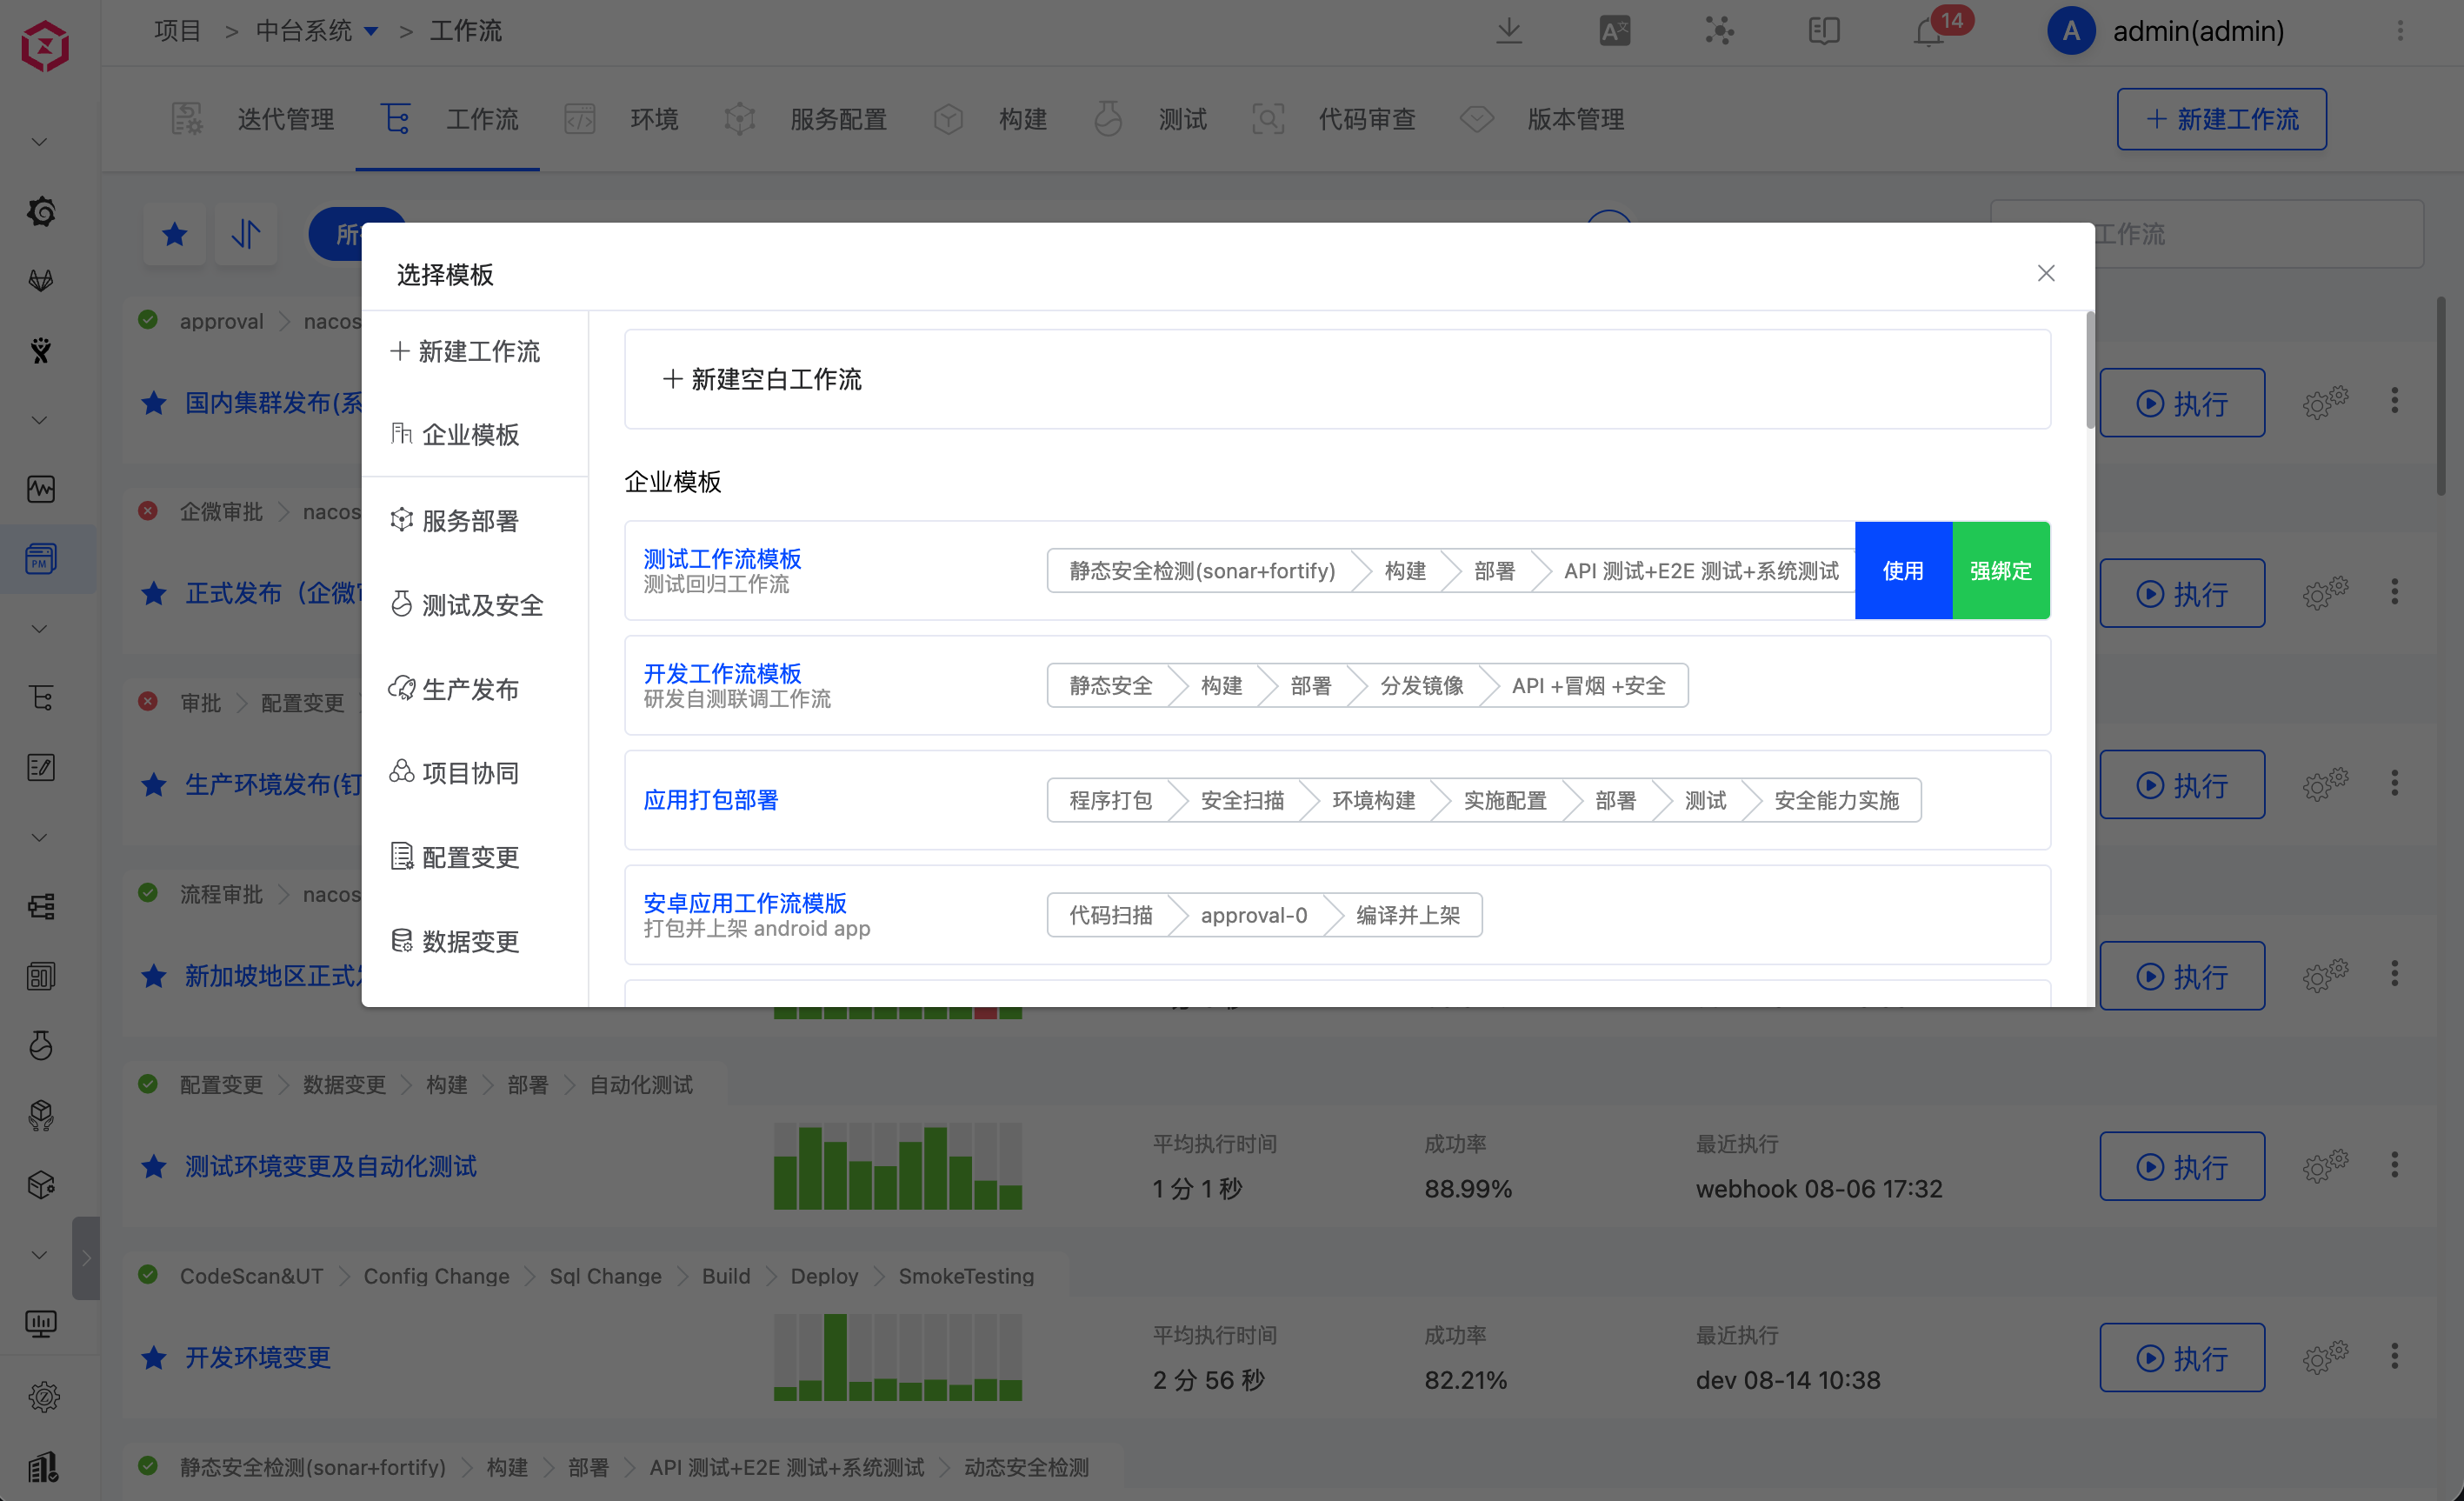
When you hover the mouse over a template card, you will see two options: "Use" and "Bind".
- Select "Use": This copies the template to create a regular workflow. After creation, you can freely adjust stages, jobs, and various settings. Subsequent changes to the template will no longer affect this workflow.
- Select "Bind": This creates a strongly bound workflow based on the template. After creation, the workflow is continuously managed by the template, making it suitable for scenarios where the enterprise needs standardized publishing, testing, or security scanning processes.
# Strong Binding
Strong binding is used to establish a persistent association between a workflow and a workflow template. After creating a strongly bound workflow, the structure of the workflow will be uniformly managed by the template, and project members only need to maintain project-specific configuration parameters.
After a strongly bound workflow is created, a "Managed" label will appear next to the workflow title in the editing page. Hovering over the label will show the name of the template the workflow is bound to.
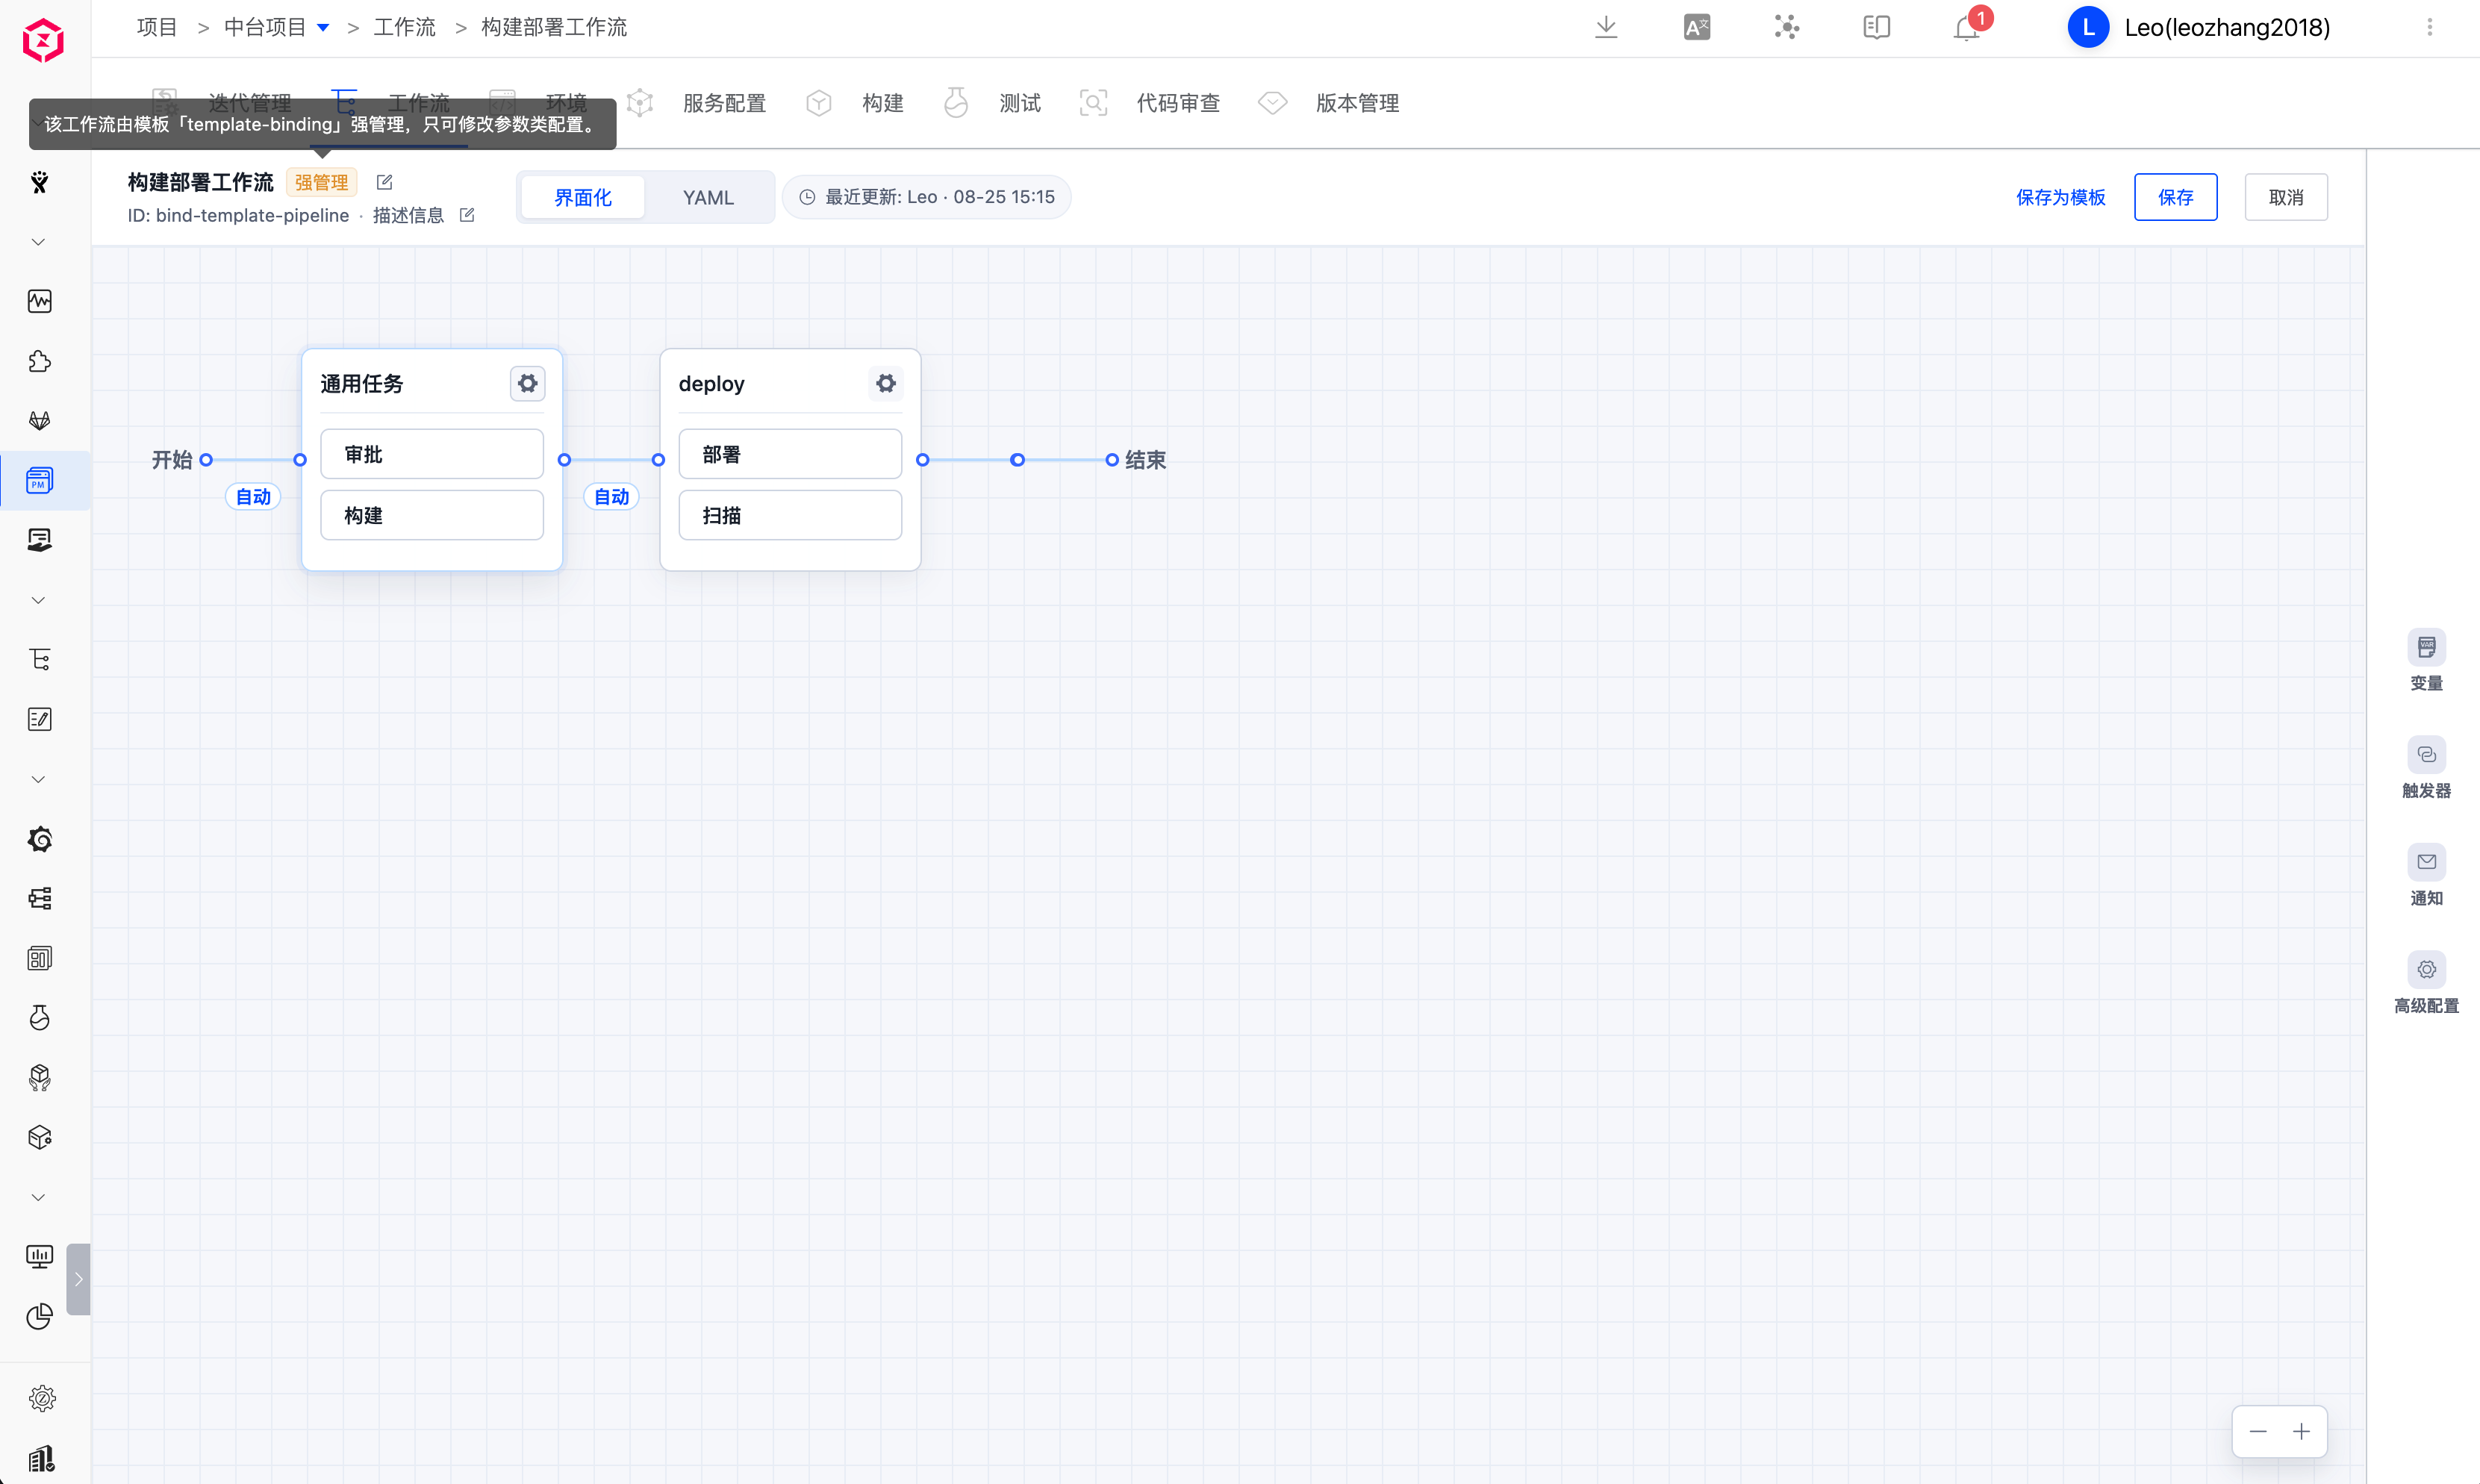
The following aspects of a strongly bound workflow can be modified:
- Basic information such as workflow name and description.
- Runtime configurations such as workflow parameters, shared storage, and concurrent execution settings.
- Parameter configurations of existing stages and jobs in the template, such as build settings, service deployment, environment, variables, approval, notification, and other execution-specific parameters.
The following structural changes are NOT supported in a strongly bound workflow:
- Adding or deleting stages.
- Adding or deleting jobs.
- Replacing the type of an existing job, or editing YAML in a way that causes the stage/job structure to differ from the template.
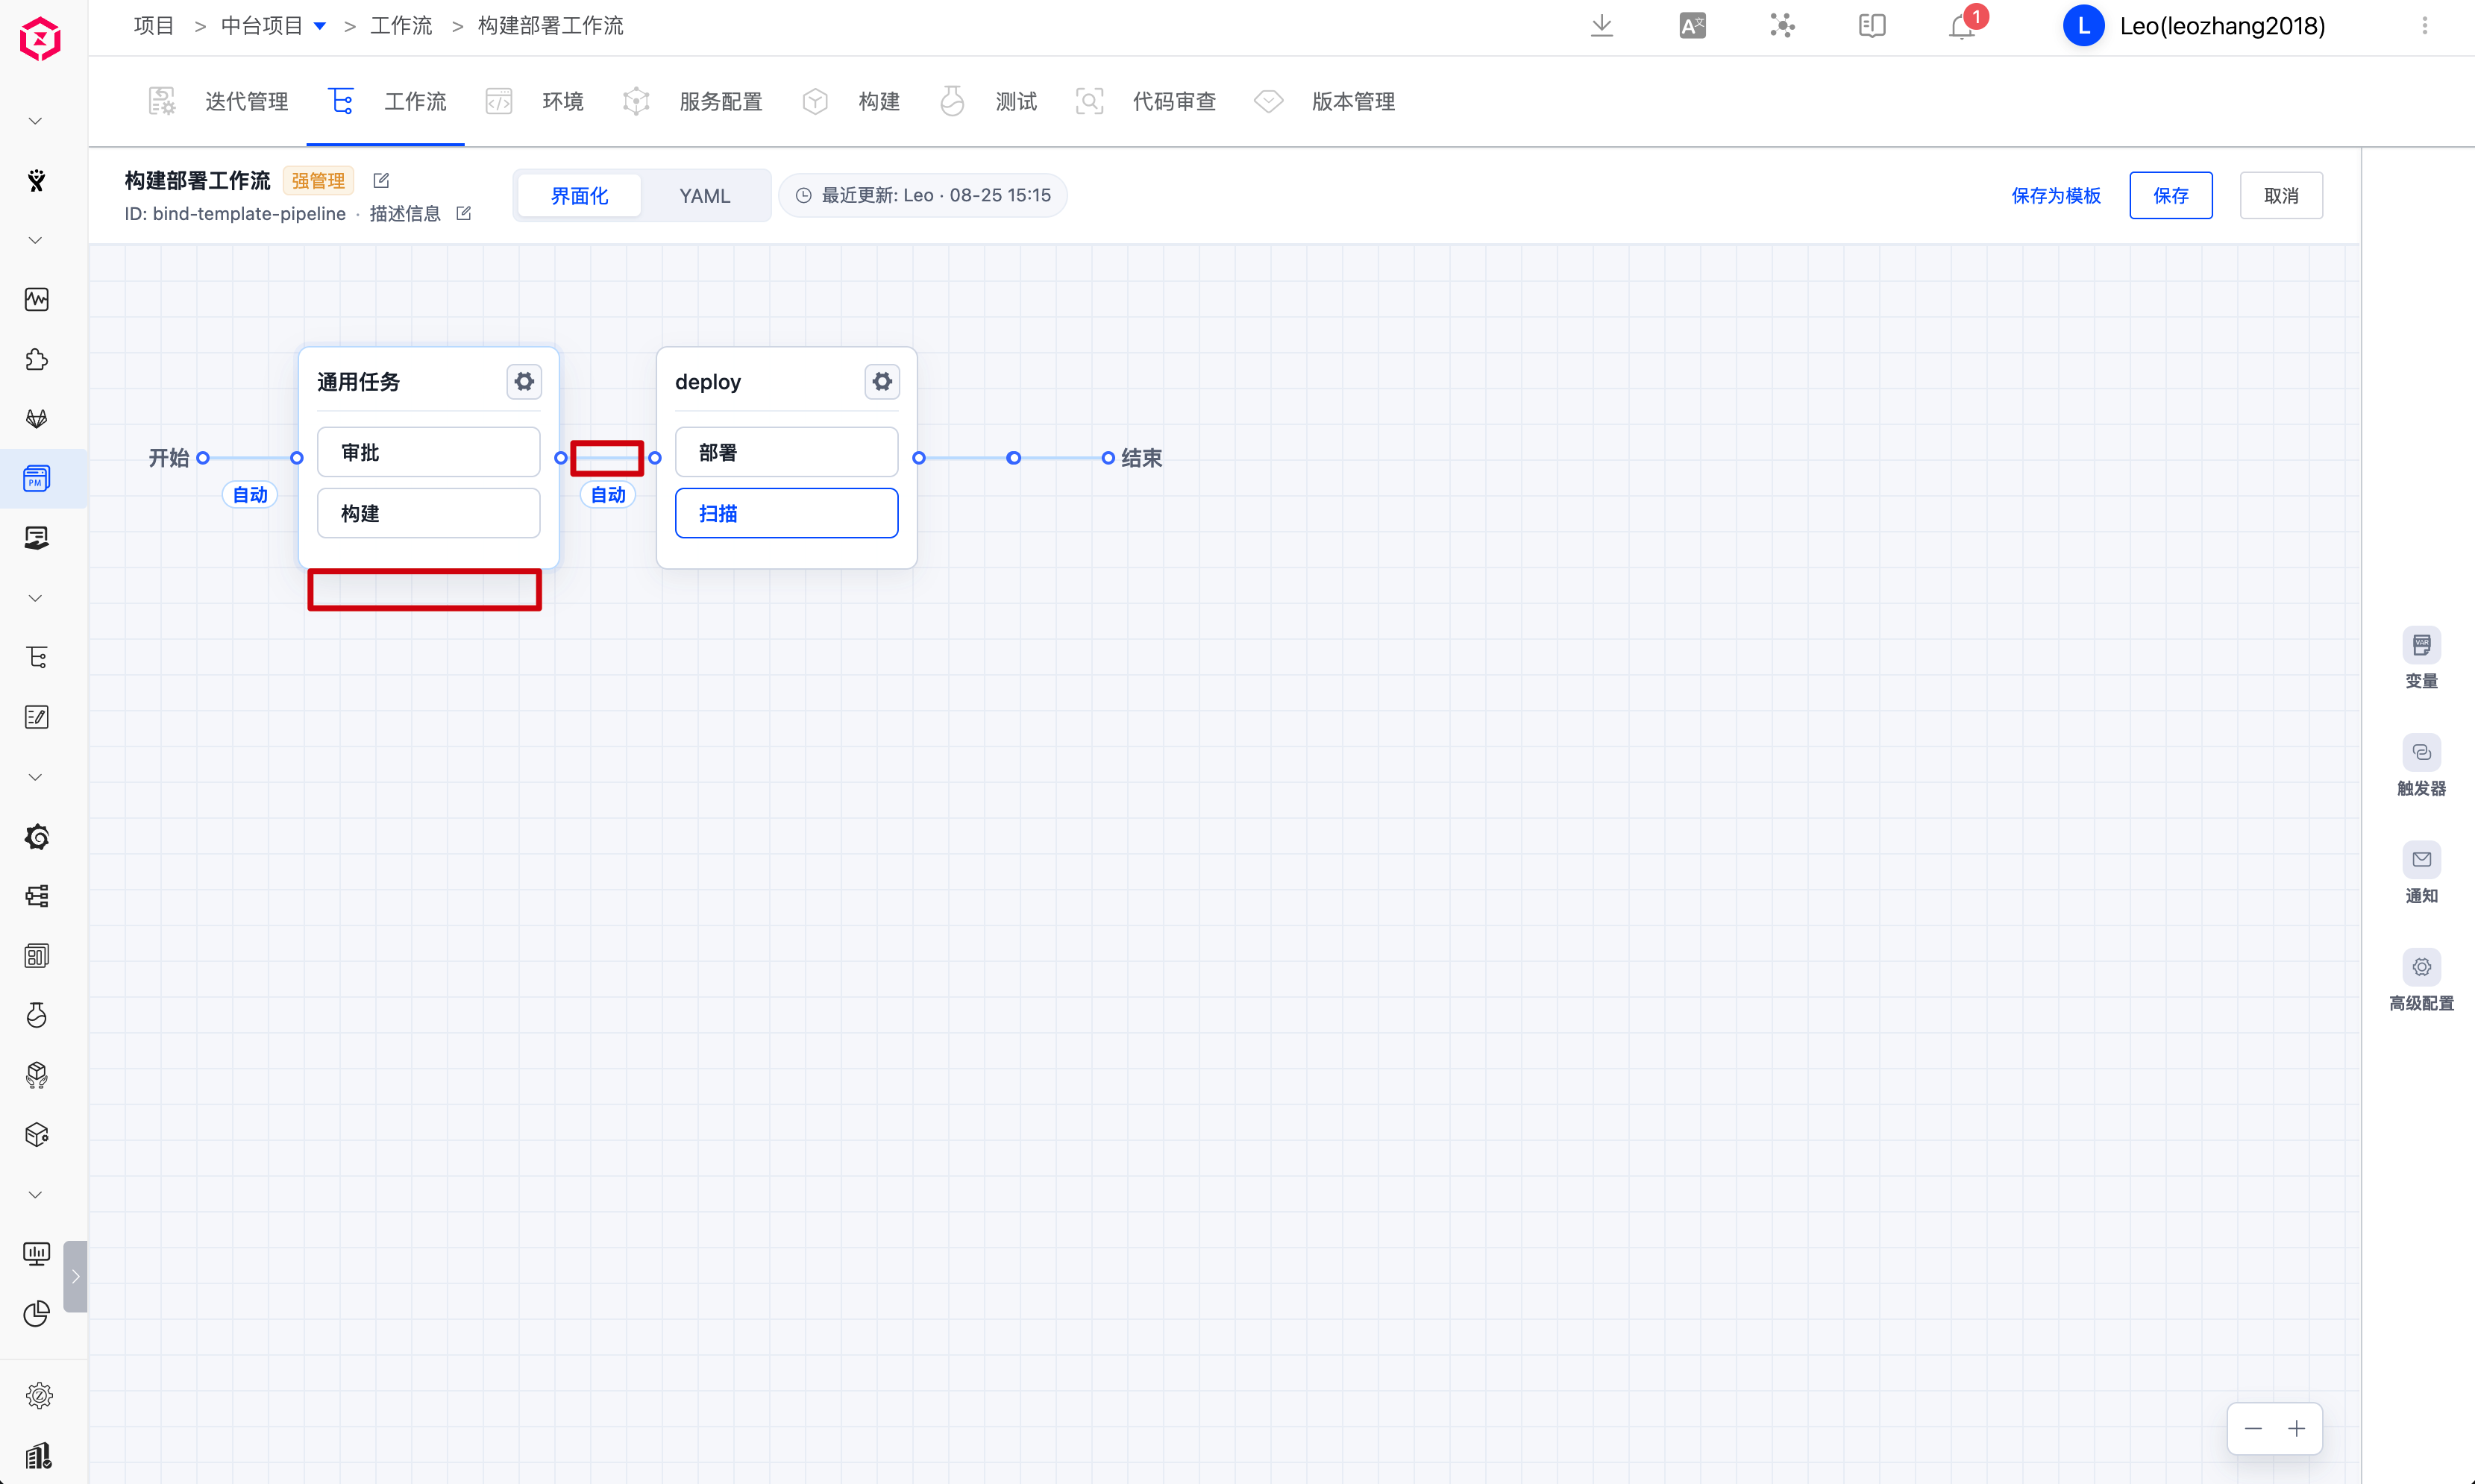
# Editing and Saving a Strongly Bound Workflow
To edit a strongly bound workflow, enter the workflow configuration page as usual, modify the necessary parameters, and click Save.
The system will automatically record the differences between the current workflow and the template. When the template is updated in the future, these differences will be used to determine whether the workflow can automatically inherit the template changes, or if manual conflict resolution is needed.
If you're editing the workflow via YAML, make sure not to add, delete, or replace stages or jobs.
# Template Upgrade Impact
When a workflow template is modified and saved, if it is referenced by any strongly bound workflows, the system will check the impact of the template upgrade on these workflows and display a "Template Upgrade Impact" dialog.
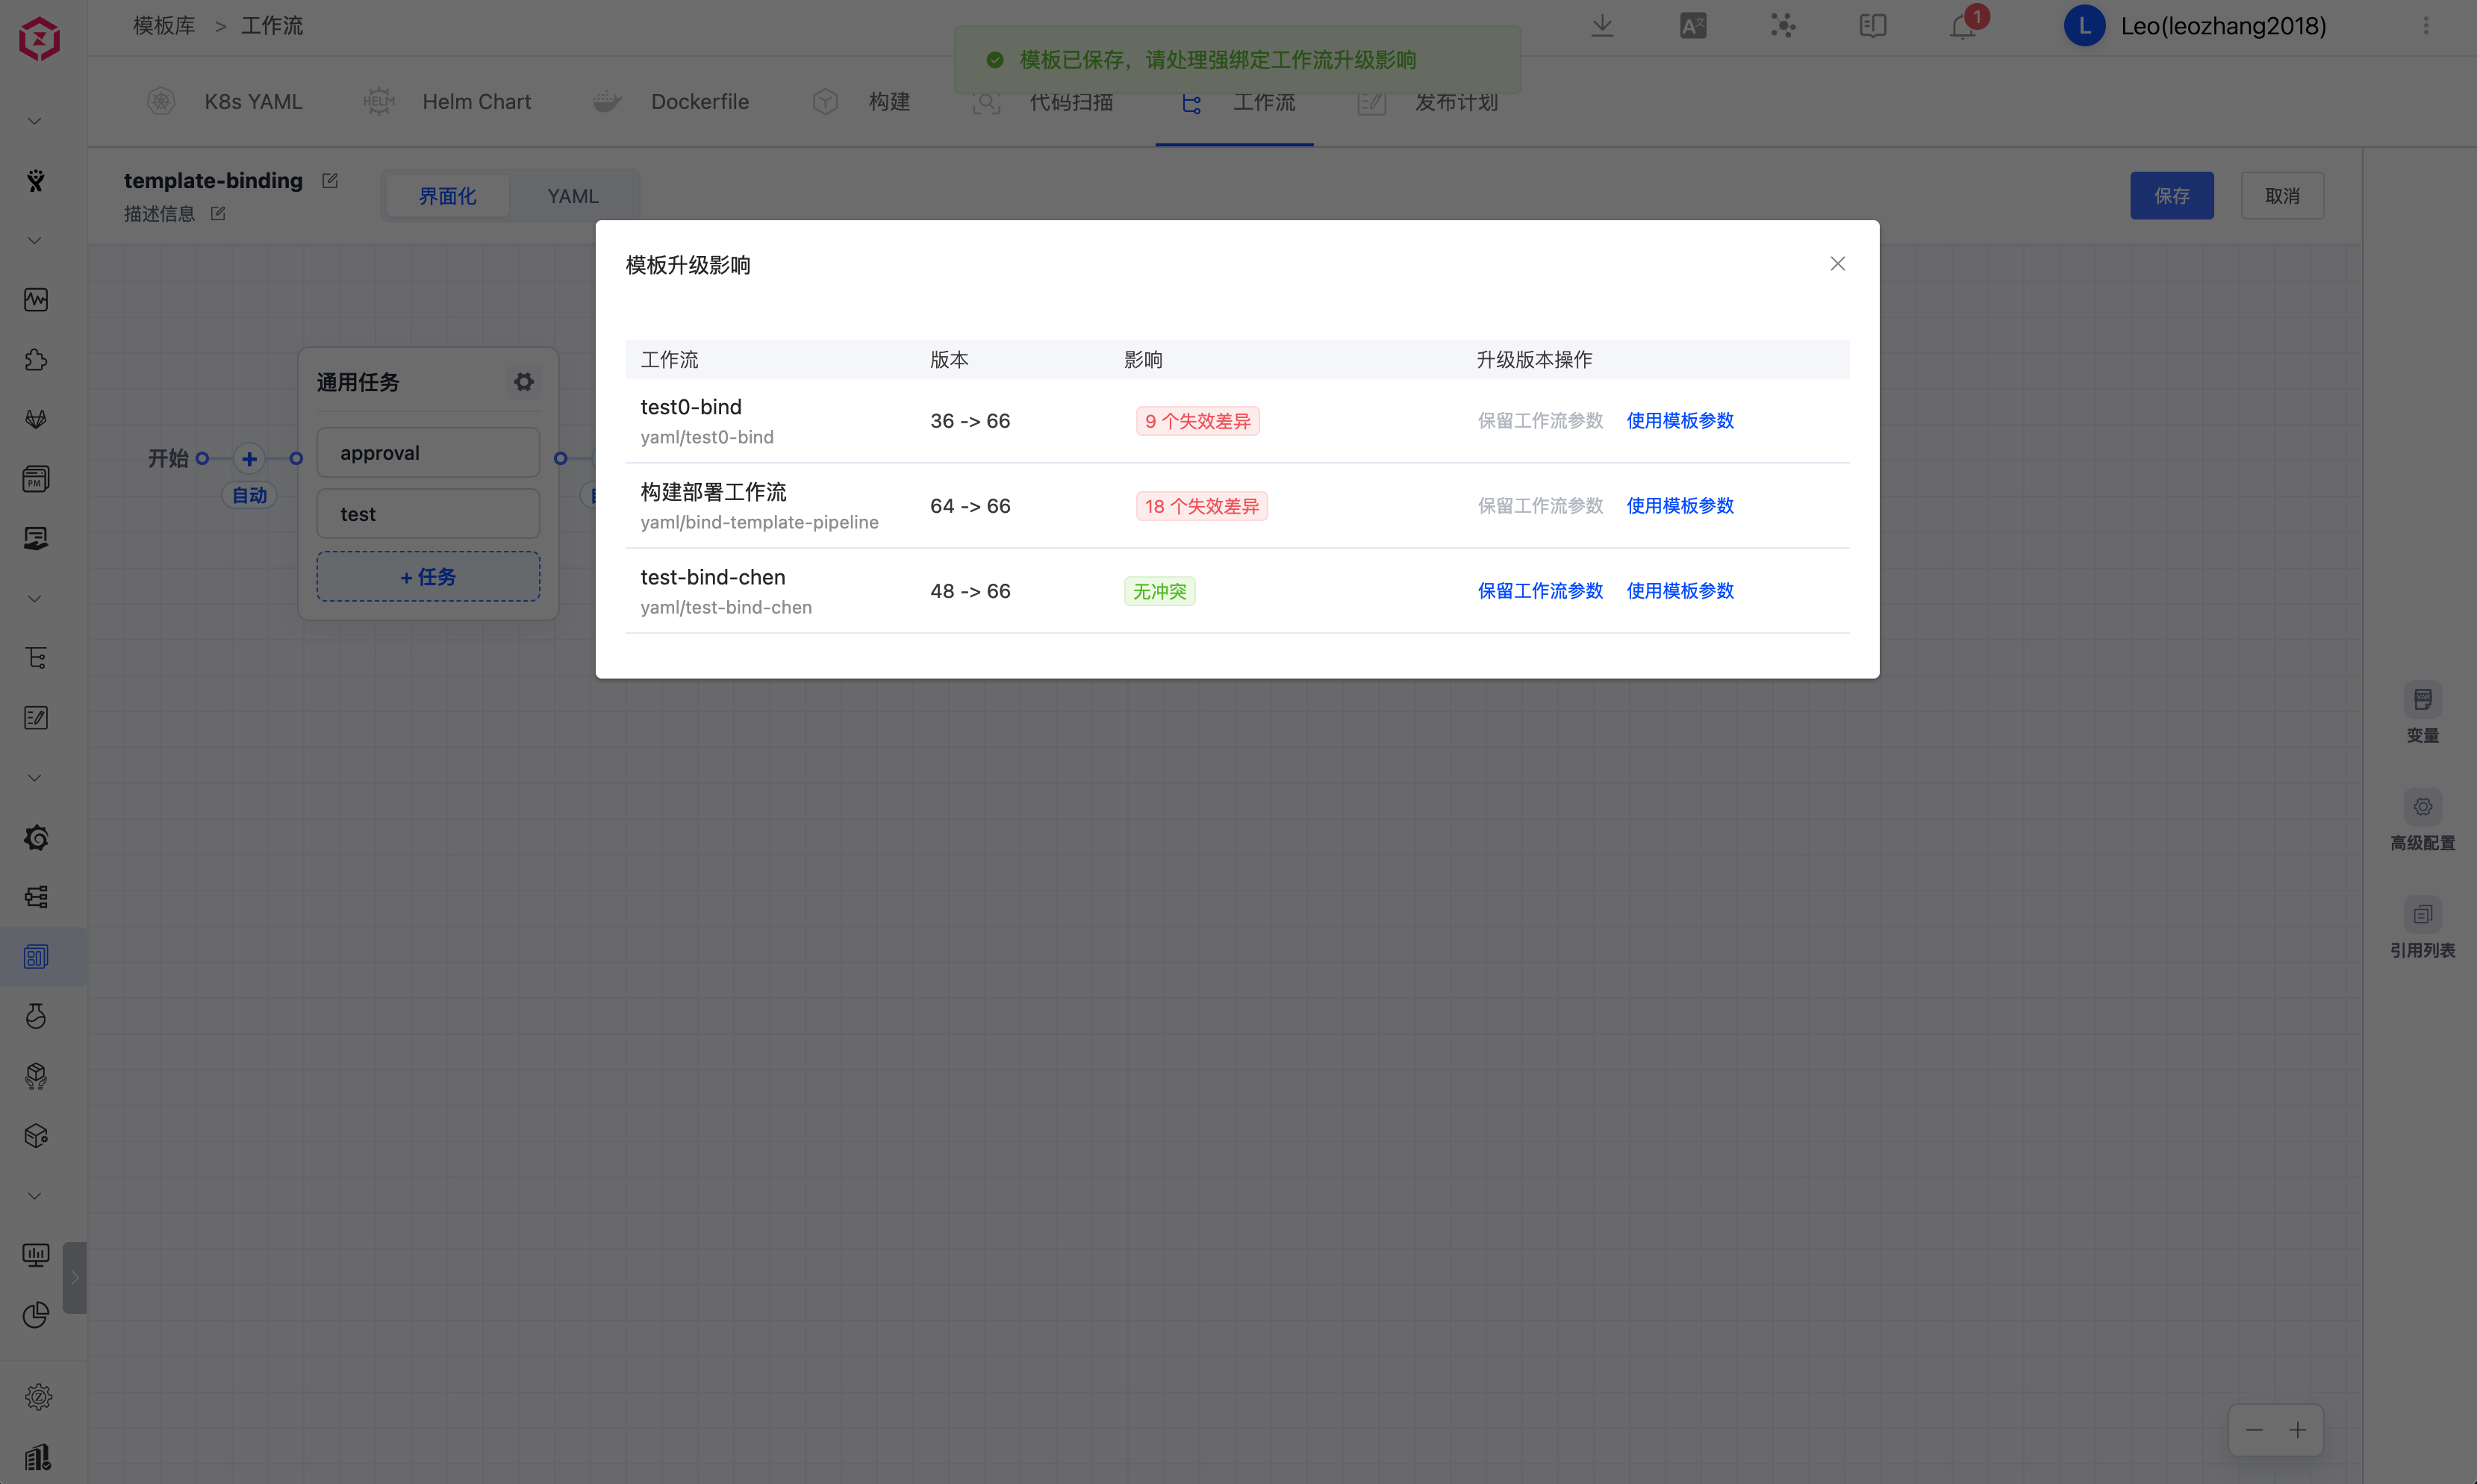
The dialog displays the following details:
- Workflow: The name and project of the affected strongly bound workflow.
- Version: The current template version bound to the workflow and the latest template version.
- Impact: Whether there are conflicts, invalid differences, or no conflicts.
- Upgrade actions: How to handle differences between the workflow and the new template version.
You can choose one of the following options:
- "Keep Workflow Parameters": Retain the workflow’s modified parameter configurations, merge the template changes into the workflow. Suitable when workflow parameters should be customized per project.
- "Use Template Parameters": Use the template’s latest configuration and discard local workflow parameter changes at conflict points. Suitable when the workflow needs to strictly follow the template standards.
If there are invalid differences, it means some customized differences in the workflow can no longer be applied to the new template version. In this case, you must use the template parameters or re-enter the workflow configuration to adjust as needed.
# Deleting Templates Referenced by Strongly Bound Workflows
When deleting a workflow template, if it is not referenced by any strongly bound workflows, the system will delete it as a regular template.
If the template is referenced by strongly bound workflows, the system will notify you which workflows are referencing the template and require confirmation for "force delete".
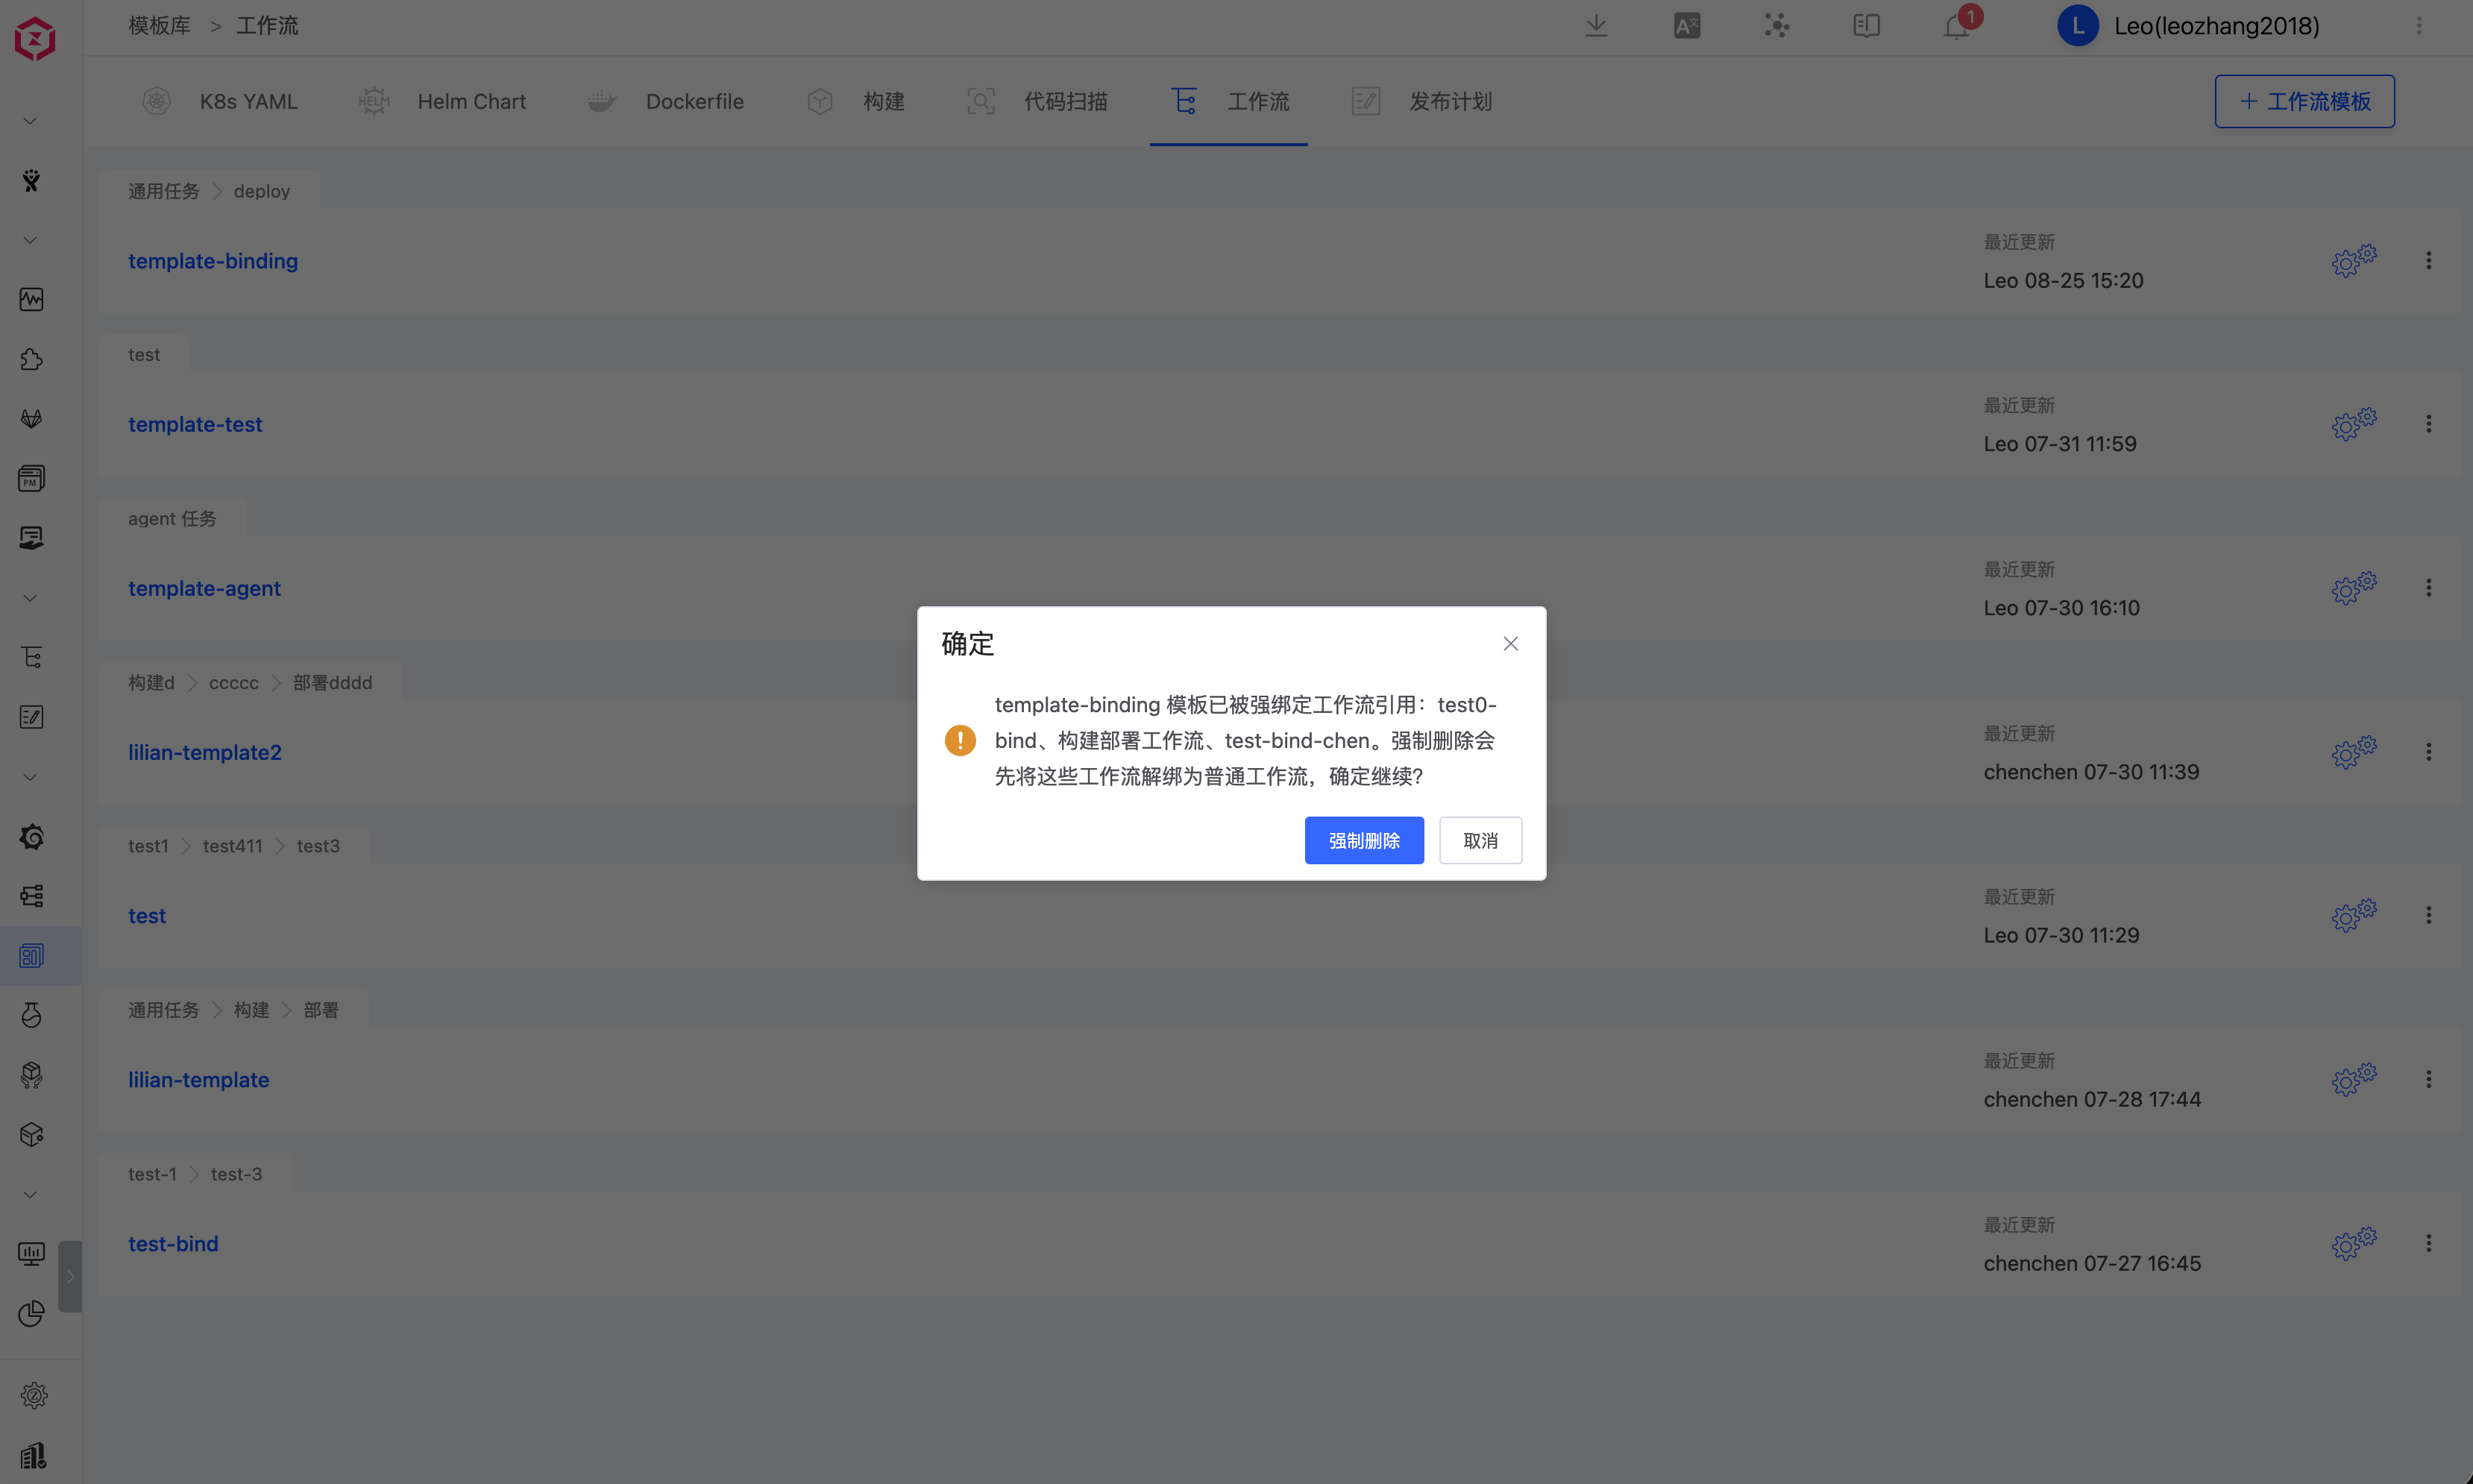
After confirming a force delete, the template will be deleted and any workflows that were strongly bound to it will be automatically unbound and converted into regular workflows. After unbinding, these workflows are no longer managed by the template and will not receive further template upgrades.
# Use Cases
Strong binding is recommended in the following scenarios:
- Enterprises need unified management of standard publishing, testing, or security scanning processes.
- Platform administrators want project workflows to continuously inherit template structure or default configurations after template upgrades.
- Project members only need to fill in execution parameters such as services, environments, variables, or approvers, and should not be able to arbitrarily modify the workflow structure.
If a project requires long-term flexibility to adjust workflow structure, it is recommended to use the regular "Use" option to create the workflow instead of strong binding.
# GUI Configuration
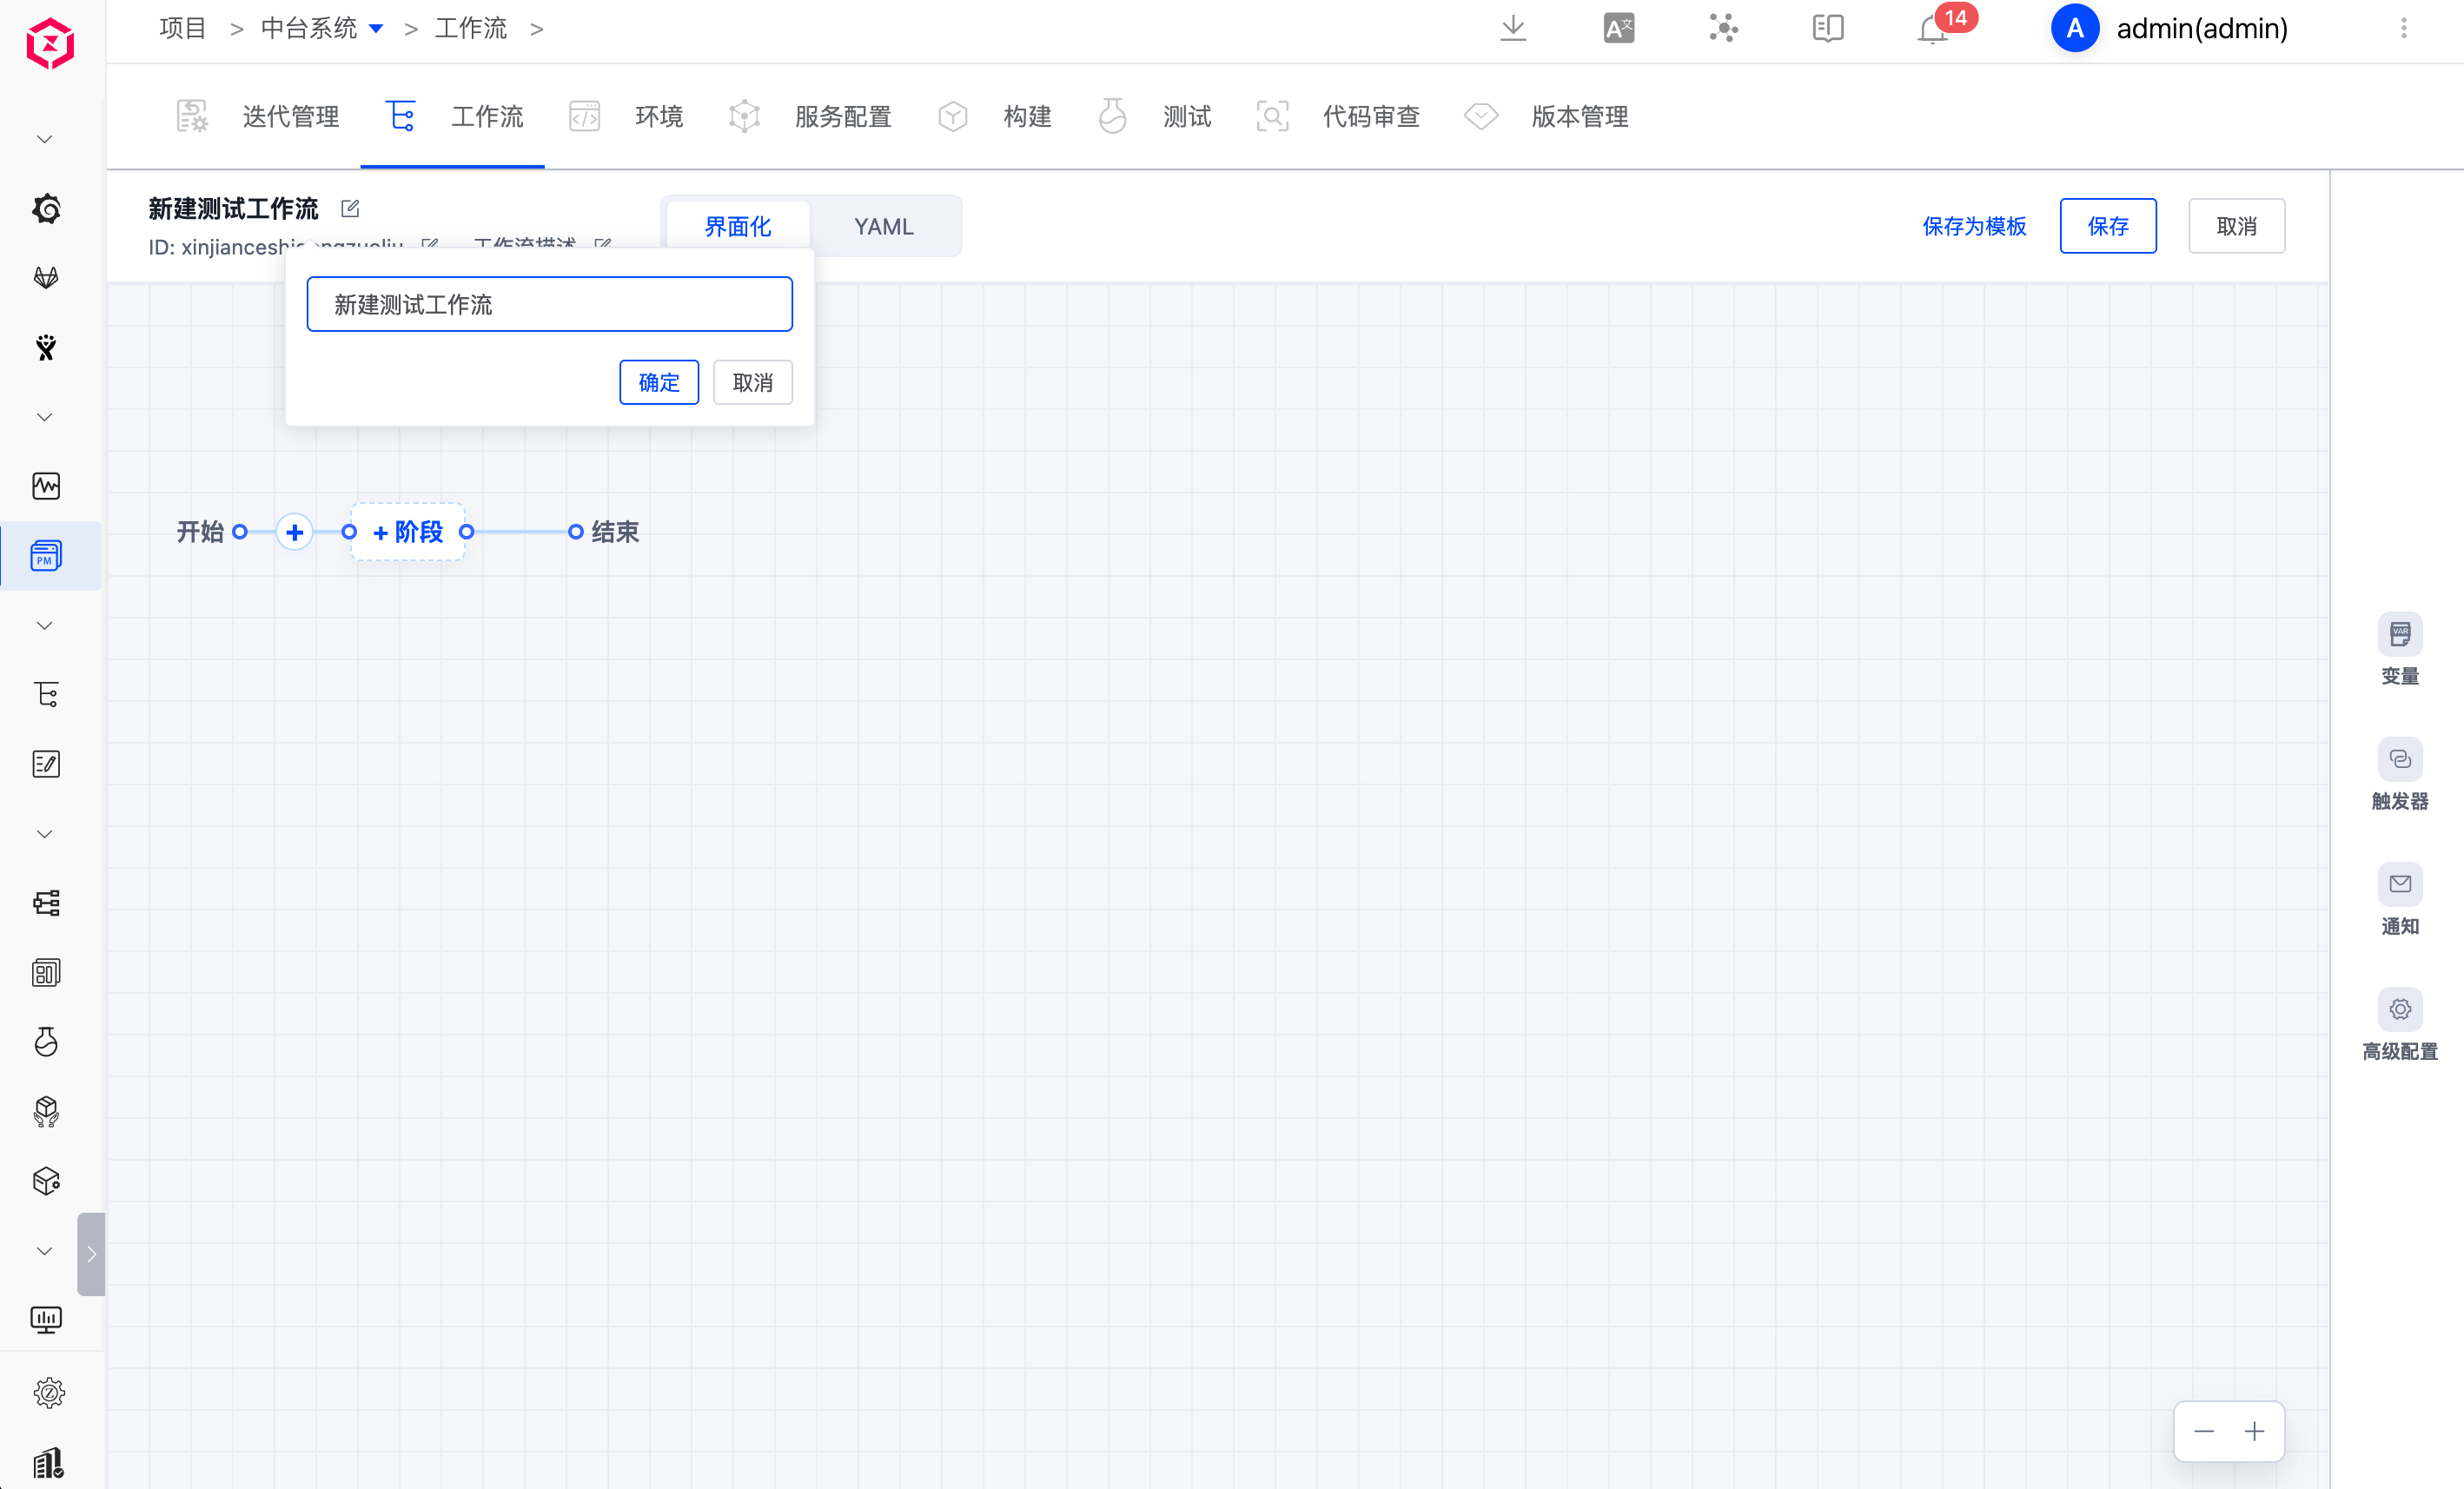
# Basic Information
Basic information includes the workflow name, identifier, and description:
Workflow Name: Supports Chinese characters, uppercase and lowercase letters, numbers, and special characters. It must be unique within the project and can be modified.Workflow Identifier: Supports uppercase and lowercase letters, numbers, and hyphens. It must be globally unique and cannot be modified.Description: Describes the workflow details and is displayed on the workflow details page.
# Stages
Click + Stage to add a new stage configuration.
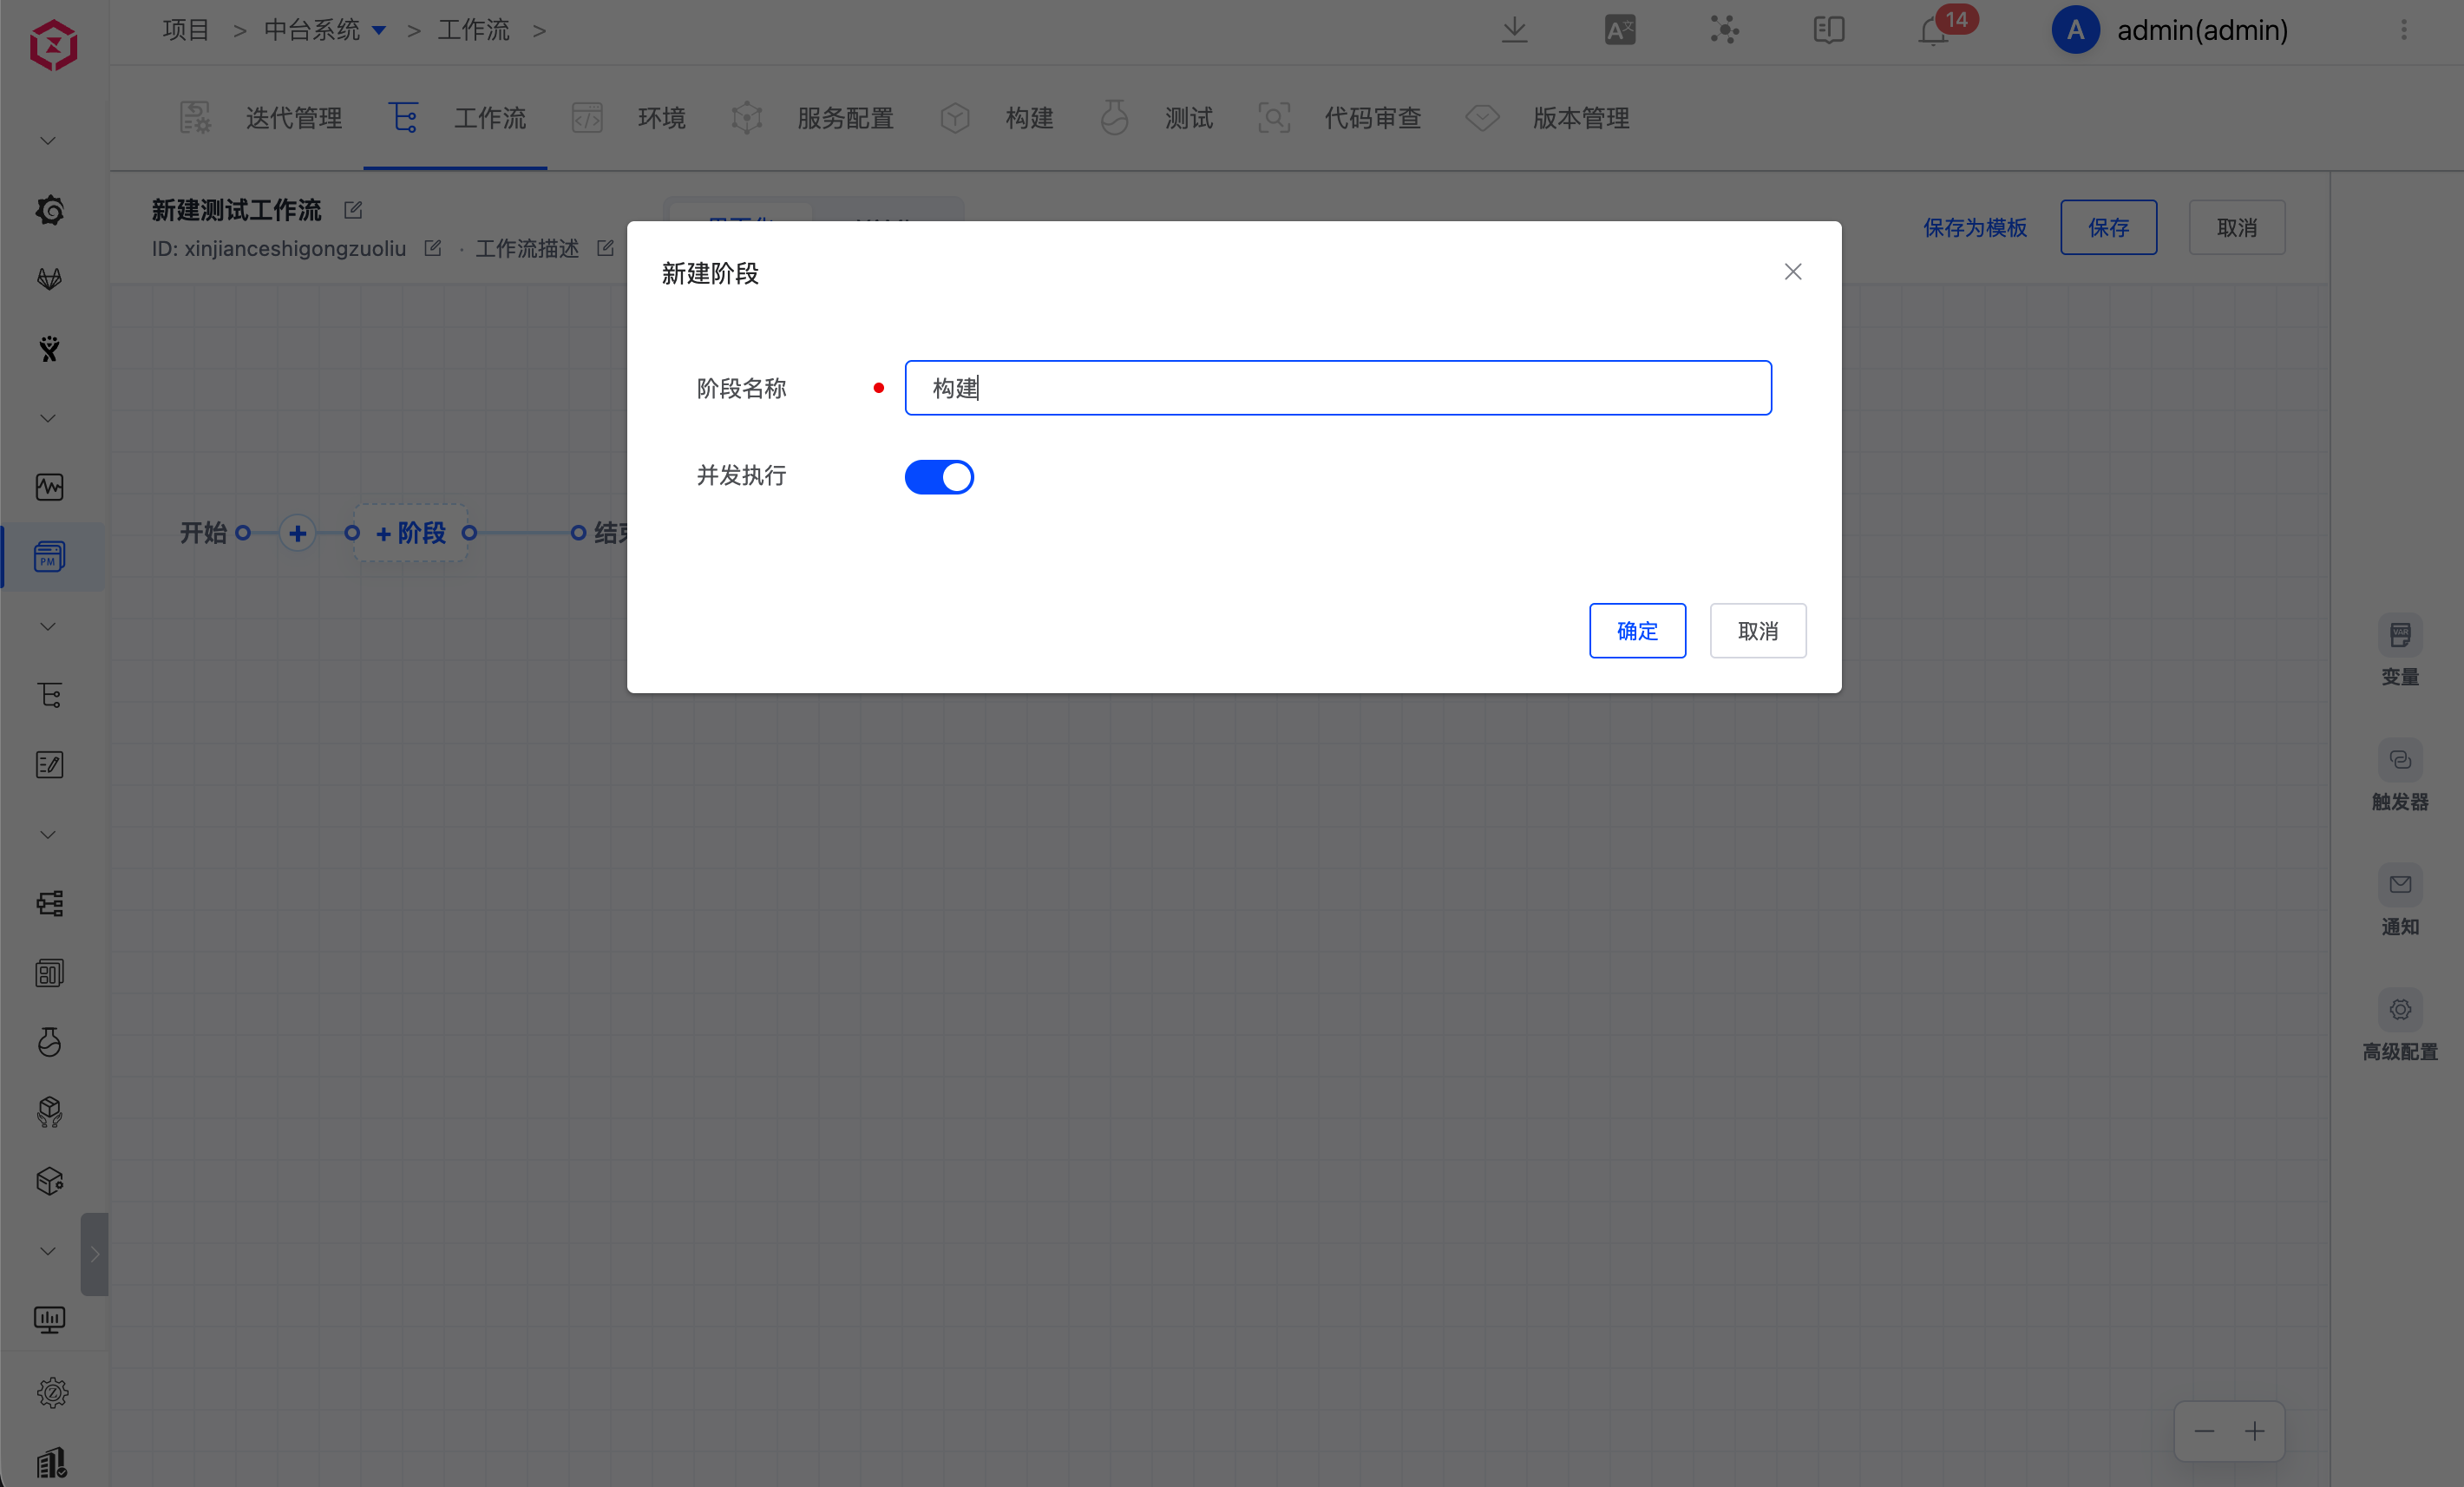
Parameter description:
Stage Name: The stage name must be unique within the same workflow.Concurrent Execution: When enabled, multiple jobs configured in this stage run concurrently.
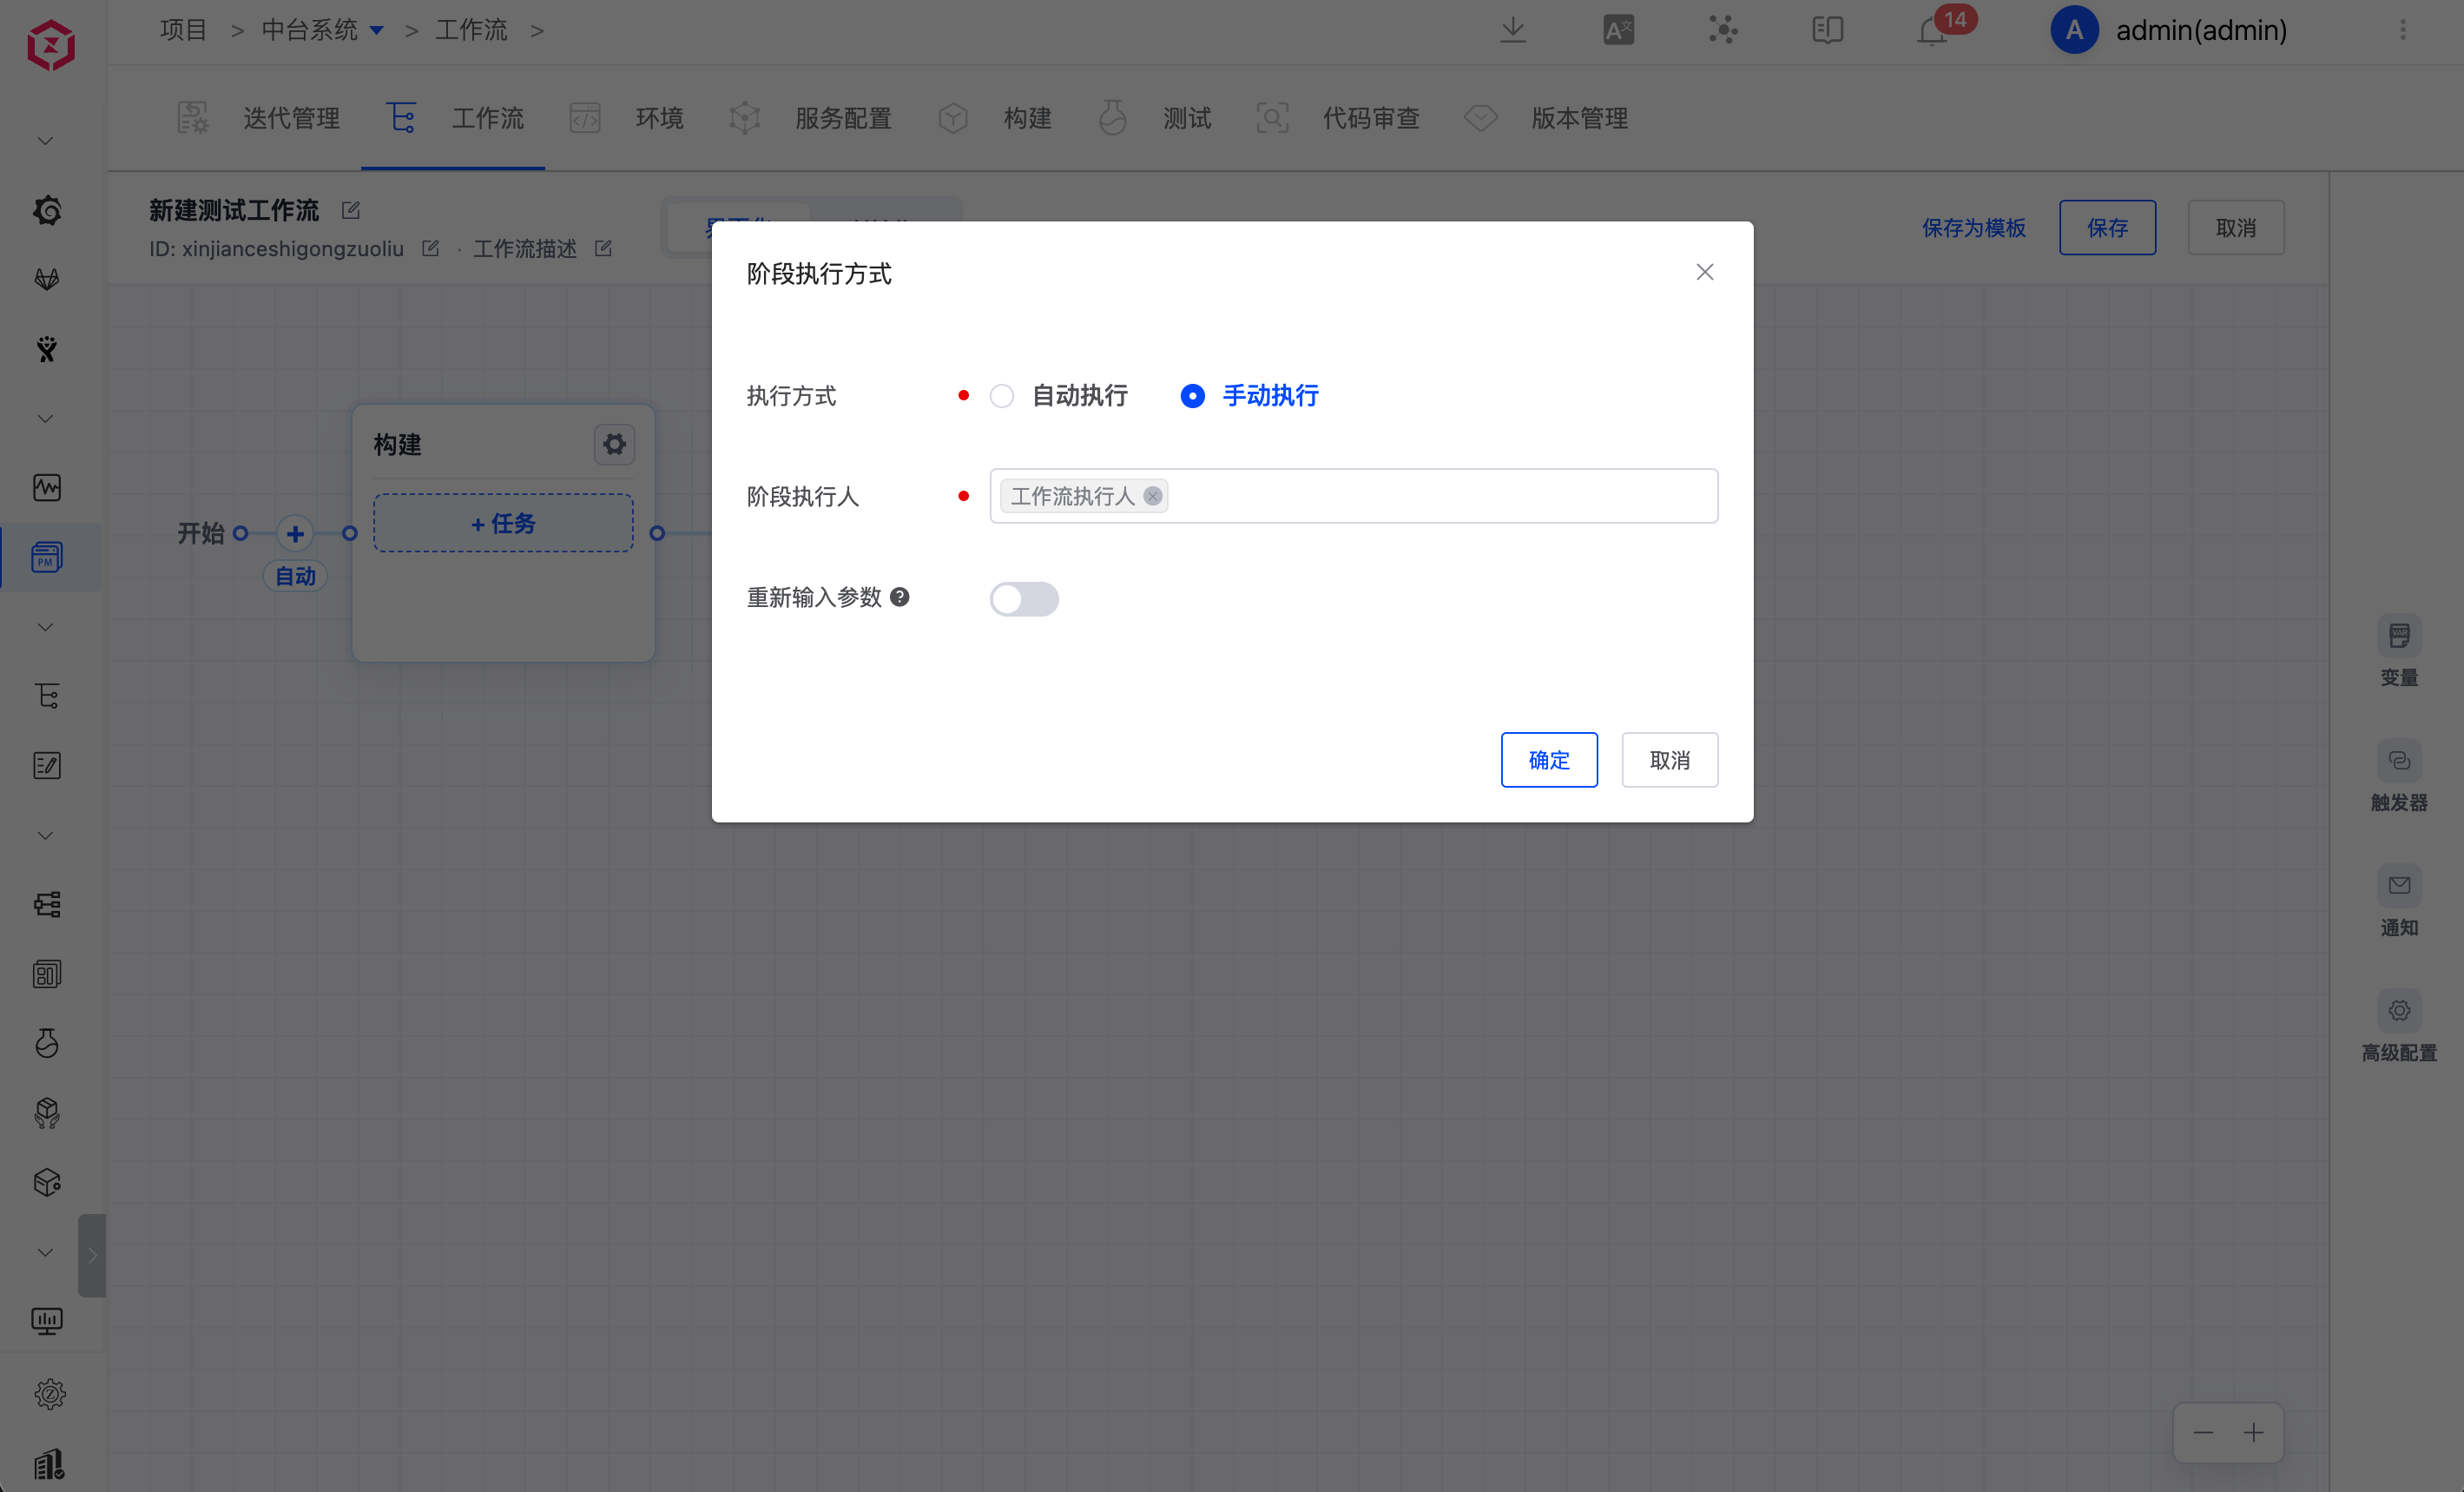
Stages support two execution modes: Automatic and Manual. Manual execution allows you to specify stage executors and re-enter job parameters during execution.
# Jobs
Click + Job under a stage to add a job configuration. For supported job types and detailed configuration, see Workflow Jobs.
# YAML Configuration
# Configuration Description
You can define a workflow using a YAML file. The overall YAML structure is described below:
display_name: <workflow name>       // Required. Unique within the project. Supports Chinese characters, uppercase and lowercase letters, numbers, and special characters.
name: <workflow identifier>         // Required. Unique within the project. Supports uppercase and lowercase letters, numbers, and hyphens.
stages:                            // Required. Multiple stages are executed in sequence.
  - <stage 1 configuration>
  - <stage 2 configuration>
  - <more stage configurations...>
project: <project name>            // Required.
description: <workflow description>
multi_run: <optional: true/false>  // Whether multiple workflow tasks can run in parallel when the workflow is triggered multiple times simultaneously. Default: false.
2
3
4
5
6
7
8
9
The detailed configuration of each stage is as follows:
name: <stage name>               // Required.
parallel: <optional: true/false> // Whether multiple jobs in this stage can run concurrently. Default: false.
jobs:                            // Required.
  - <job 1 configuration>
  - <job 2 configuration>
  - <more job configurations...>
2
3
4
5
6
Currently, two built-in job types are available: build and deploy. The detailed configuration of a build job is as follows:
Build variables set in YAML take effect only when related build variables are configured in the specified build.
name: <job name>                     // Required.
type: zadig-build                    // Required. Set to zadig-build.
spec:                                // Required.
  docker_registry_id: <image registry ID>
  service_and_builds:                // Build information of service modules. Multiple service modules can be configured.
    - service_module: <service module name>
      service_name: <service name>
      build_name: <build name>
      key_vals:                      // Build variable information. String and choice variables are supported. See the string and choice examples below.
        - key: username              // Build variable name.
          value: Zadig               // Build variable value.
          is_credential: false       // Whether the value is encrypted. Default: false.
          type: string
        - key: password
          value: v1
          is_credential: false
          type: choice
          choice_option:             // Options for the choice variable.
            - v1
            - v2
    - service_module: <service module name>  // More service module build information.
      service_name: <service name>
      build_name: <build name>
      ...
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
The detailed configuration of the built-in deploy job is as follows:
name: <job name>                     // Required.
type: zadig-deploy                   // Set to zadig-deploy.
spec:
  env: <deployment environment>      // Required.
  source: <service image source used for deployment>  // Required. Options: runtime (runtime input) / fromjob (output from another job).
  job_name: <job name>               // Required when source is fromjob.
2
3
4
5
6
# YAML Example
Take the following workflow configuration as an example:
- The first stage contains a build job and builds two services (
myapp-1andmyapp-2) in parallel. - The second stage contains a deploy job and uses the image artifacts from the build job above to deploy the
pre-releaseenvironment.
The corresponding complete YAML configuration example is as follows:
name: pre-release-deploy
display_name: pre-release-deploy
stages:
  - name: build
    parallel: true
    jobs:
      - name: build-myapps
        type: zadig-build
        spec:
          docker_registry_id: 6247eb0832a15f910118318c
          service_and_builds:
            - build_name: simple-service-build-nginx-1
              key_vals:
                - is_credential: false
                  key: username
                  type: string
                  value: admin
                - is_credential: false
                  choice_option:
                    - v1
                    - v2
                  key: password
                  type: choice
                  value: v1
              service_module: myapp-1
              service_name: a
            - build_name: simple-service-build-myapp-2
              service_module: myapp-2
              service_name: b
  - name: deploy
    jobs:
      - name: deploy
        type: zadig-deploy
        spec:
          env: pre-release
          job_name: build-myapps
          source: fromjob
project: simple-service
description: pre-release environment deployment
multi_run: false
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
# Variables
Workflows provide rich variable capabilities to support parameterized workflow configuration and information transfer among jobs, stages, workflows, and projects.
# Built-in Variables
| Variable Source | Variable | Description |
|---|---|---|
| Project | {{.project}} | Project name |
| Workflow | {{.workflow.name}} | Workflow identifier |
{{.workflow.task.id}} | Workflow task ID, for example 1 | |
{{.workflow.task.creator.id}} | Username of the workflow task executor, for example admin | |
{{.workflow.task.creator}} | Nickname of the workflow task executor, for example admin-nickname | |
{{.workflow.task.is_release_plan_trigger}} | Whether the workflow task is triggered by a release plan, for example true | |
{{.workflow.task.timestamp}} | Unix timestamp when the workflow task is created, for example 1686642562 | |
{{.workflow.task.datetime}} | Workflow task creation time, for example 2026-04-17 18:00:00 | |
| Build Job | {{.job.<job name>.SERVICES}} | Set of service modules selected for the build job The variable value is in the form of aslan/zadig,zadig-portal/zadig (service module name/service name) |
{{.job.<job name>.BRANCHES}} | Set of branch information for the first repository corresponding to the service modules selected for the build job The variable value is in the form of feature1,feature2,feature3 | |
{{.job.<job name>.IMAGES}} | Set of images corresponding to the service modules selected for the build job The variable value is in the form of image1:tag1,image2:tag2 | |
{{.job.<job name>.GITURLS}} | Set of first repository information corresponding to the service modules selected for the build job. The variable value is in the form of https://gitlab.com/group1/repo1,https://gitlab.com/group2/repo2 (code source URL/organization name or username/repository name) | |
{{.job.<job name>.<service>.<service module>.COMMITID}} | Commit information of the first repository of the specified service module | |
{{.job.<job name>.<service>.<service module>.BRANCH}} | Branch information of the first repository when the service module is specified | |
| Deploy Job | {{.job.<job name>.envName}} | Deployment environment |
{{.job.<job name>.IMAGES}} | Set of images of deployed service modules The variable value is in the form of image1:tag1,image2:tag2 | |
{{.job.<job name>.VERSION_NAME}} | Version name selected during deployment | |
| Image Distribution Job | {{.job.<job name>.IMAGES}} | Set of target images of distributed service modules The variable value is in the form of image1:tag1,image2:tag2 |
# Custom Variables
Workflow variables are divided into global variables and job variables. Global variables are configured as shown below, and custom variables in jobs are configured in the corresponding jobs.
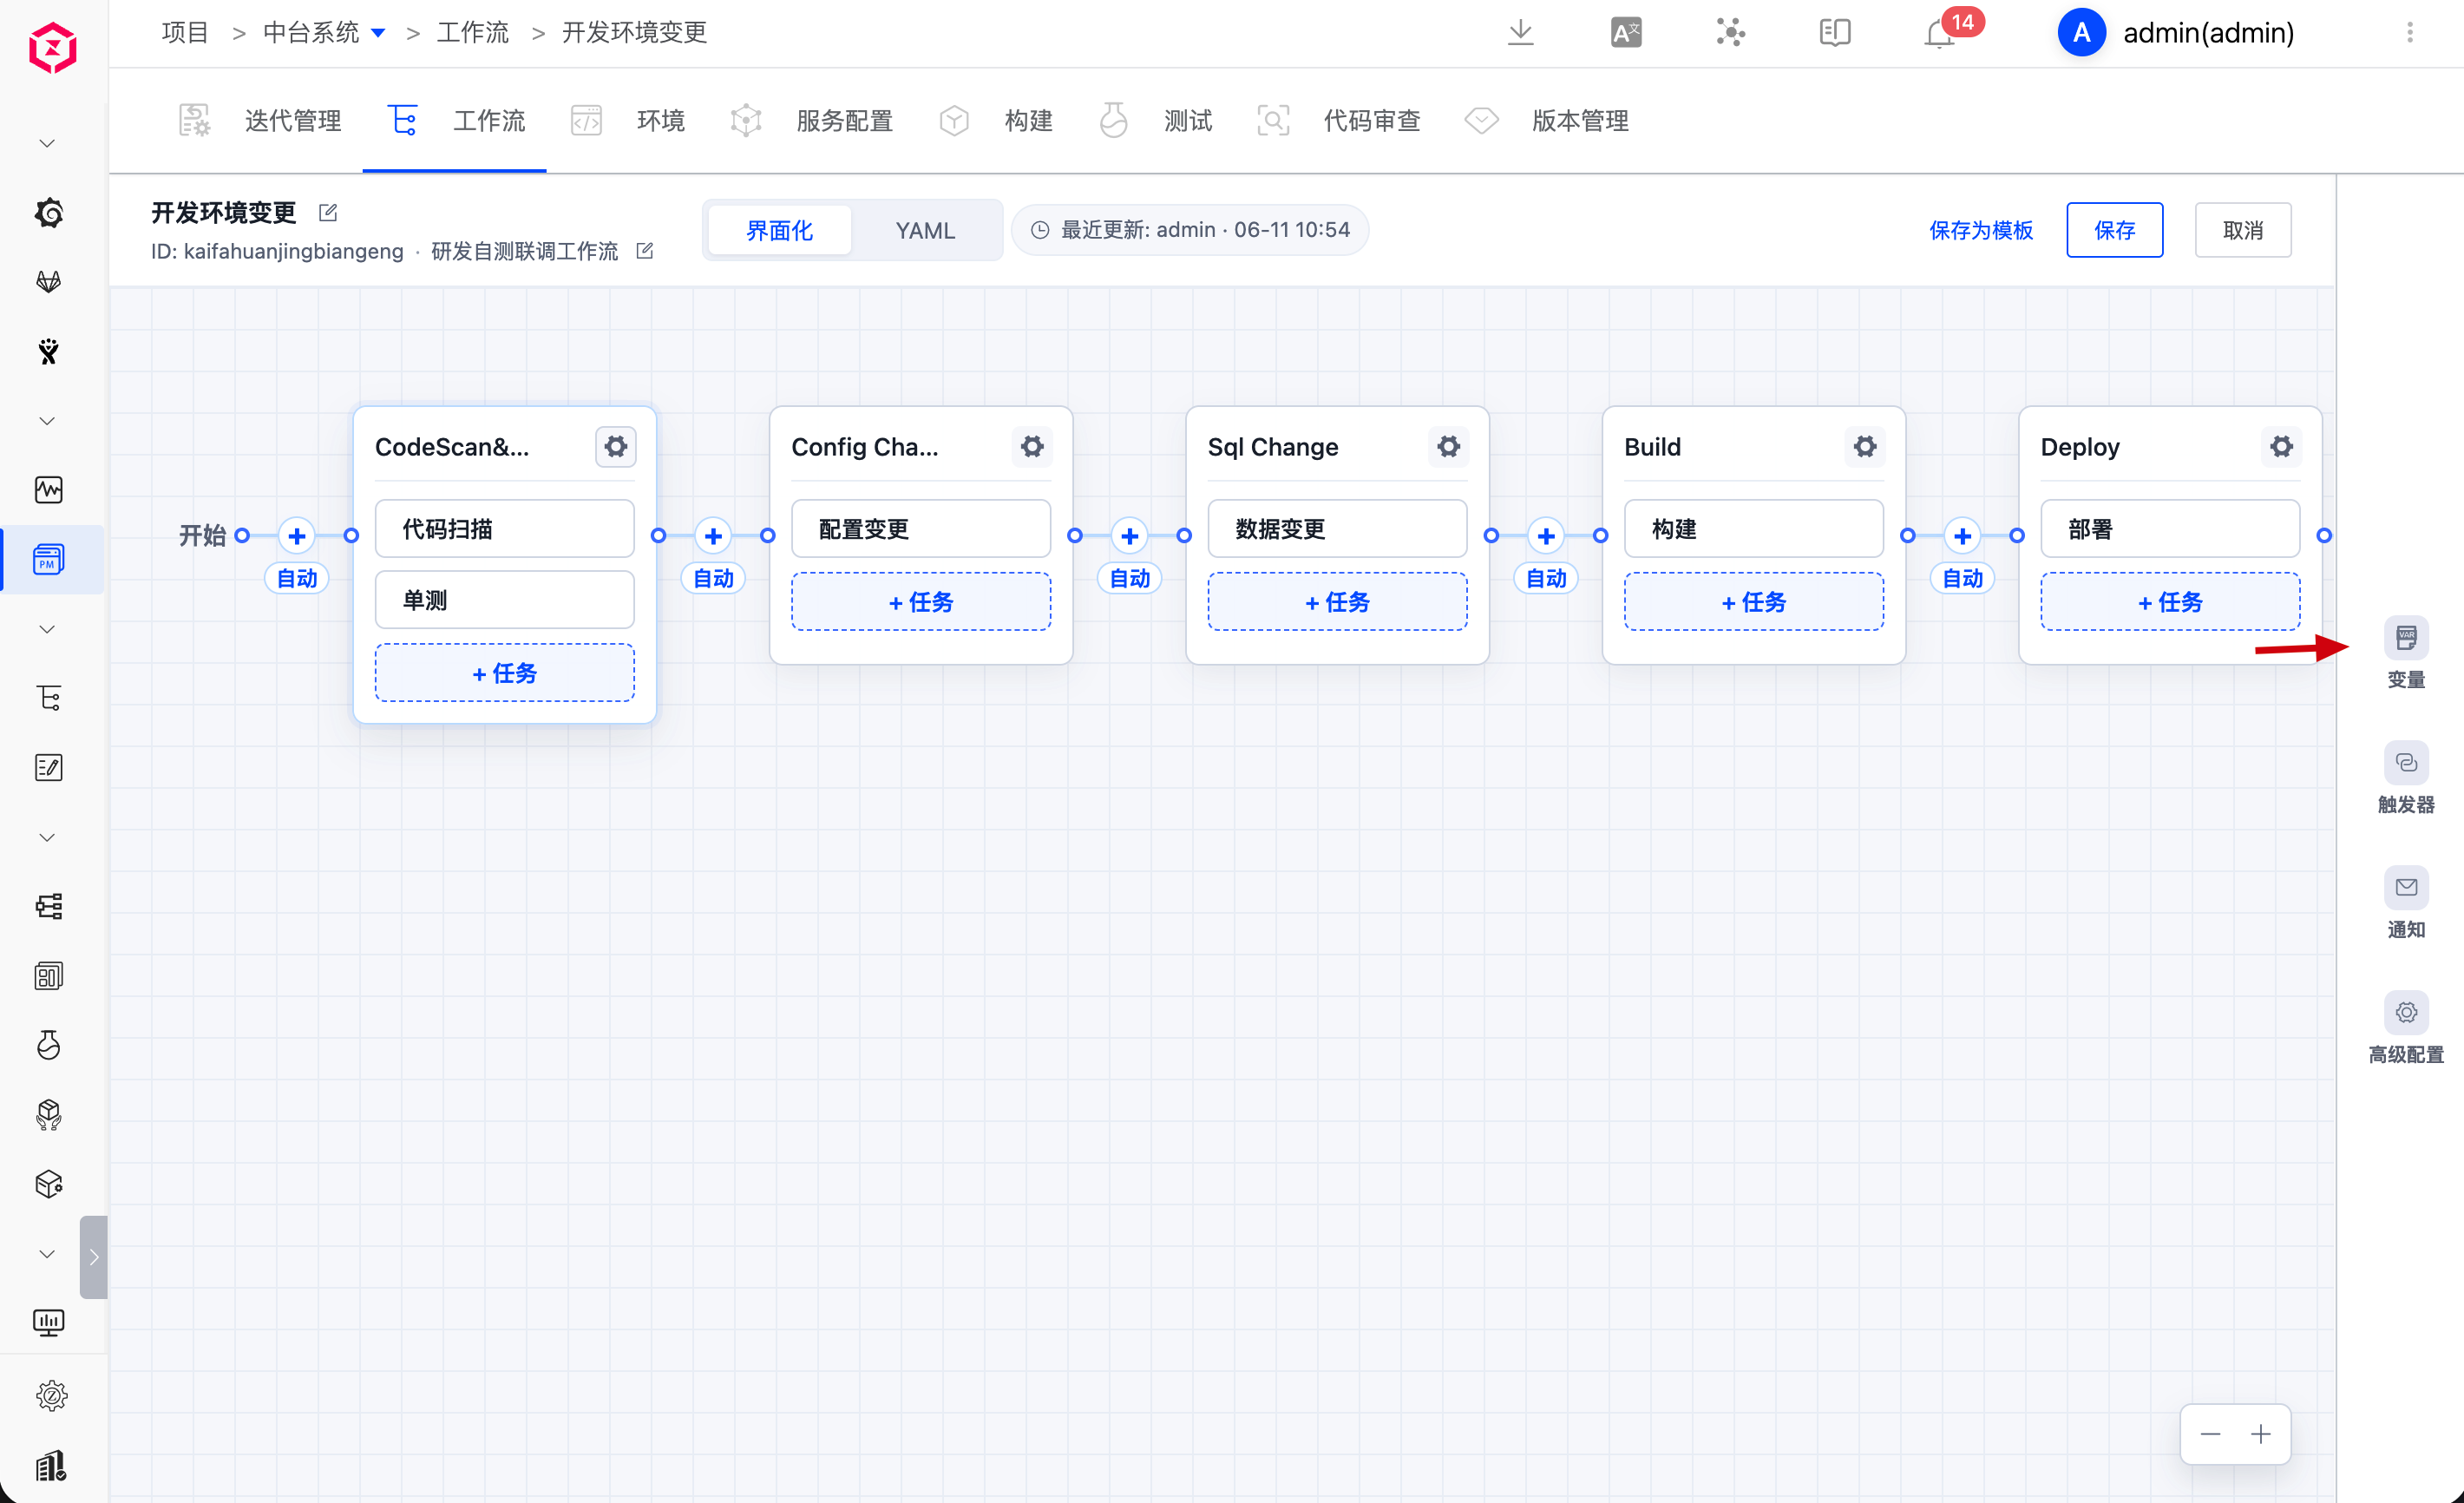
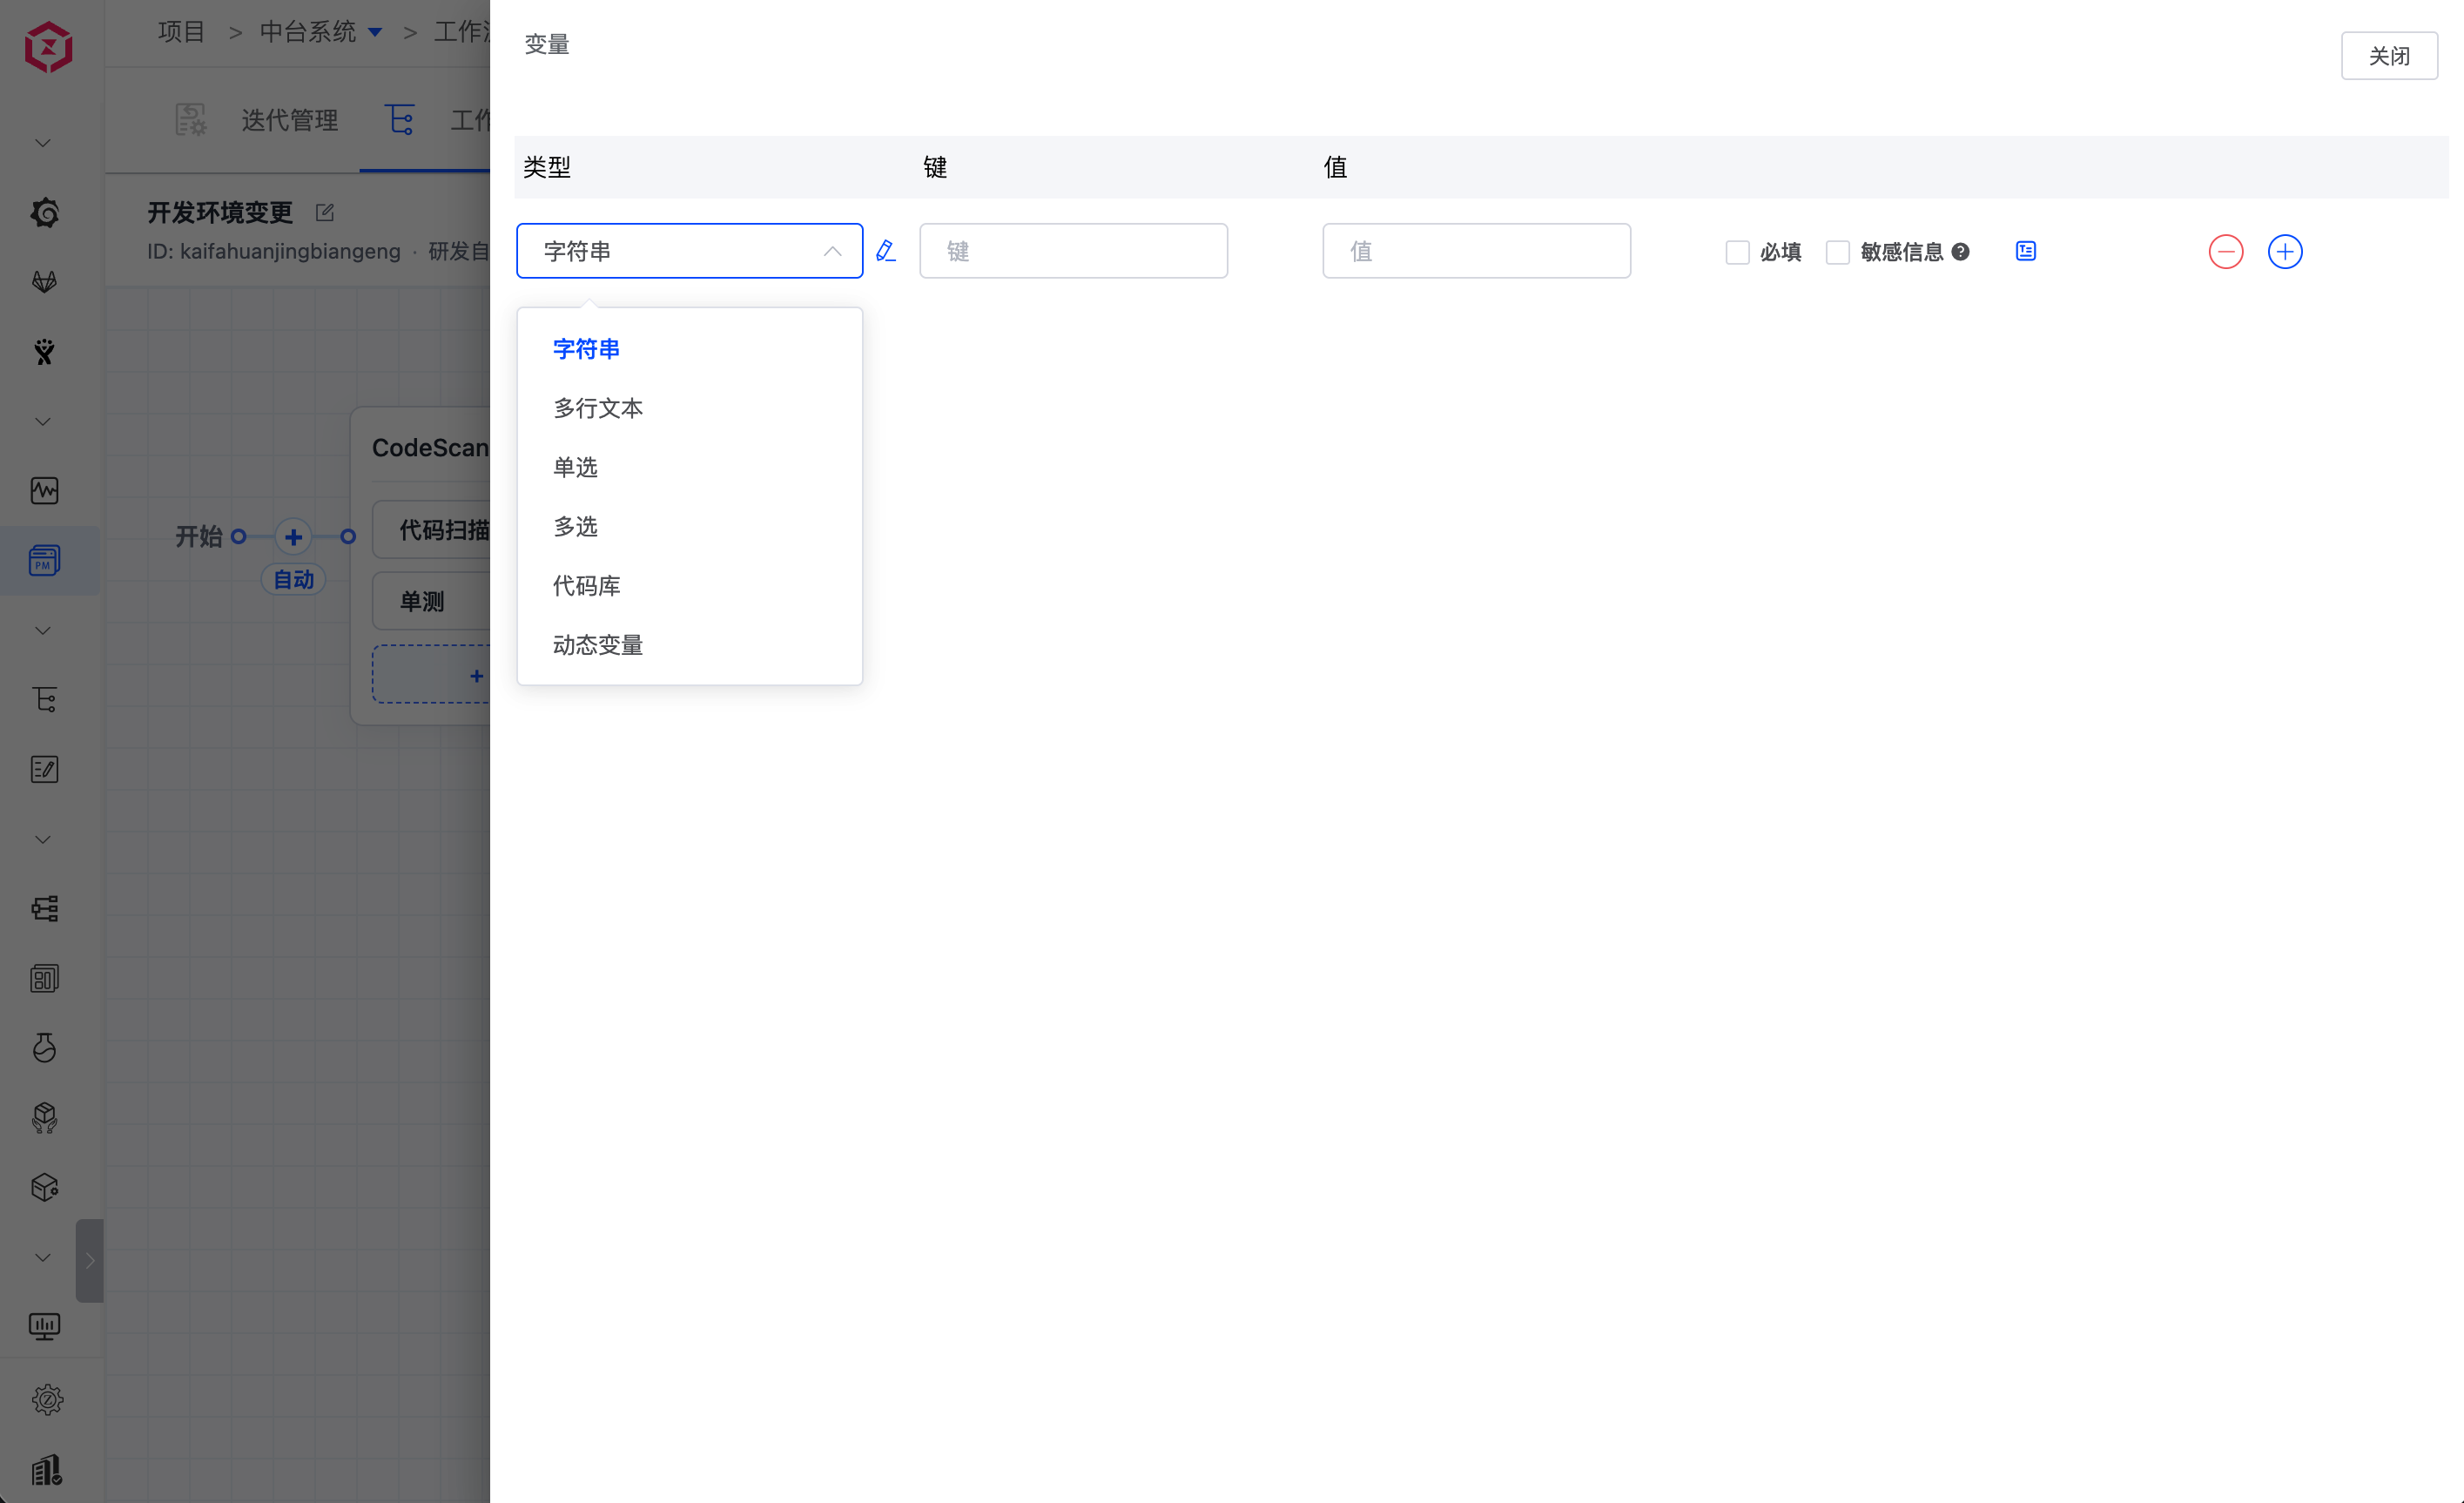
Variable description:
Type: Supports string, multi-line text, single choice, multiple choice, file, code repository, image, and dynamic variable.Code Repositoryis available only in workflow global variables.Imageis available only in general script execution.
Key: The key of the custom variable.Value: The value of the custom variable. Runtime input and fixed value are supported. For details, see Variable Assignment Methods.
# Variable Assignment Methods
Click the small icon on the right side of a variable to assign a value. The assignment methods are described below:
Runtime Input: Specify the variable value when running the workflow.Fixed Value: Set a fixed value for the variable. The variable is not visible on the workflow execution page, and no value needs to be assigned during execution.Global Variable/Other Job Output: Use a global variable or a variable output from another job for assignment. During workflow execution, global variables are rendered automatically to transfer variables between different jobs.- Supported global variables include Built-in Variables and Custom Variables.
- To use
Other Job Output, configure output variables for the job first. See Configure Output Variables.
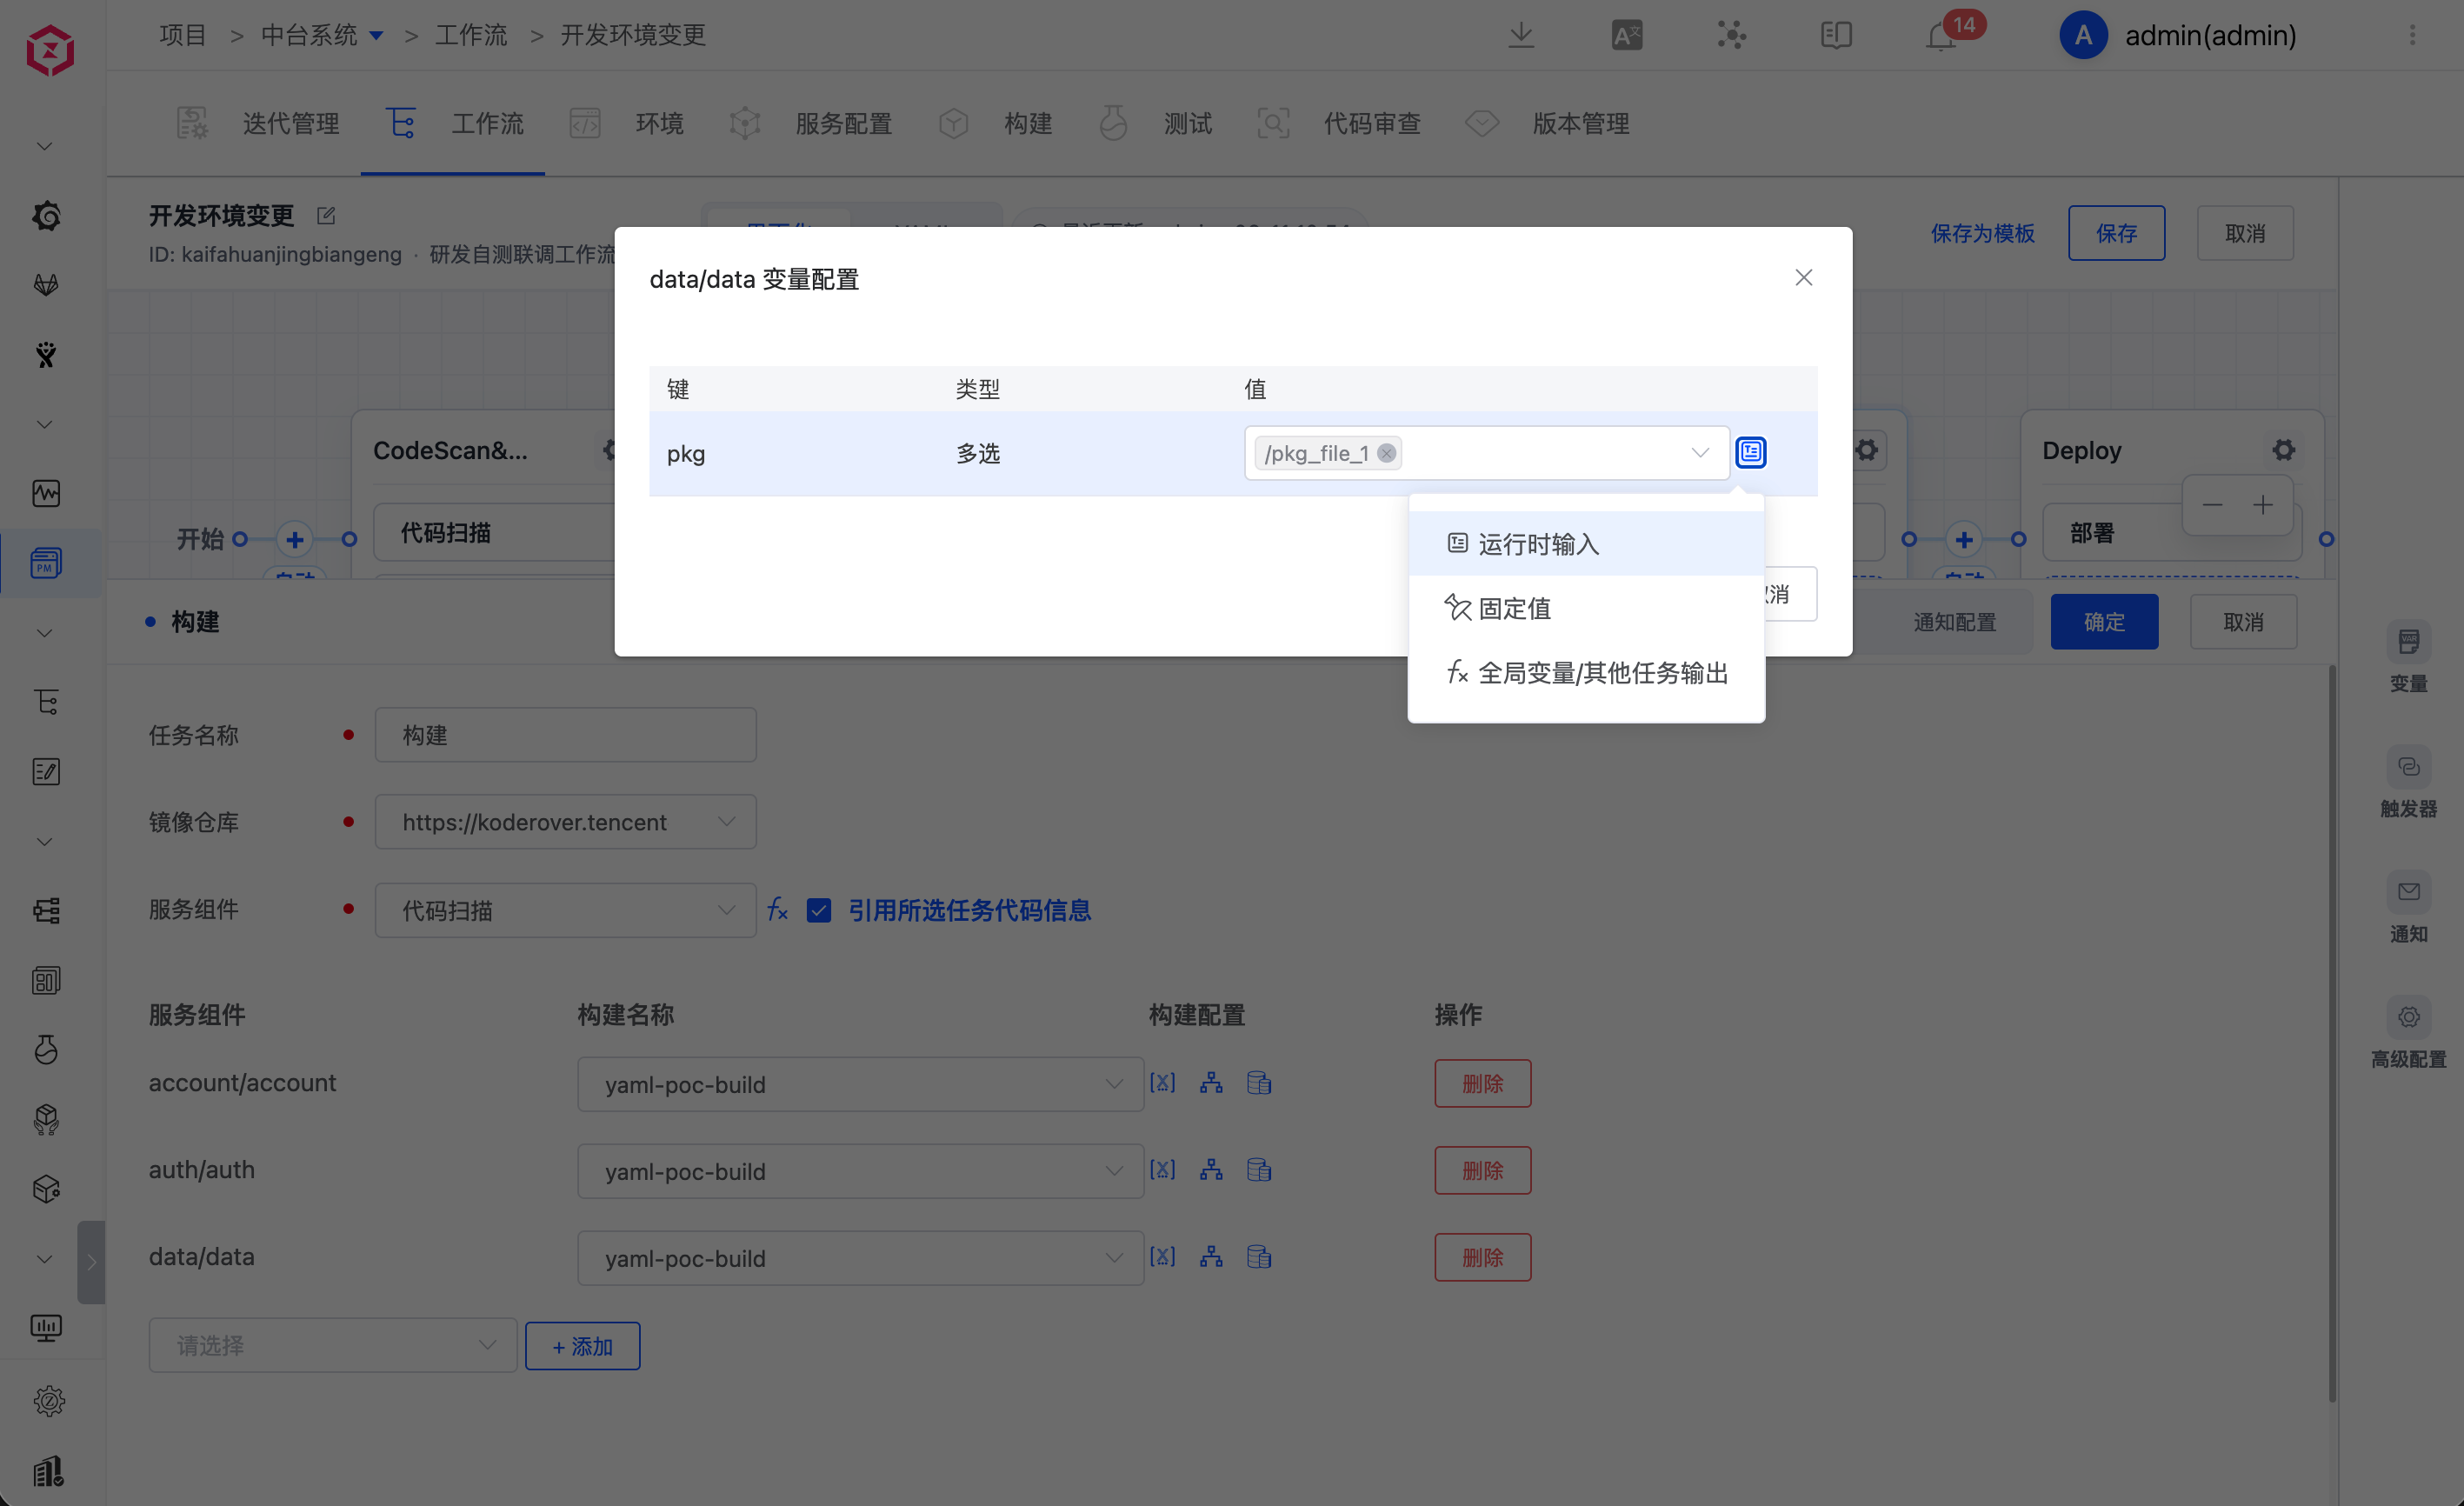
Global variables can be used in two ways:
- Use them as shell environment variables in build, code scan, test, and general script execution jobs.
- Define a custom variable in a job, set the assignment method to
Global Variable/Other Job Output, and select the corresponding global variable.
# Variable Passing
Variables can be passed between different jobs. The process is as follows:
- Declare the variables to be output in the advanced configuration of the upstream job.
- Use the variable in the downstream job through
Global Variable/Other Job Output.
Configure Output Variables
Output variables can be configured in build, test, code scan, and general script execution jobs. The output variable formats for different jobs are as follows:
- Build job:
{{.job.<job name>.<service name>.<service module name>.output.<variable name>}} - Test job:
{{.job.<job name>.<test name>.output.<variable name>}} - Code scan job:
{{.job.<job name>.<code scan name>.output.<variable name>}} - General script execution:
{{.job.<job name>.output.<variable name>}}
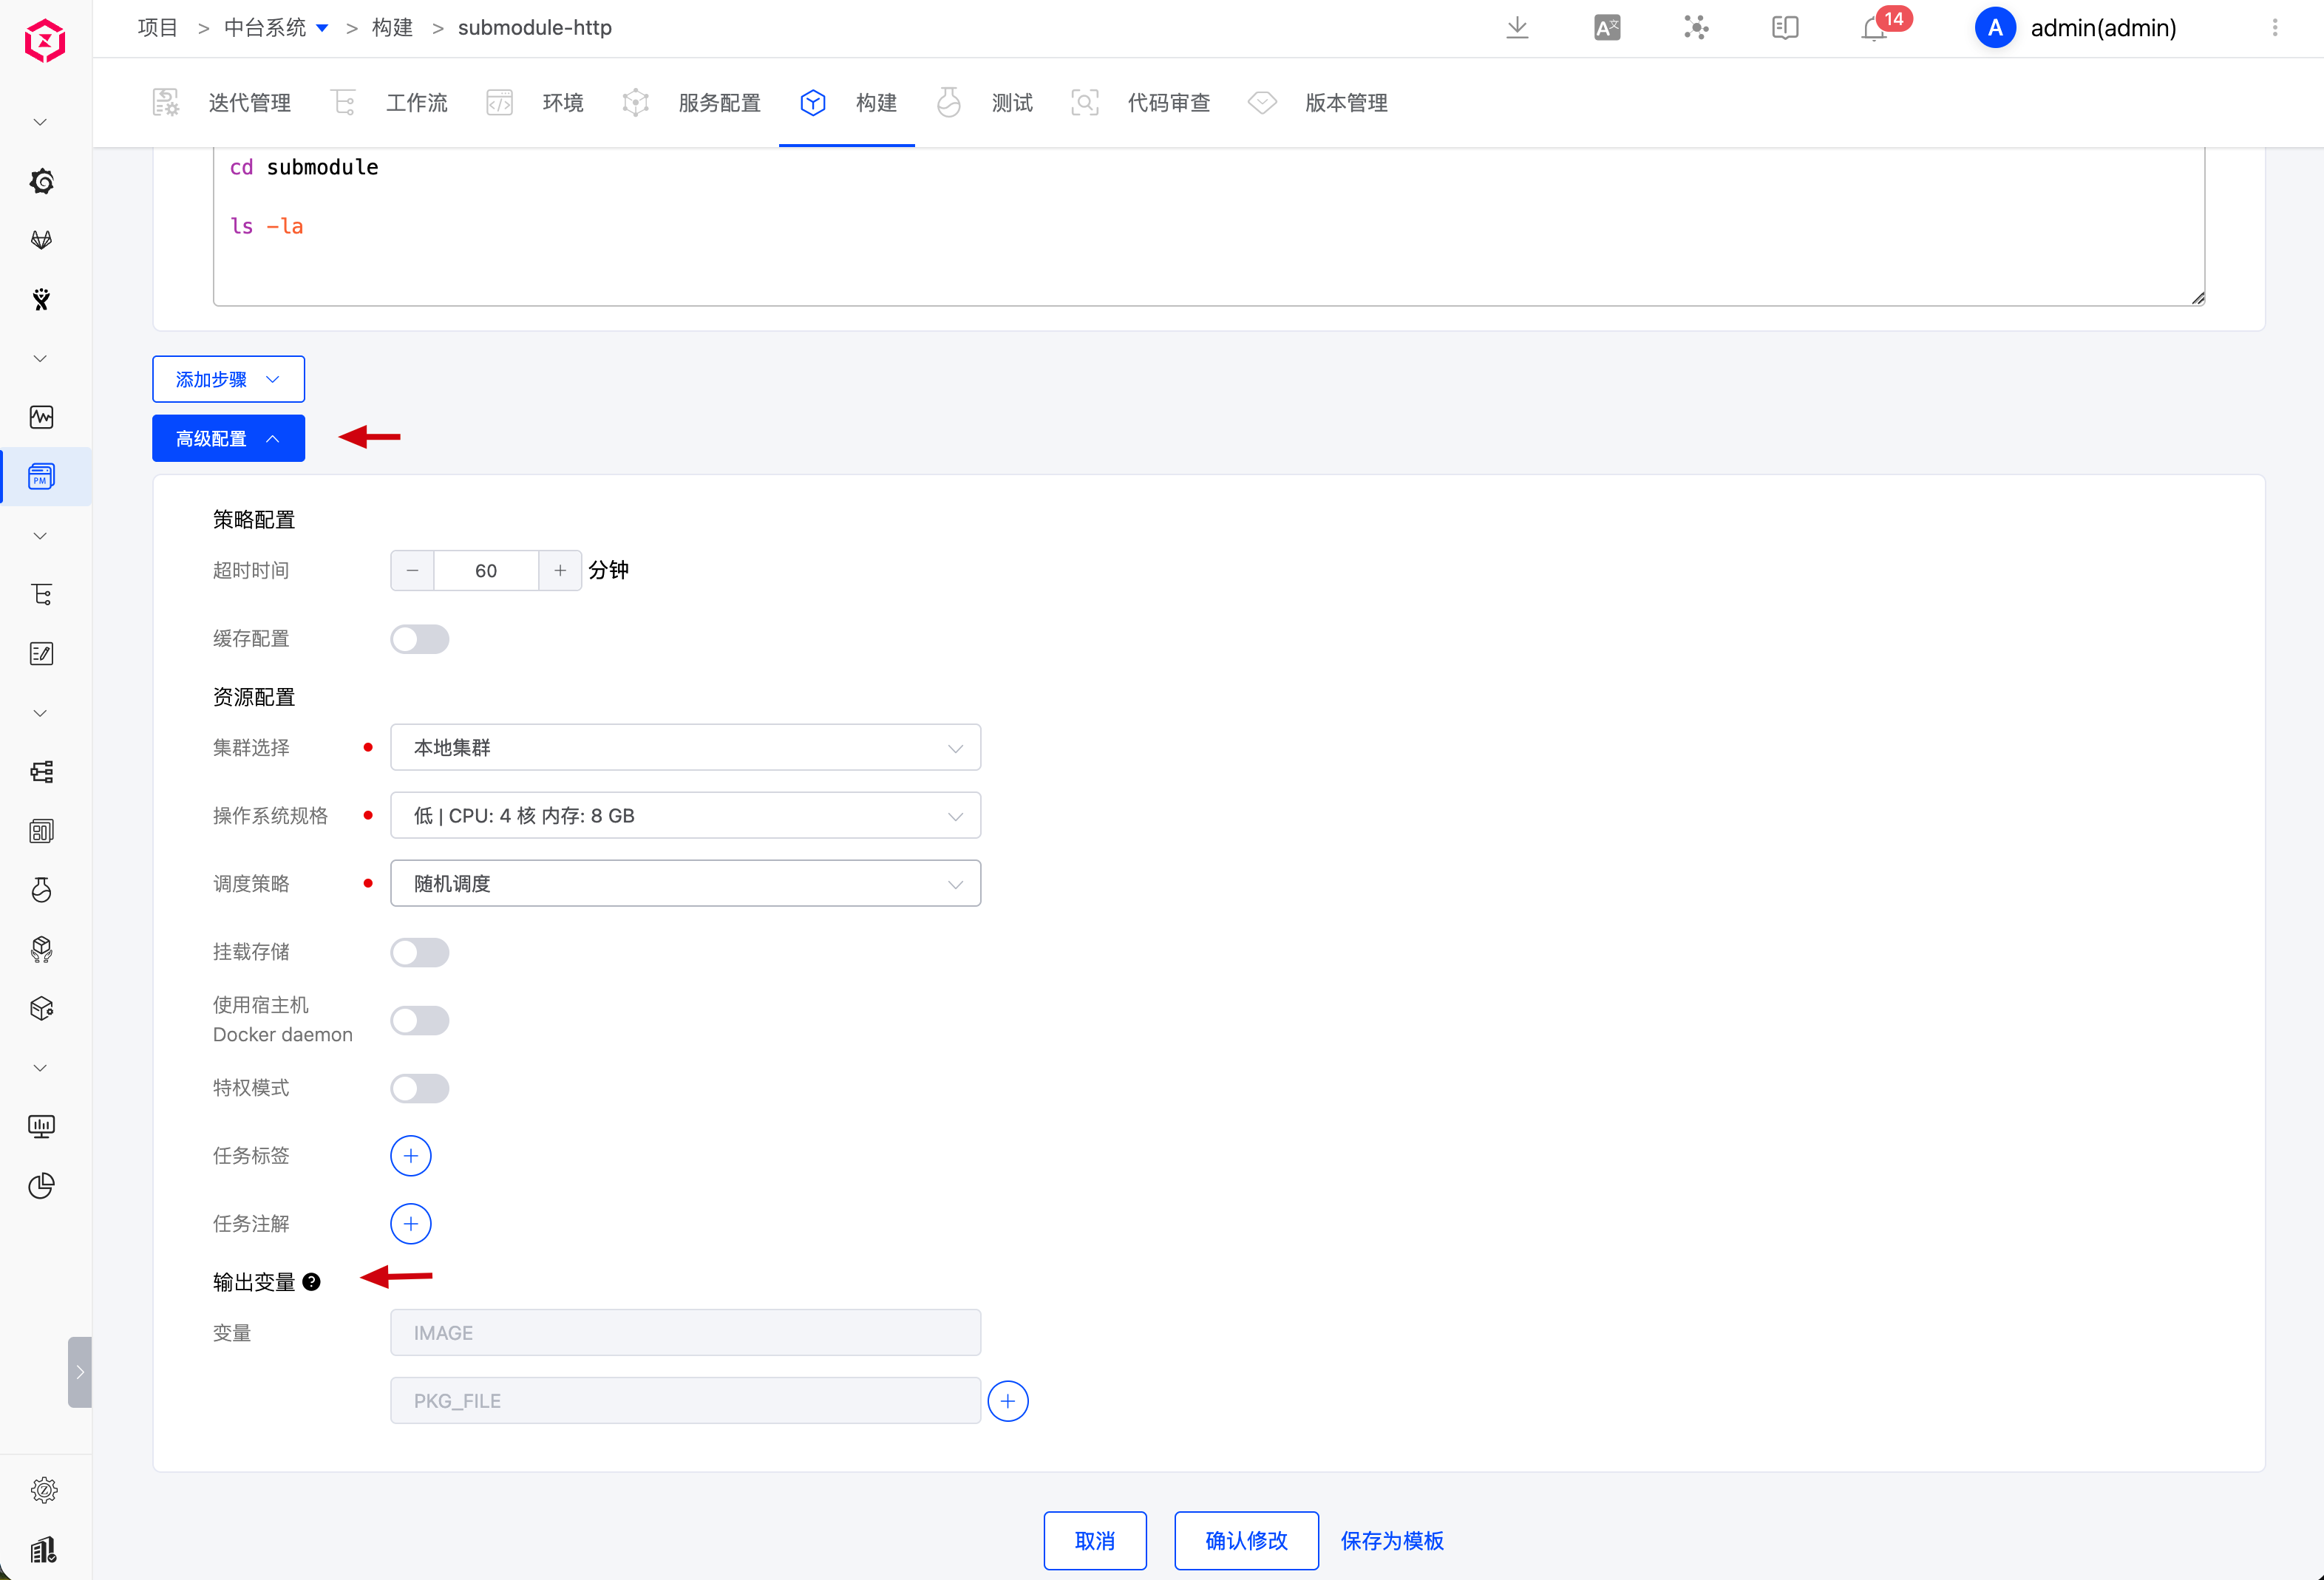
Taking a build job as an example, add an output variable in the advanced configuration and enter the variable name.
Tip
- The added variable can come from a custom variable in the build configuration or a variable set in the build script, such as
export key=value. - By default, the system outputs the
IMAGEandPKG_FILEvariables from the build, which represent the service image name and artifact file name respectively.
Use Output Variables
For jobs that support the Global Variable/Other Job Output assignment method, see Configuration Methods Supported by Different Jobs.
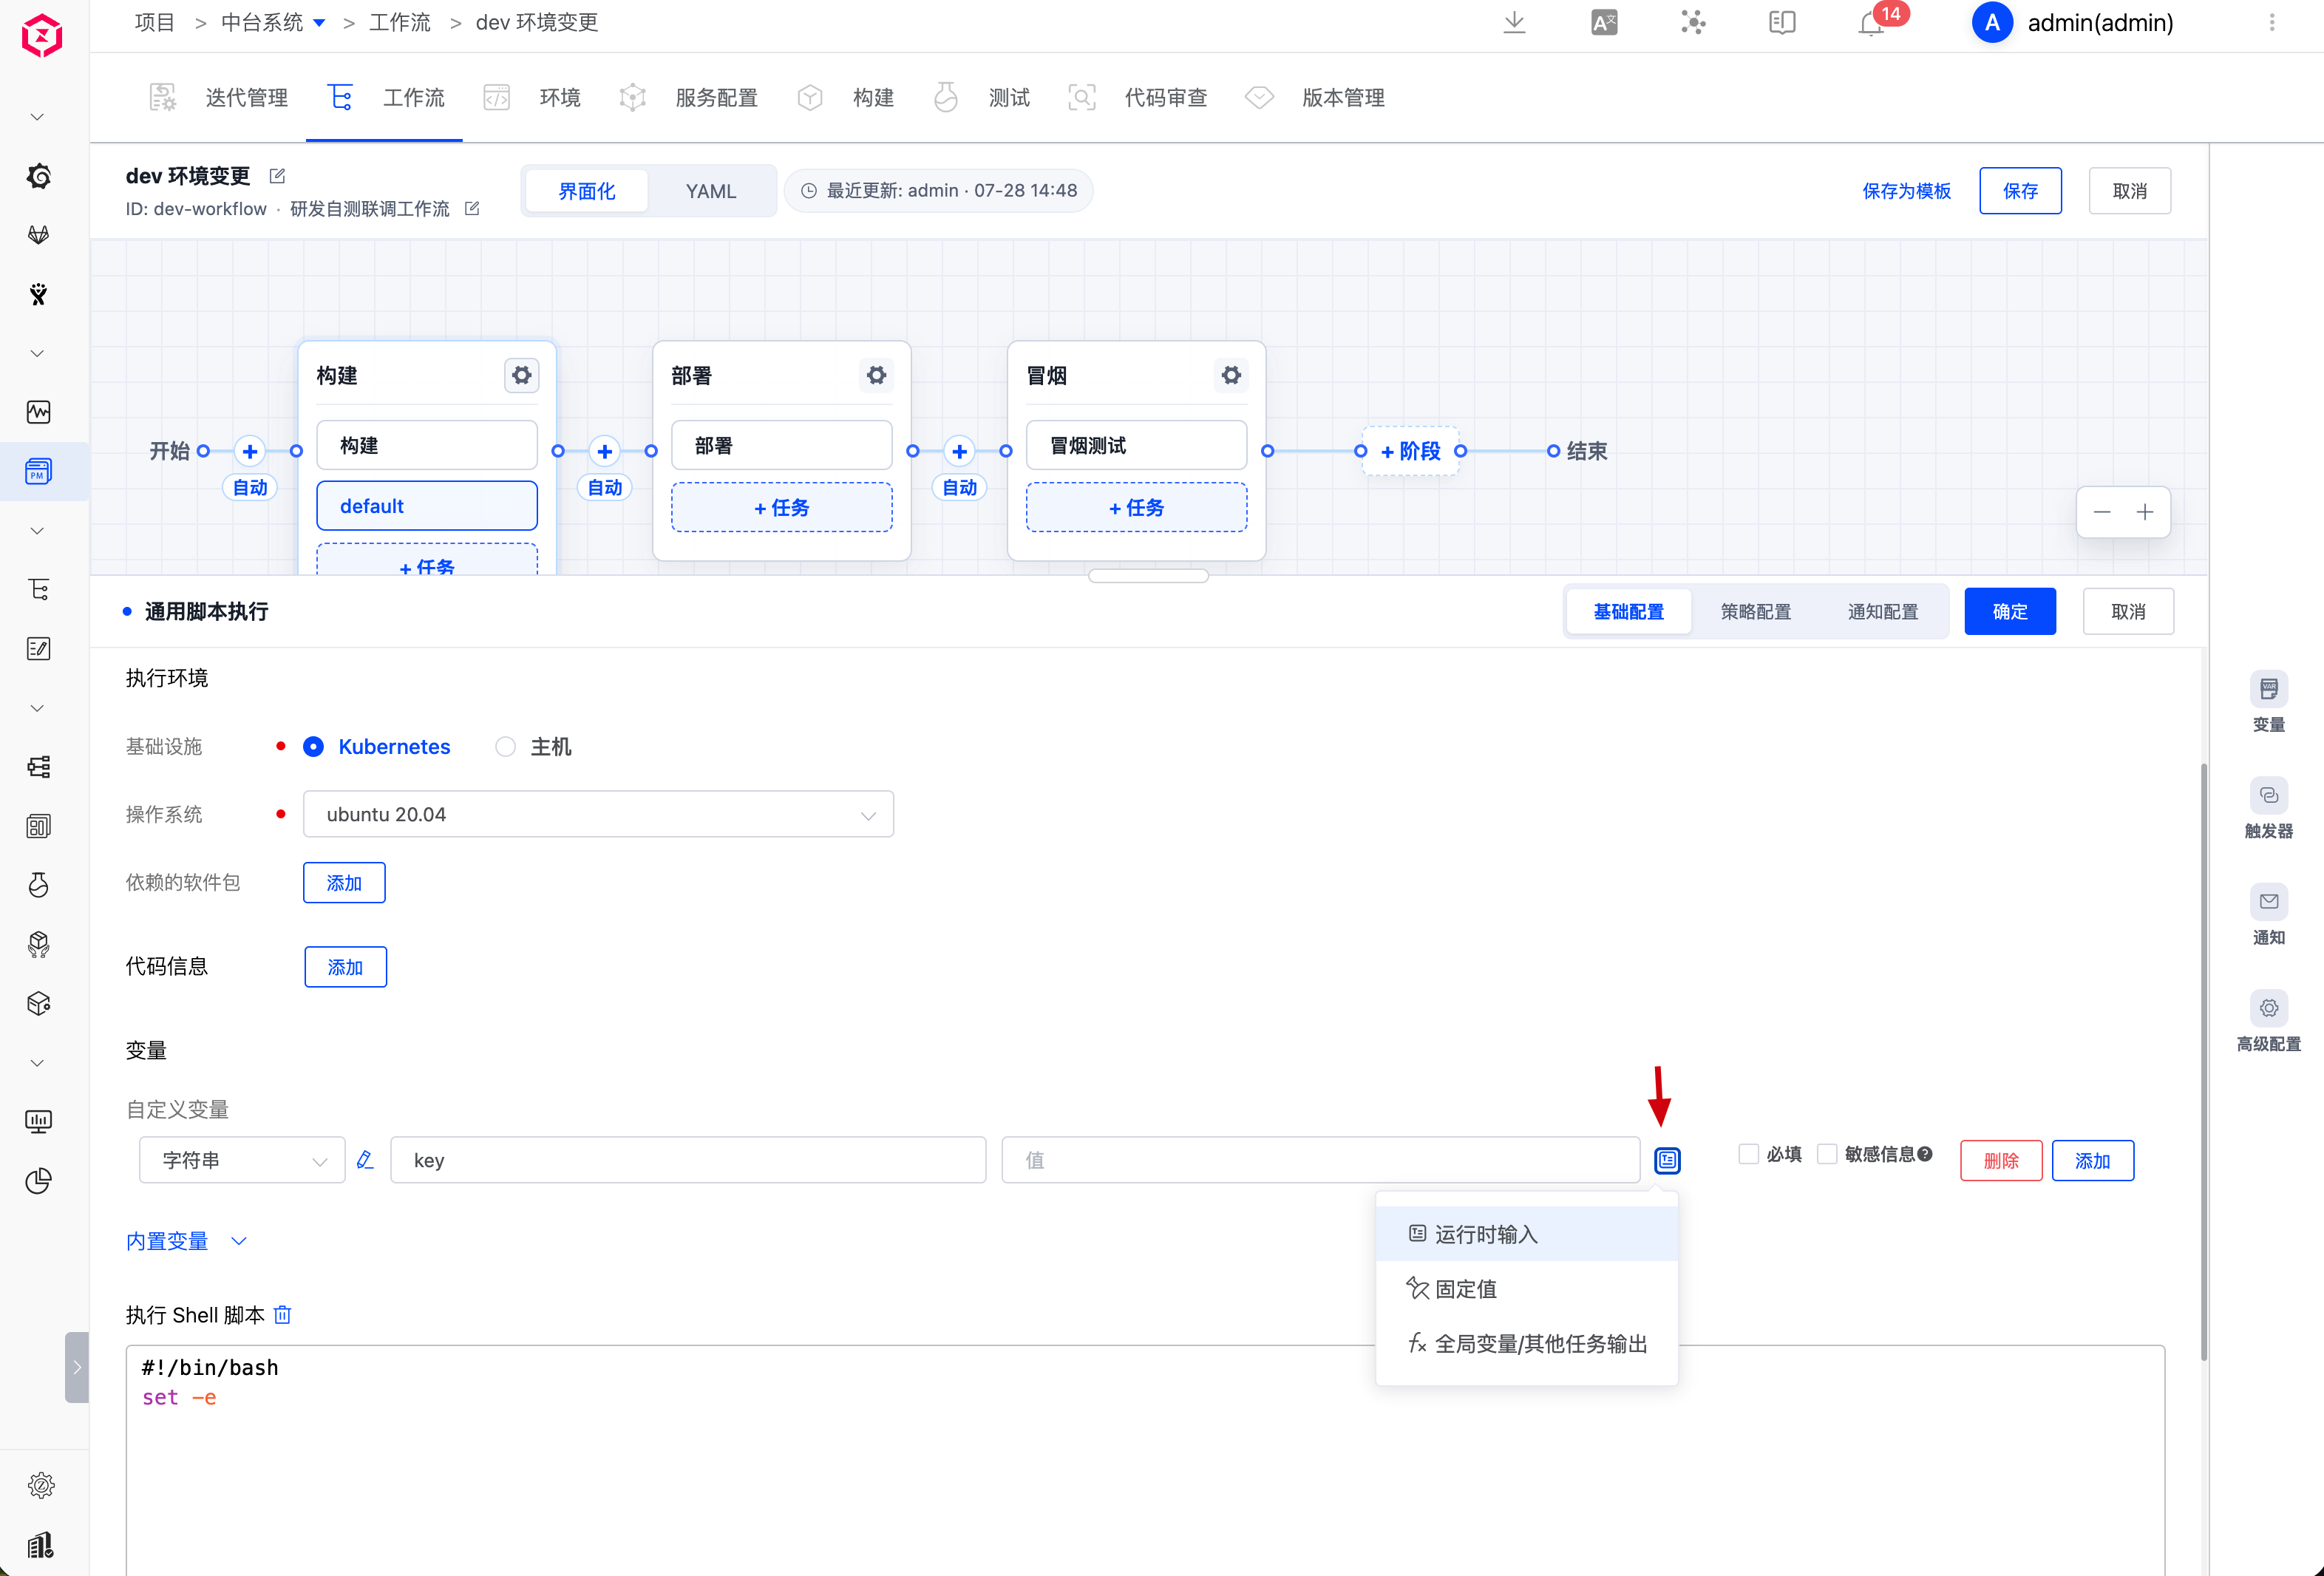
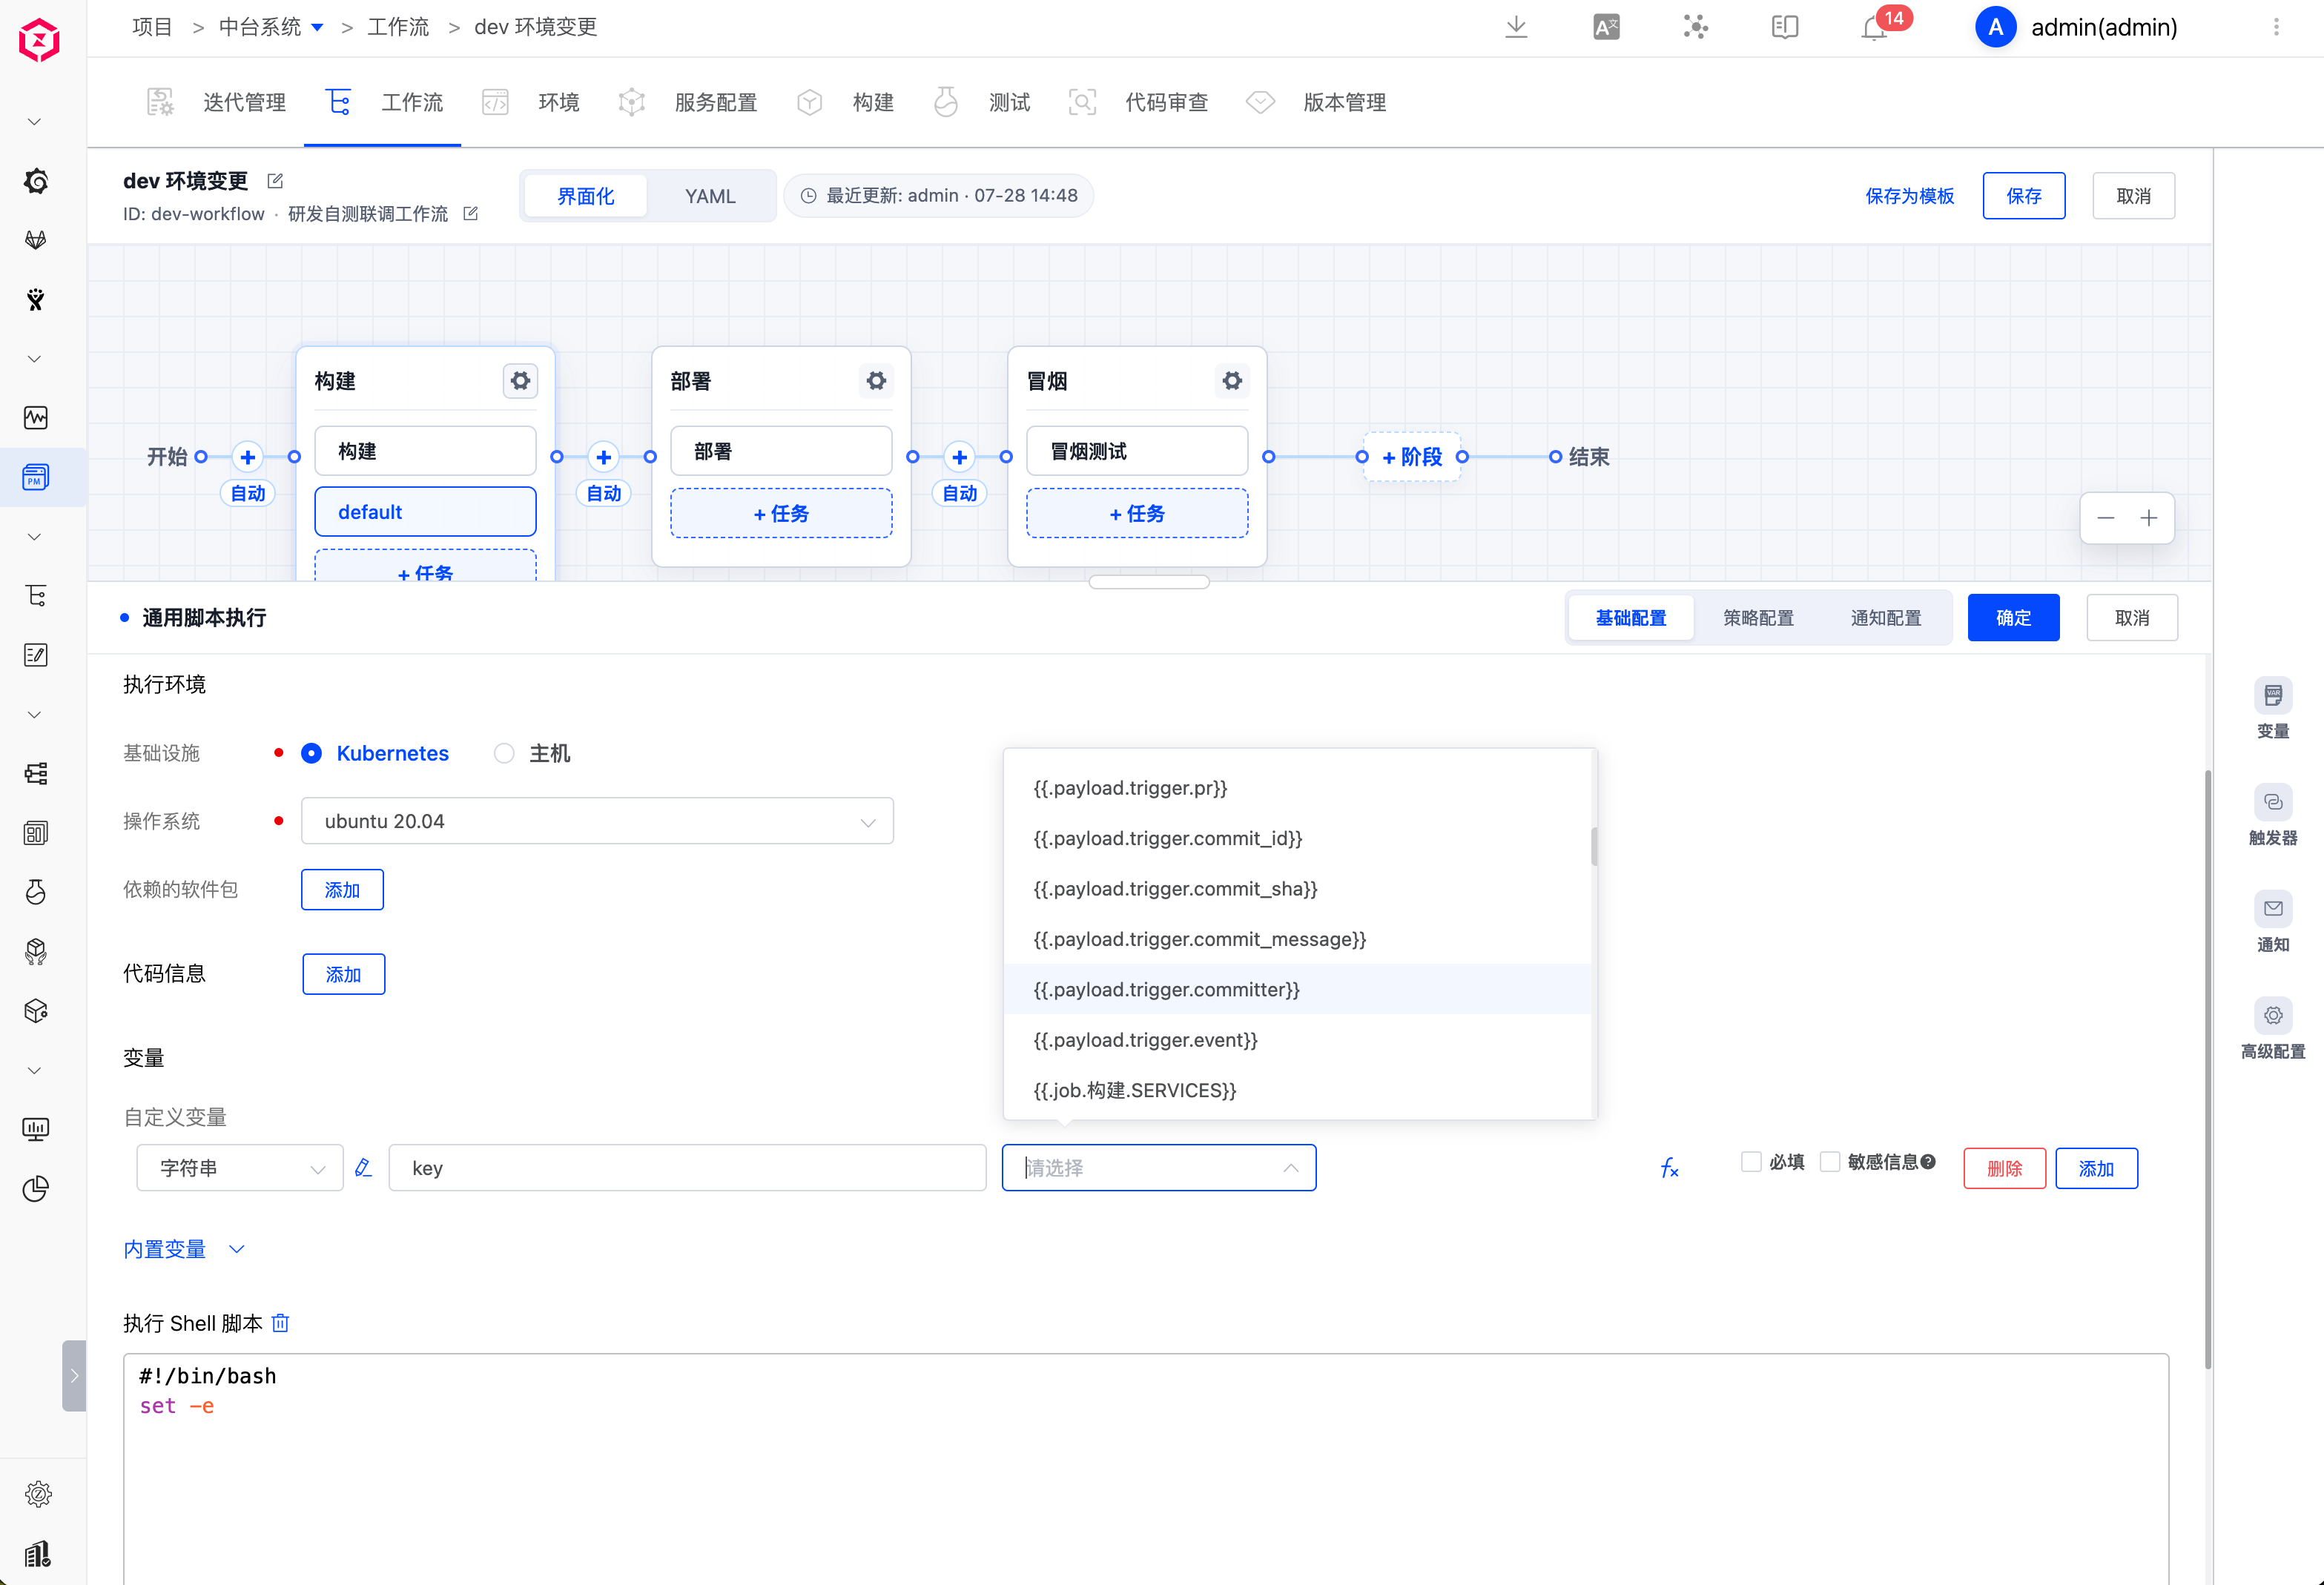
Taking a custom variable in general script execution as an example: when assigning a value to the variable in general script execution, set the assignment method to Global Variable/Other Job Output and select the output variable configured in the upstream job. This passes variables between different jobs.
# Job Scheduling Policy
# Execution Policy
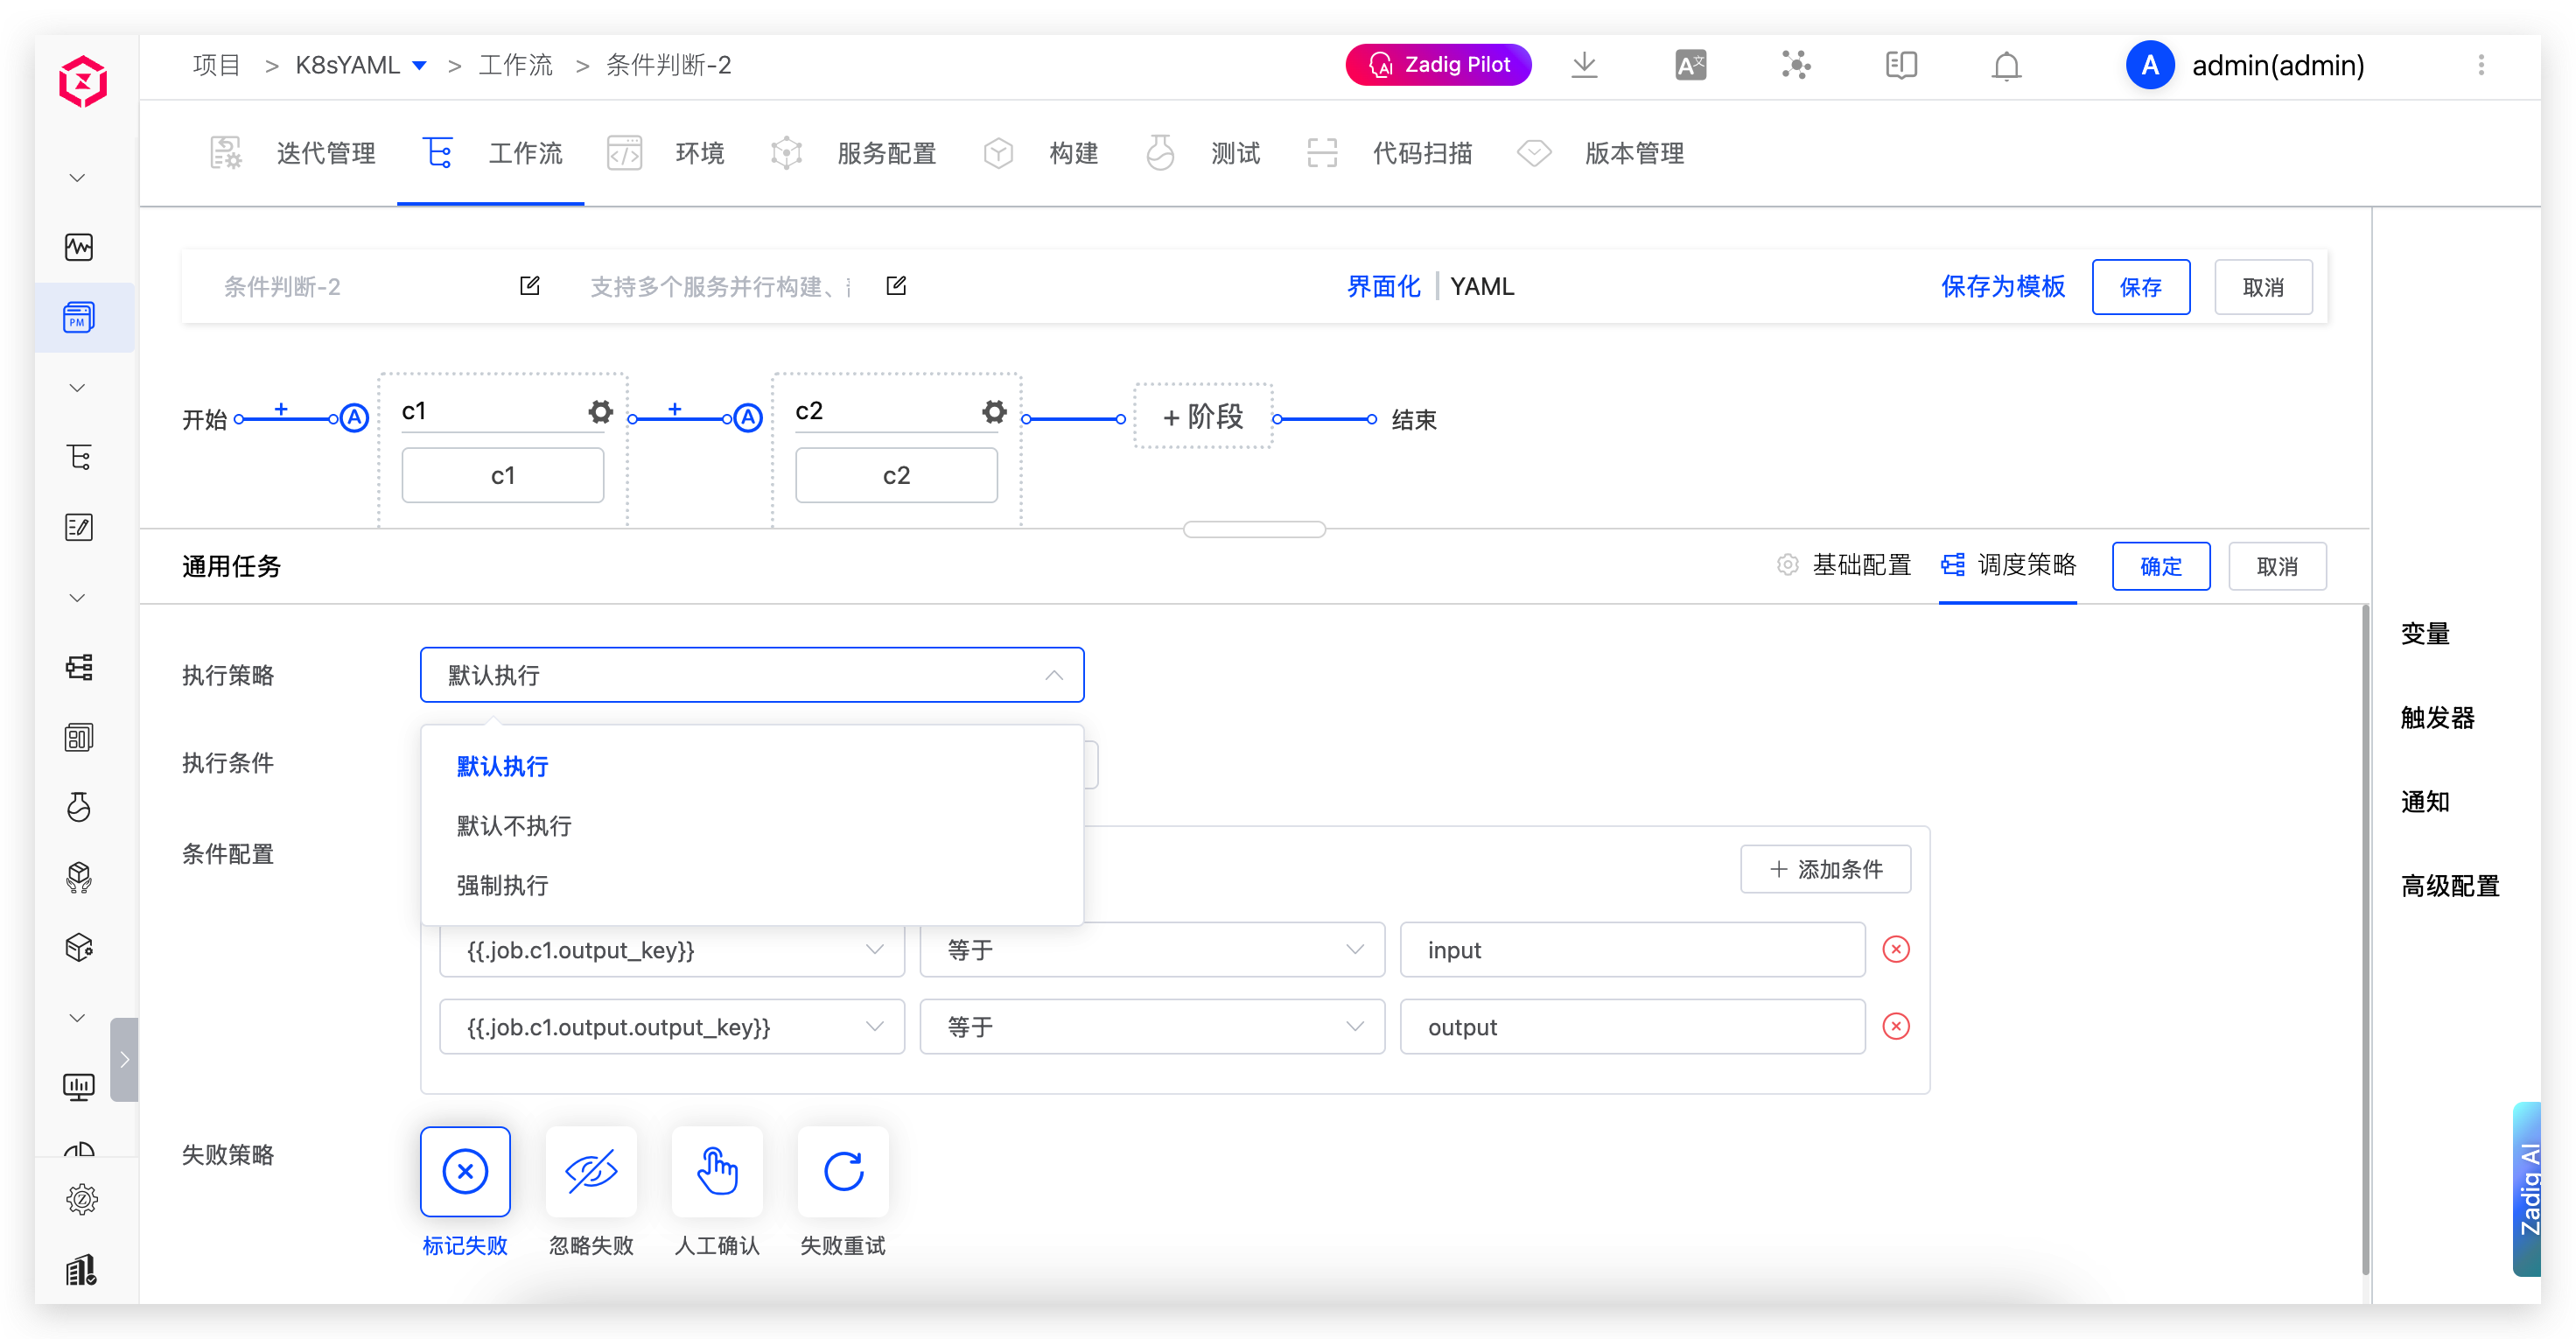
- Execute by Default: Jobs configured to execute by default are selected by default when
Run JoborConfigure Triggeris used. Users can choose not to execute them. - Do Not Execute by Default: Jobs configured not to execute by default are not selected by default when
Run JoborConfigure Triggeris used. Users can choose to execute them. - Force Execute: Jobs configured for forced execution must be executed when
Run JoborConfigure Triggeris used. Users cannot choose not to execute them.
# Execution Conditions
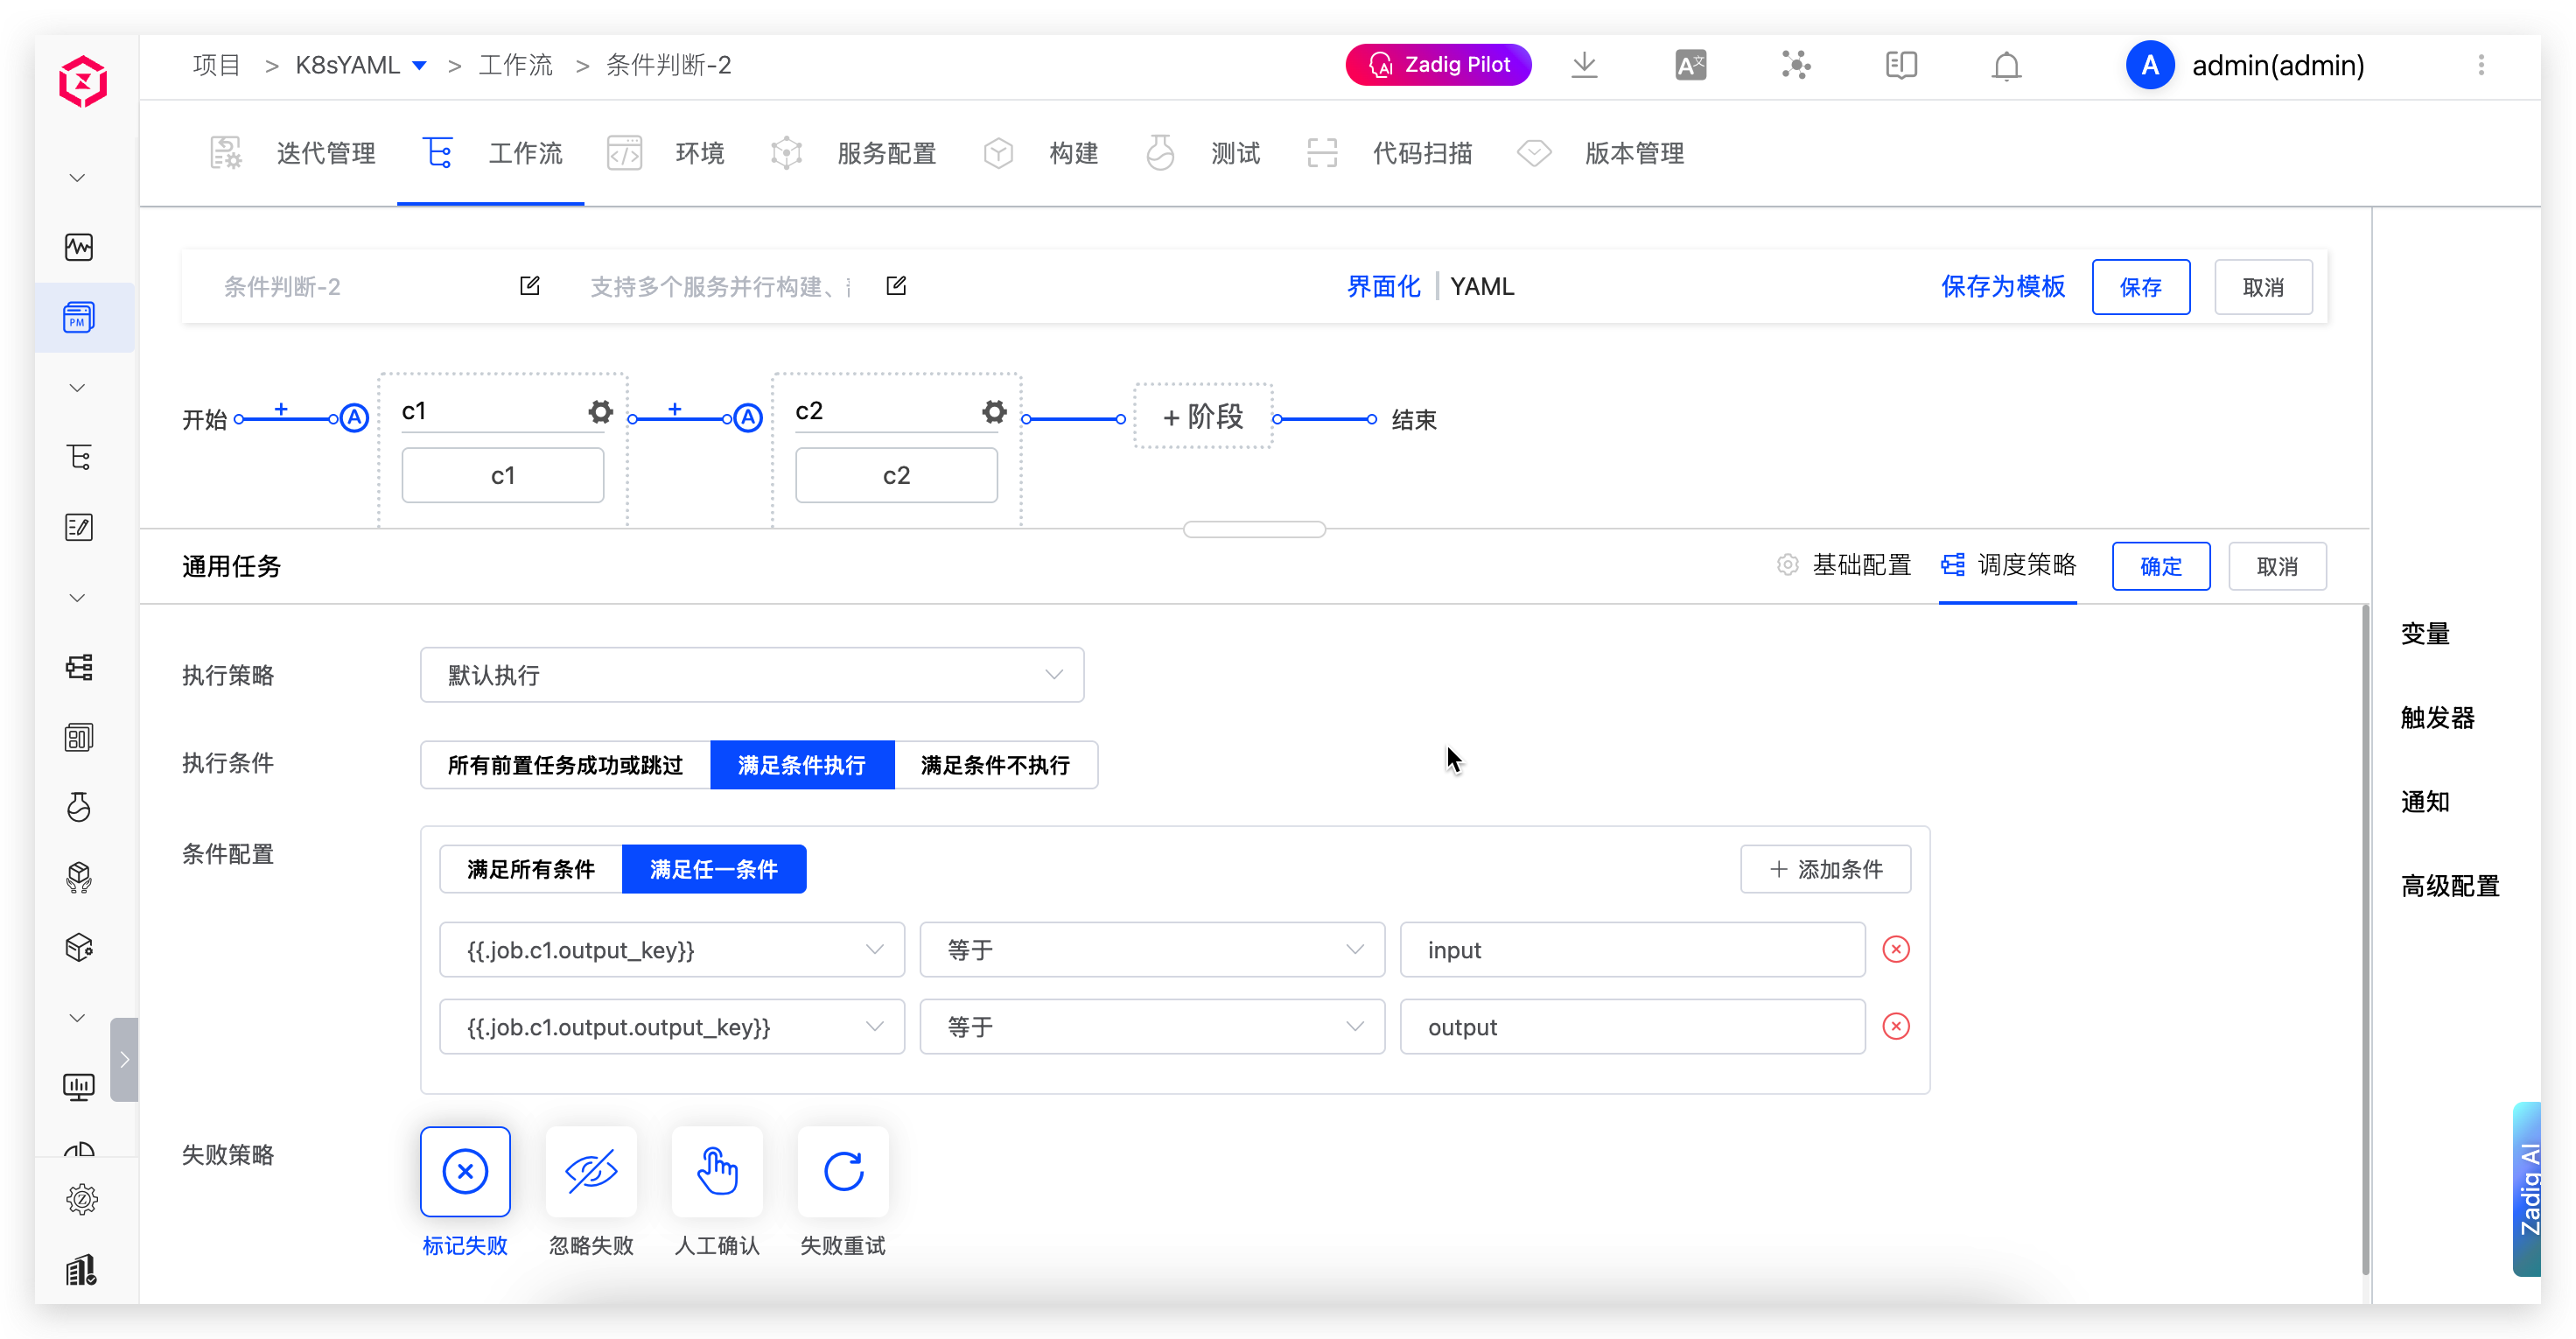
- All Upstream Jobs Succeeded or Skipped: Execute when all upstream jobs succeed or are skipped.
- Execute When Conditions Are Met: Execute when the configured conditions are met.
- Do Not Execute When Conditions Are Met: Do not execute when the configured conditions are met.
Condition configuration:
- Supports two matching modes:
Meet All ConditionsandMeet Any Condition. - Supports built-in variables and custom variables. Operators include:
Equals,Not Equals,Contains,Not Contains,Starts With,Does Not Start With,Ends With, andDoes Not End With.
# Failure Policy
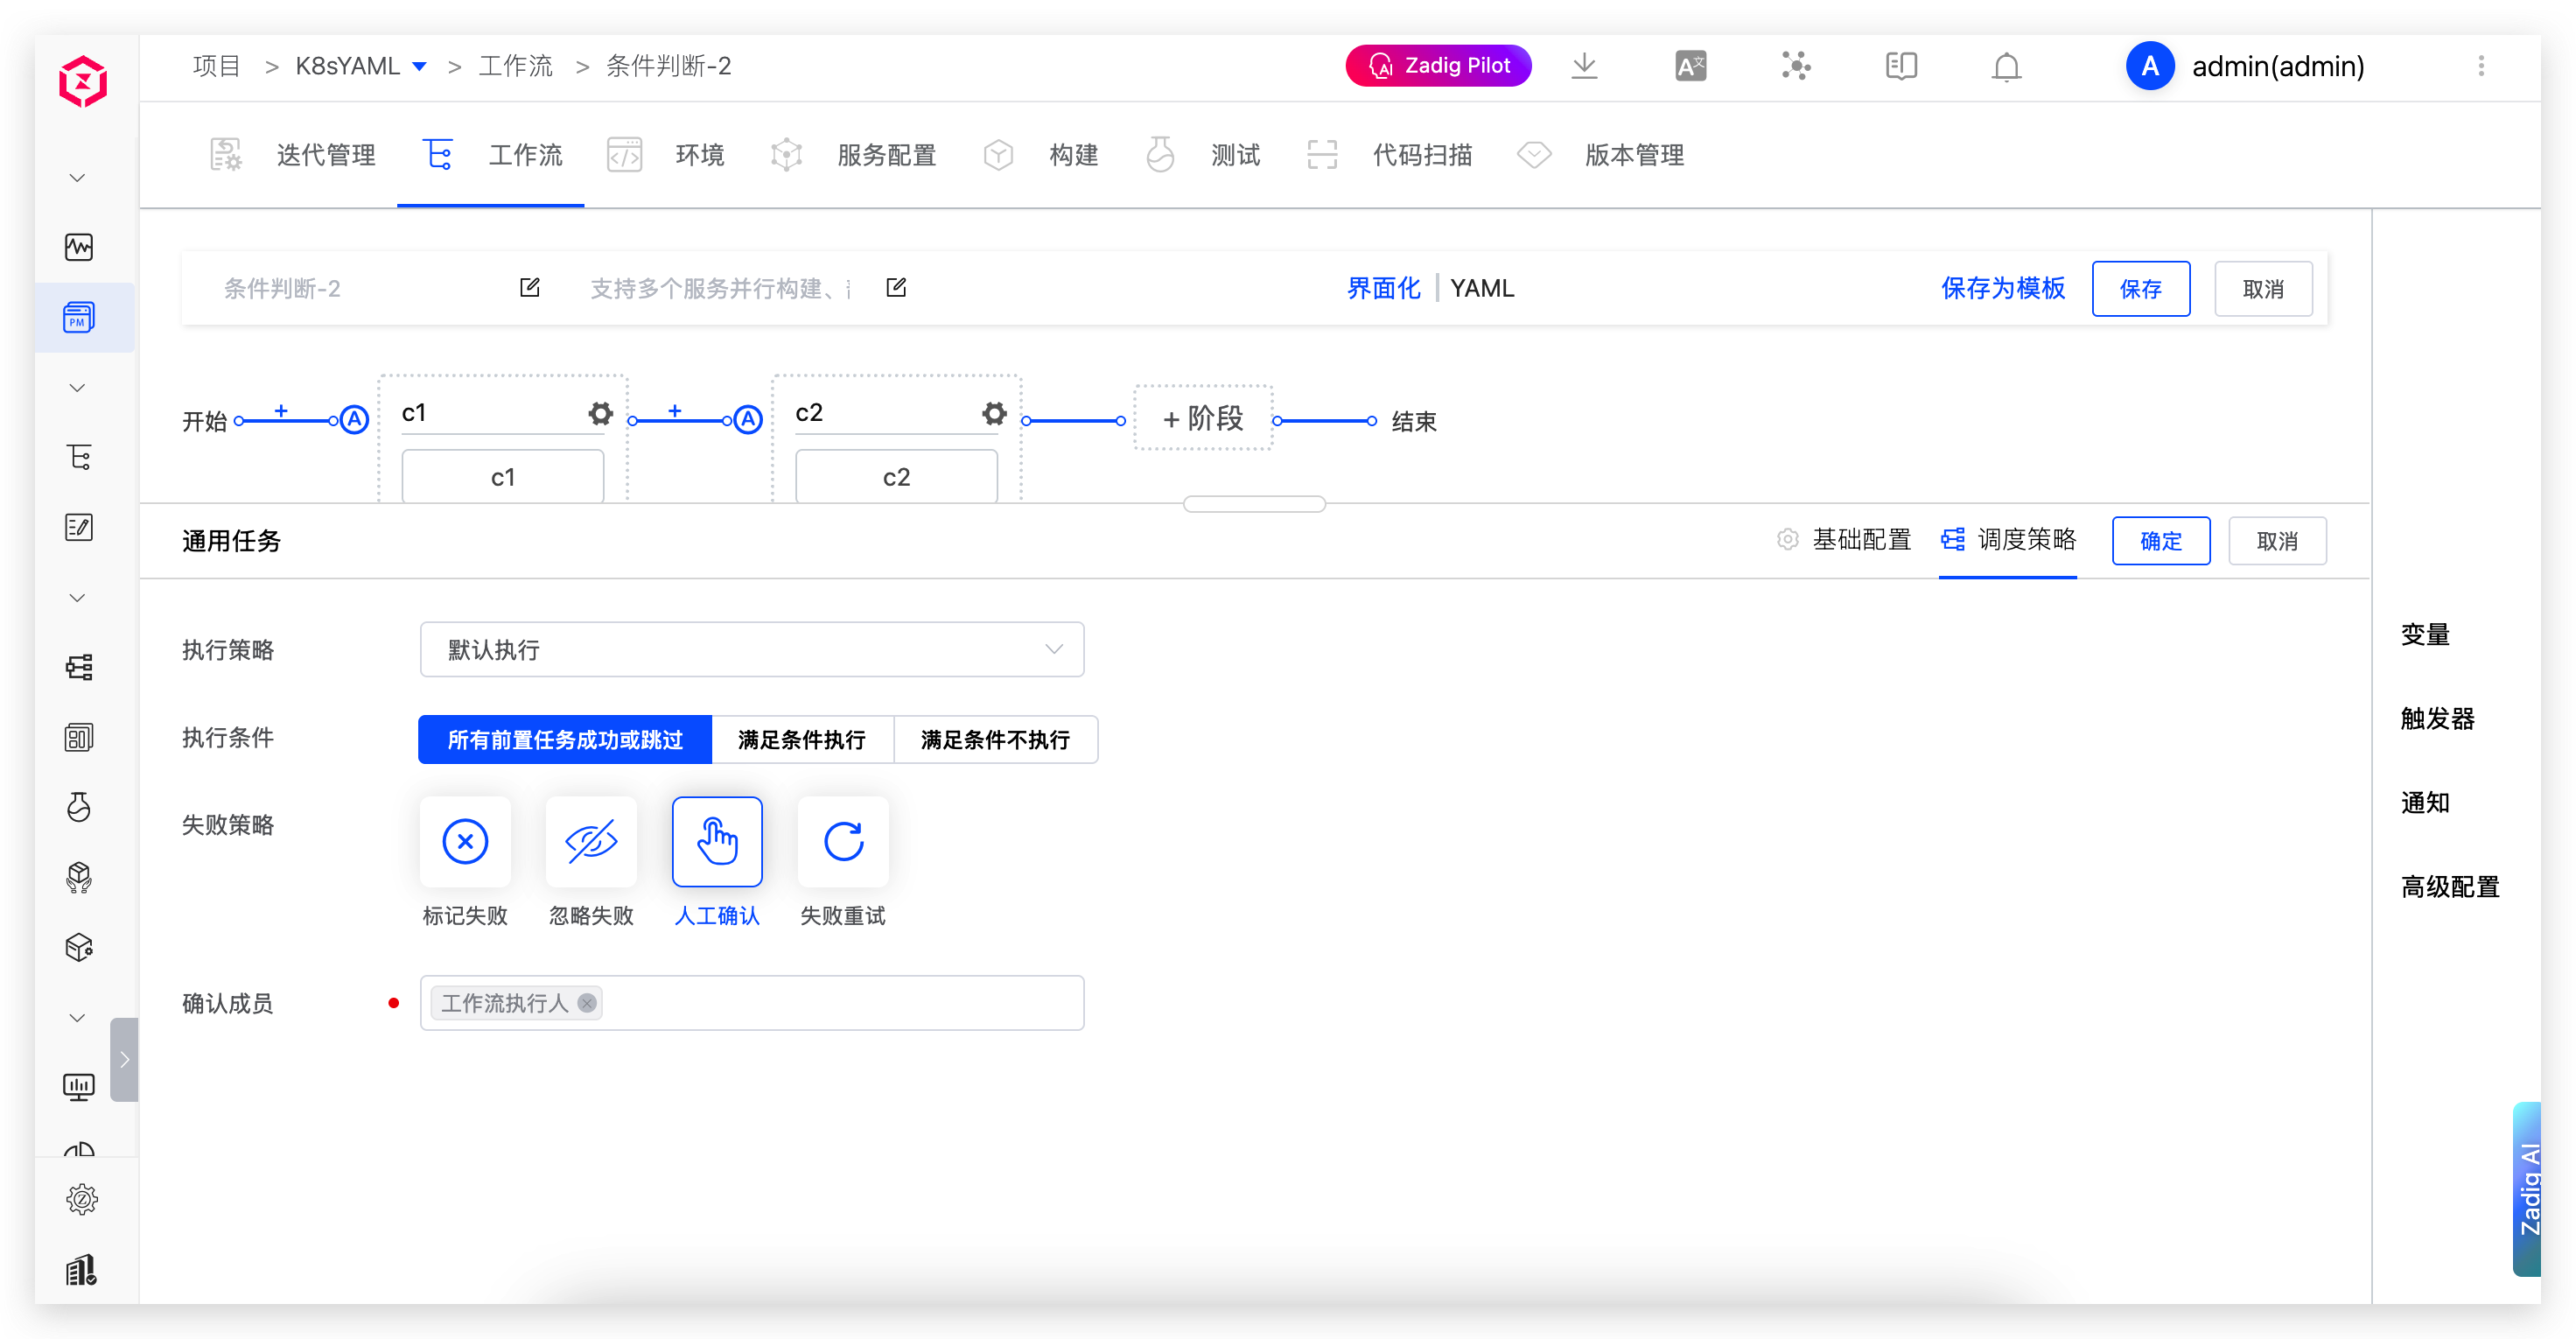
- Mark as Failed: When the job fails, the workflow stops and is marked as failed.
- Ignore Failure: When the job fails, the workflow continues.
- Manual Confirmation: When the job fails, manual confirmation is required to decide whether to
Skipthe job orStopthe workflow. - Retry on Failure: When the job fails, it can be retried automatically based on the configured retry count.
# Notifications
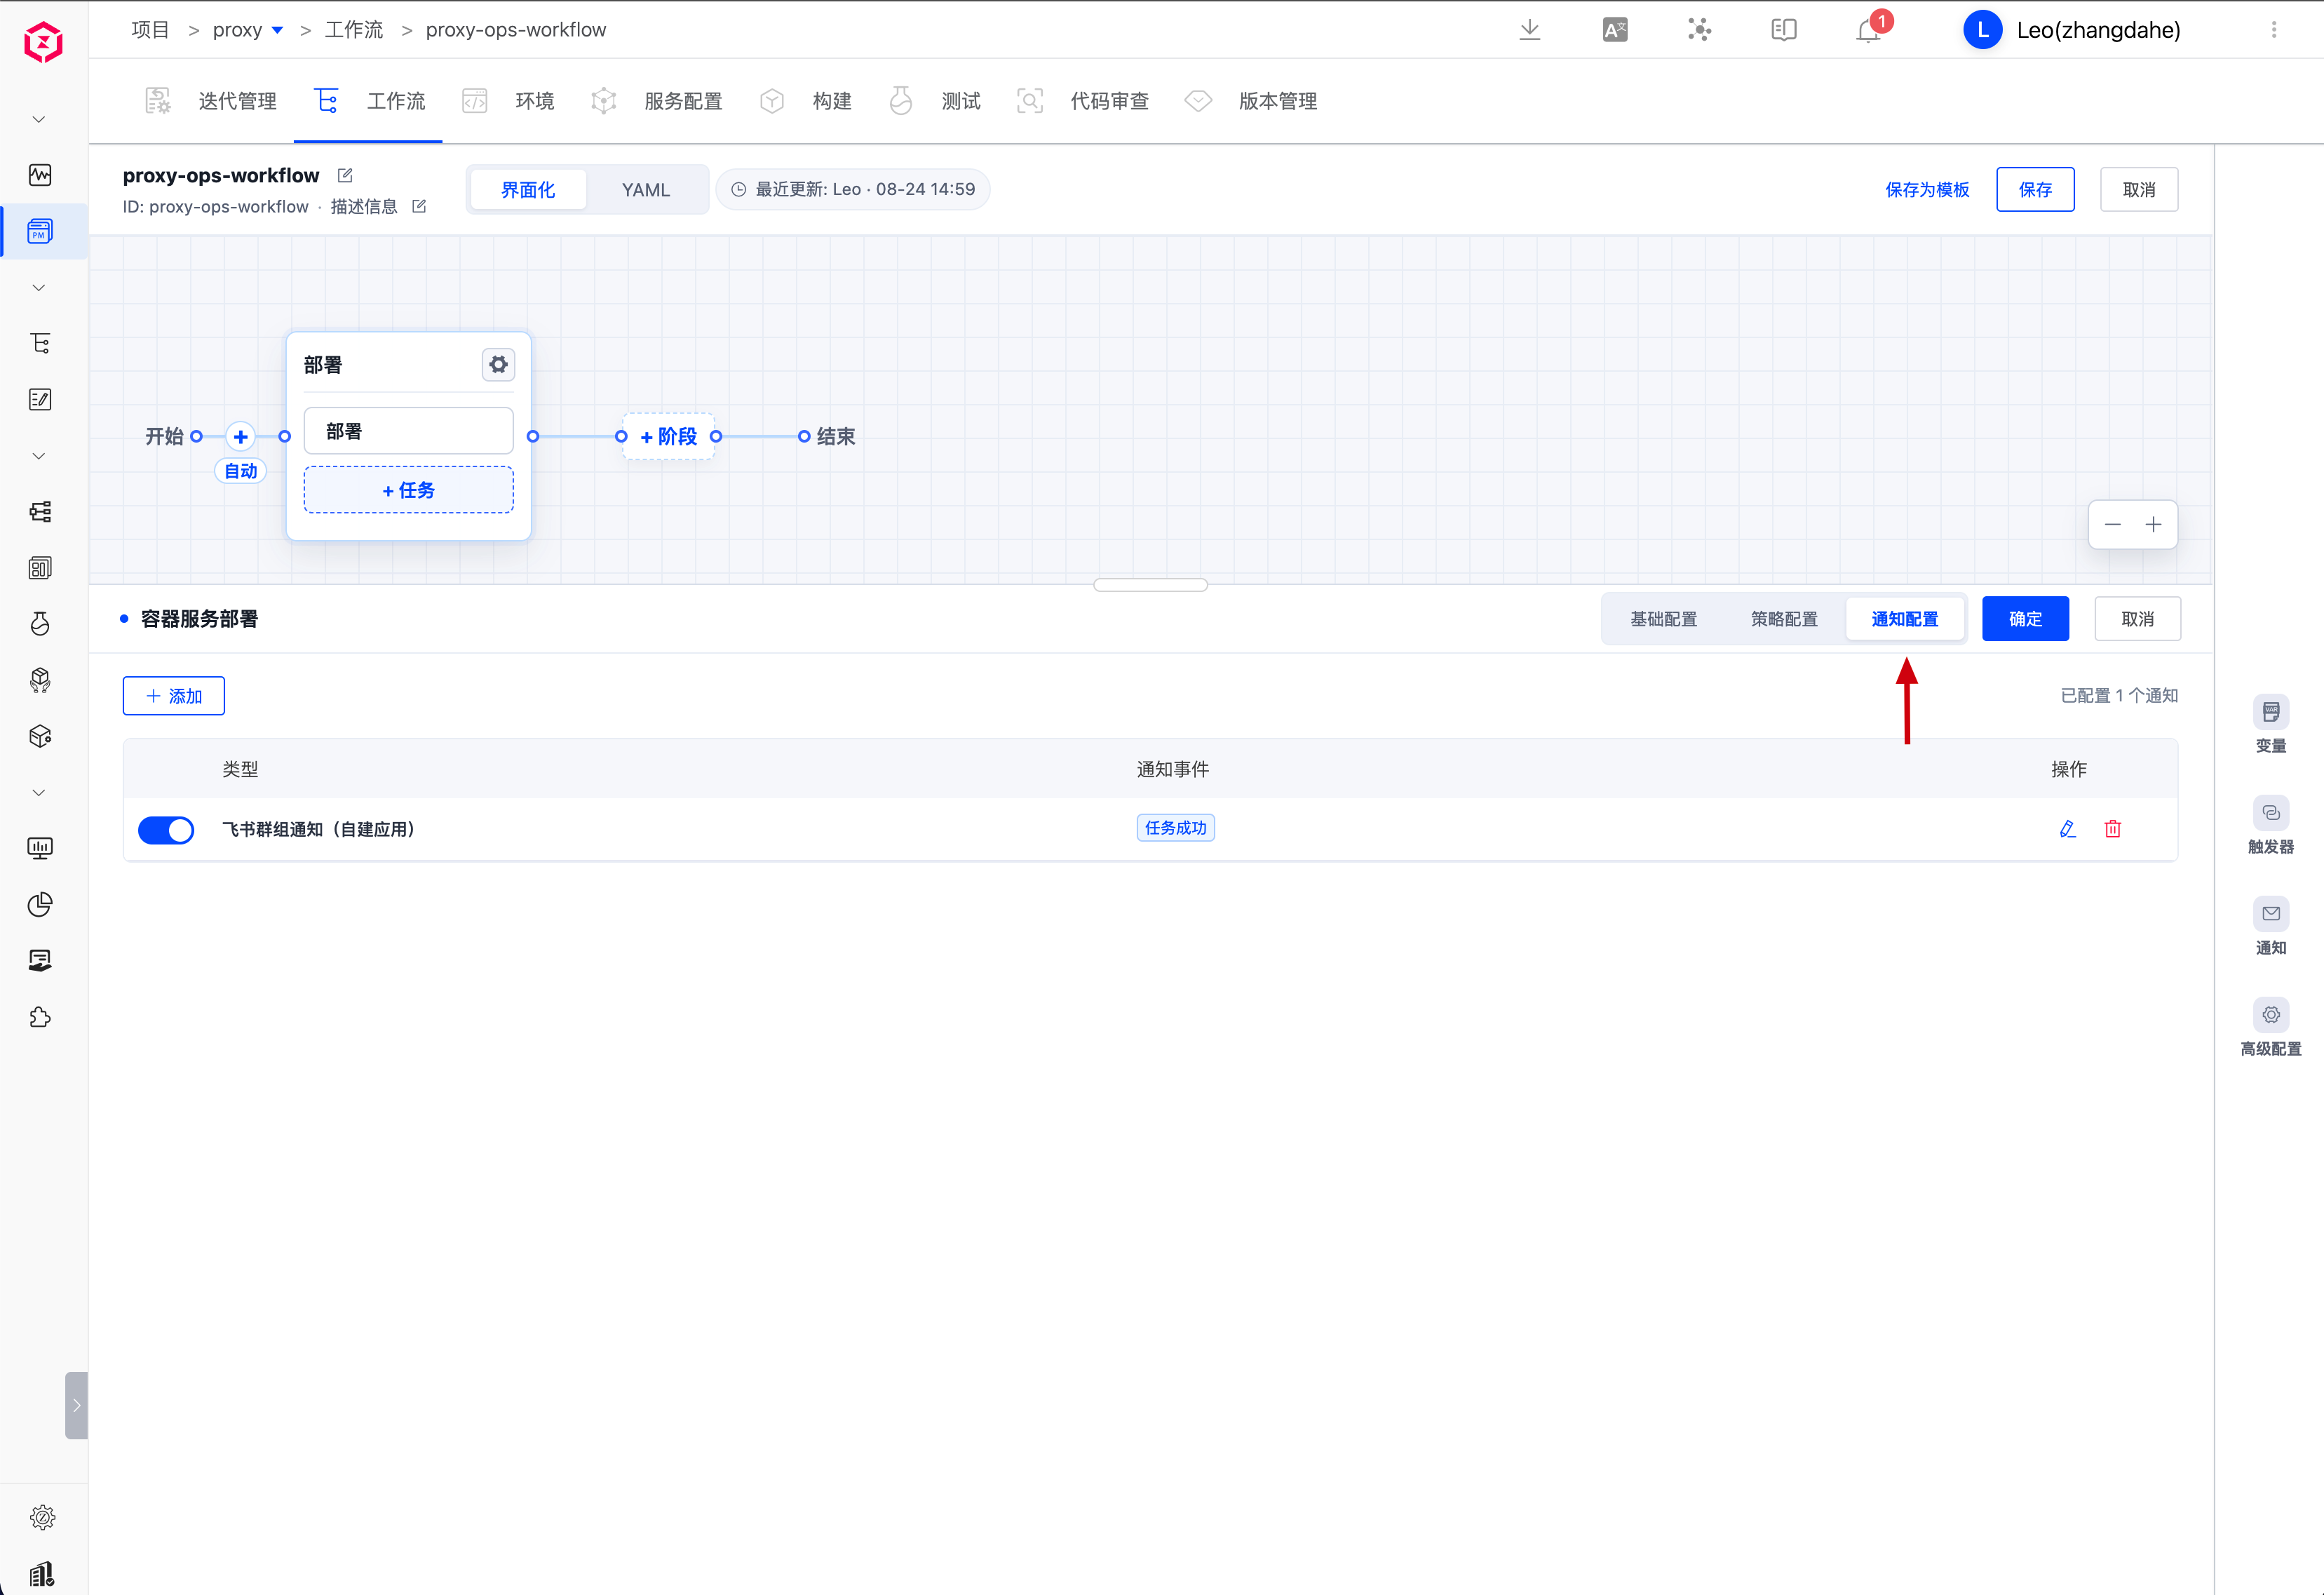
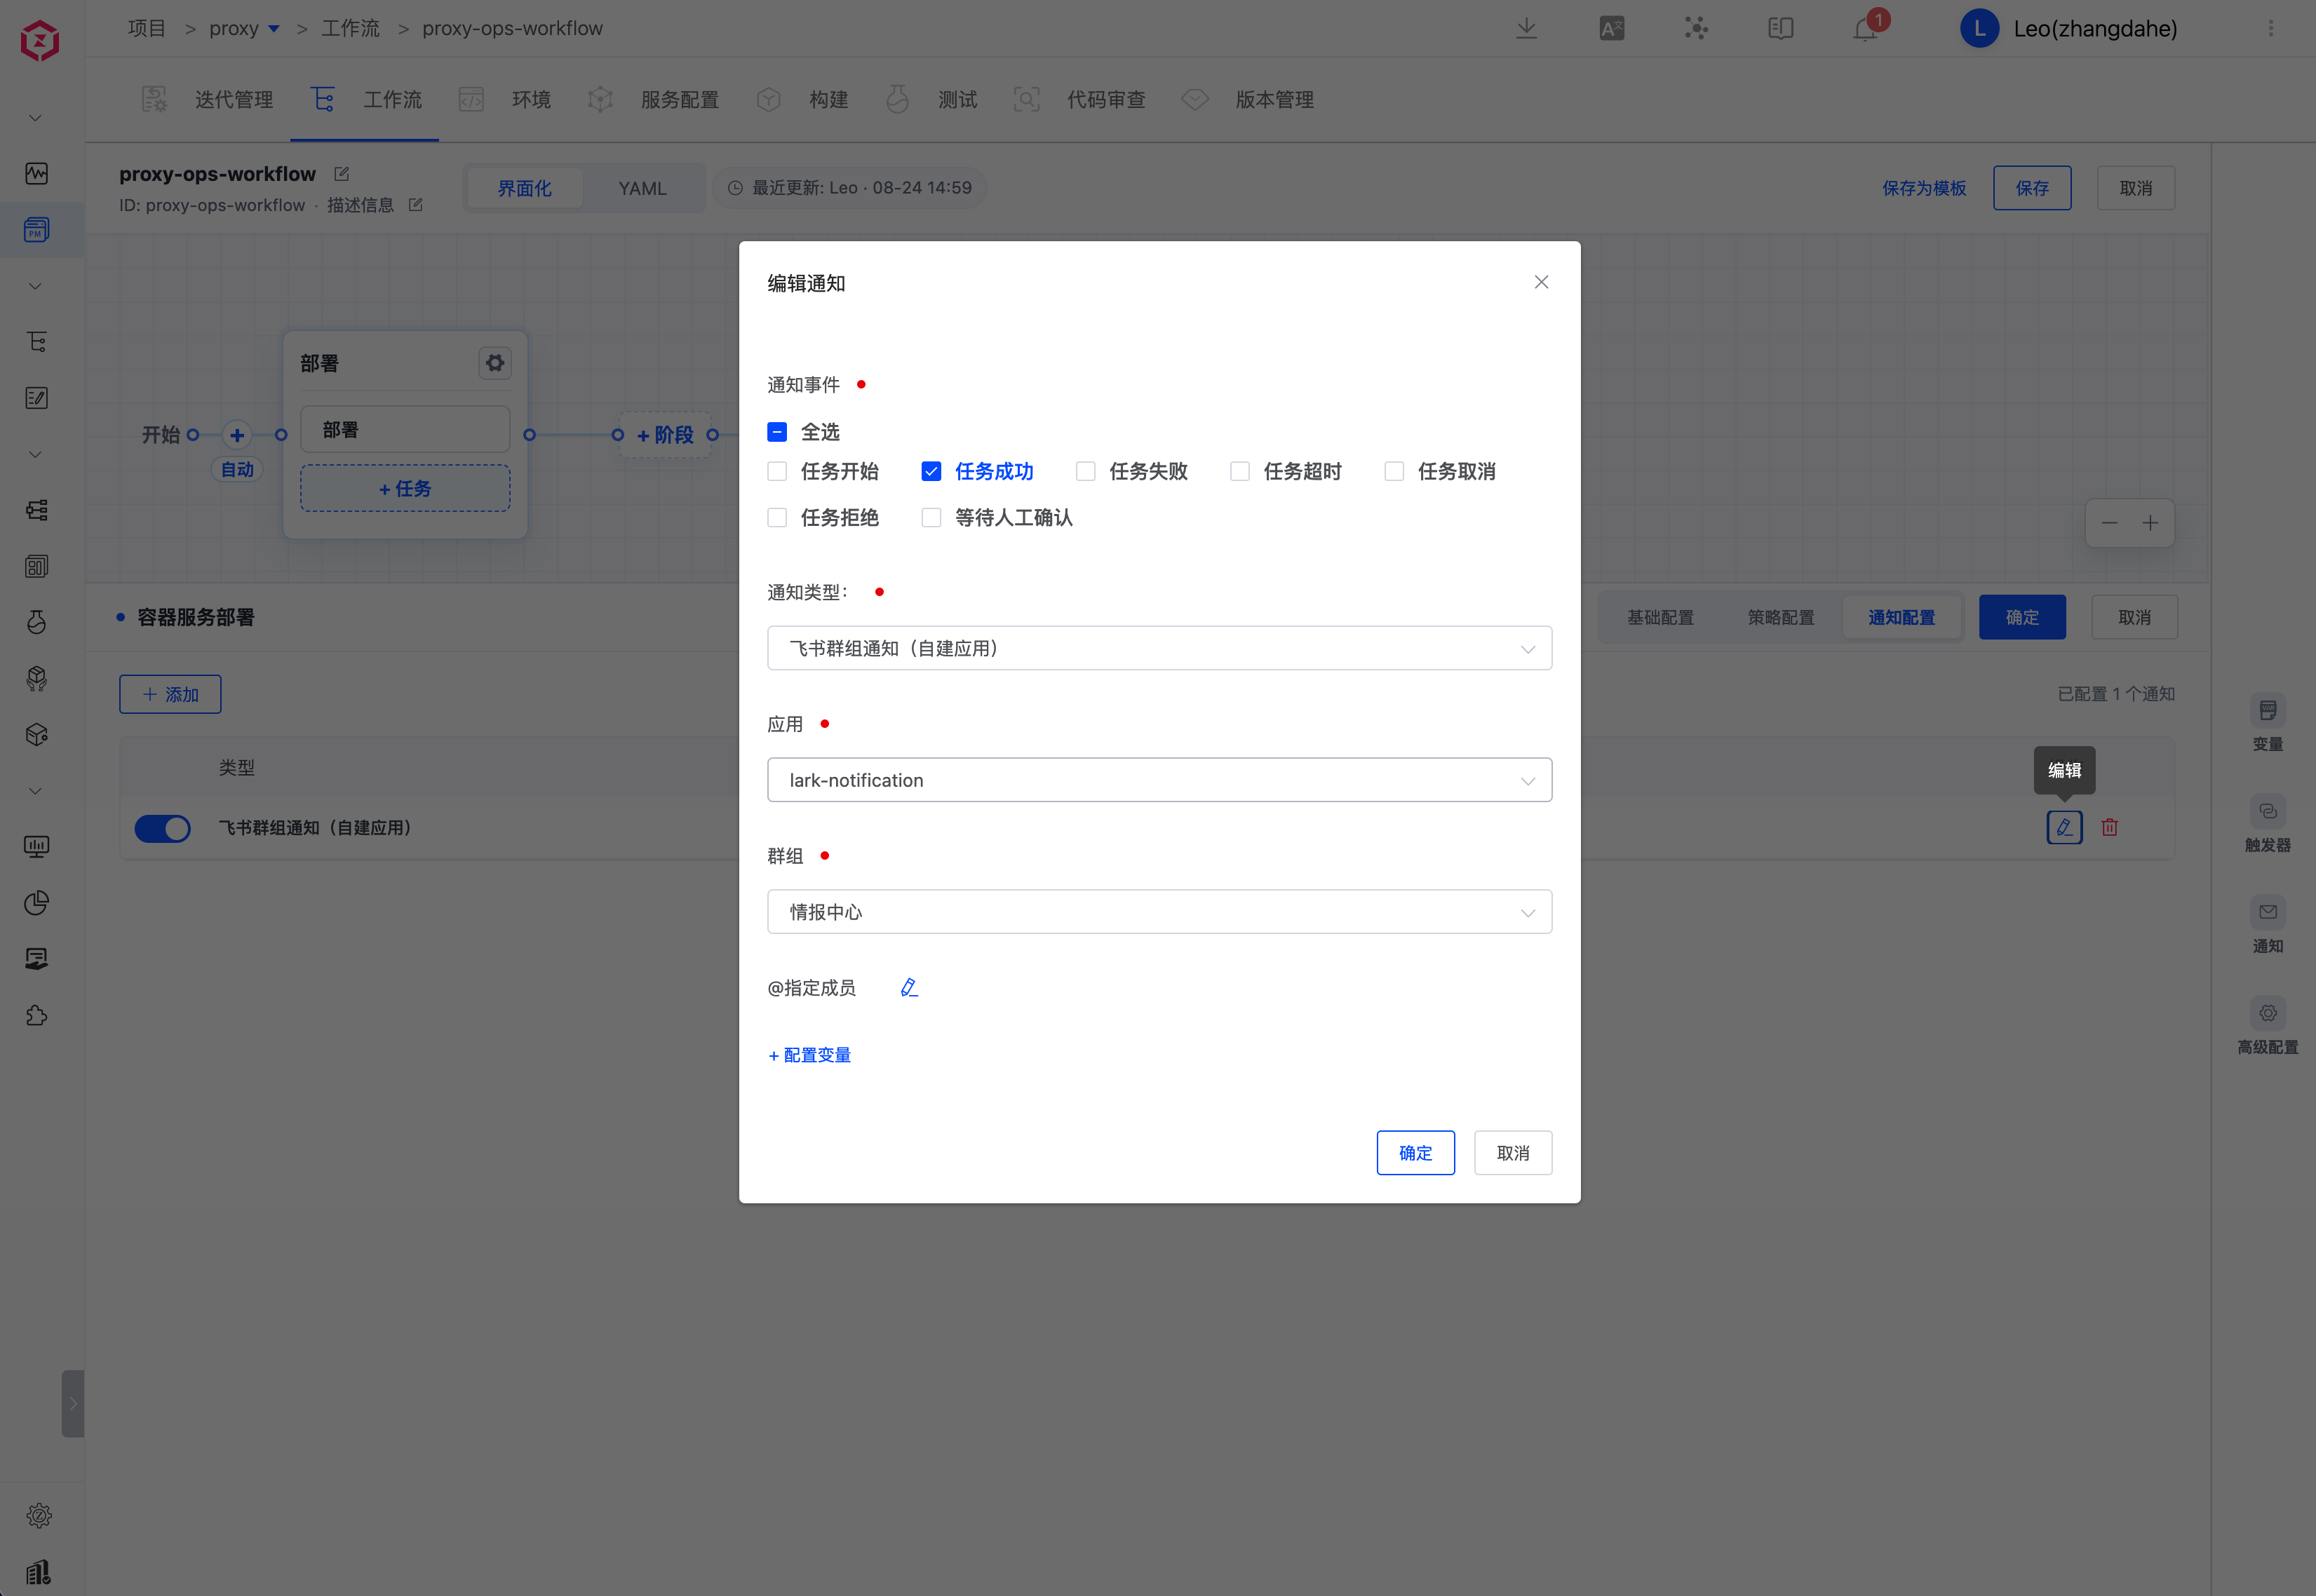
Workflow tasks can be individually configured to send notifications based on specific task statuses, such as task start, success, failure, cancellation, and more. Supported notification methods include:
# Trigger Configuration
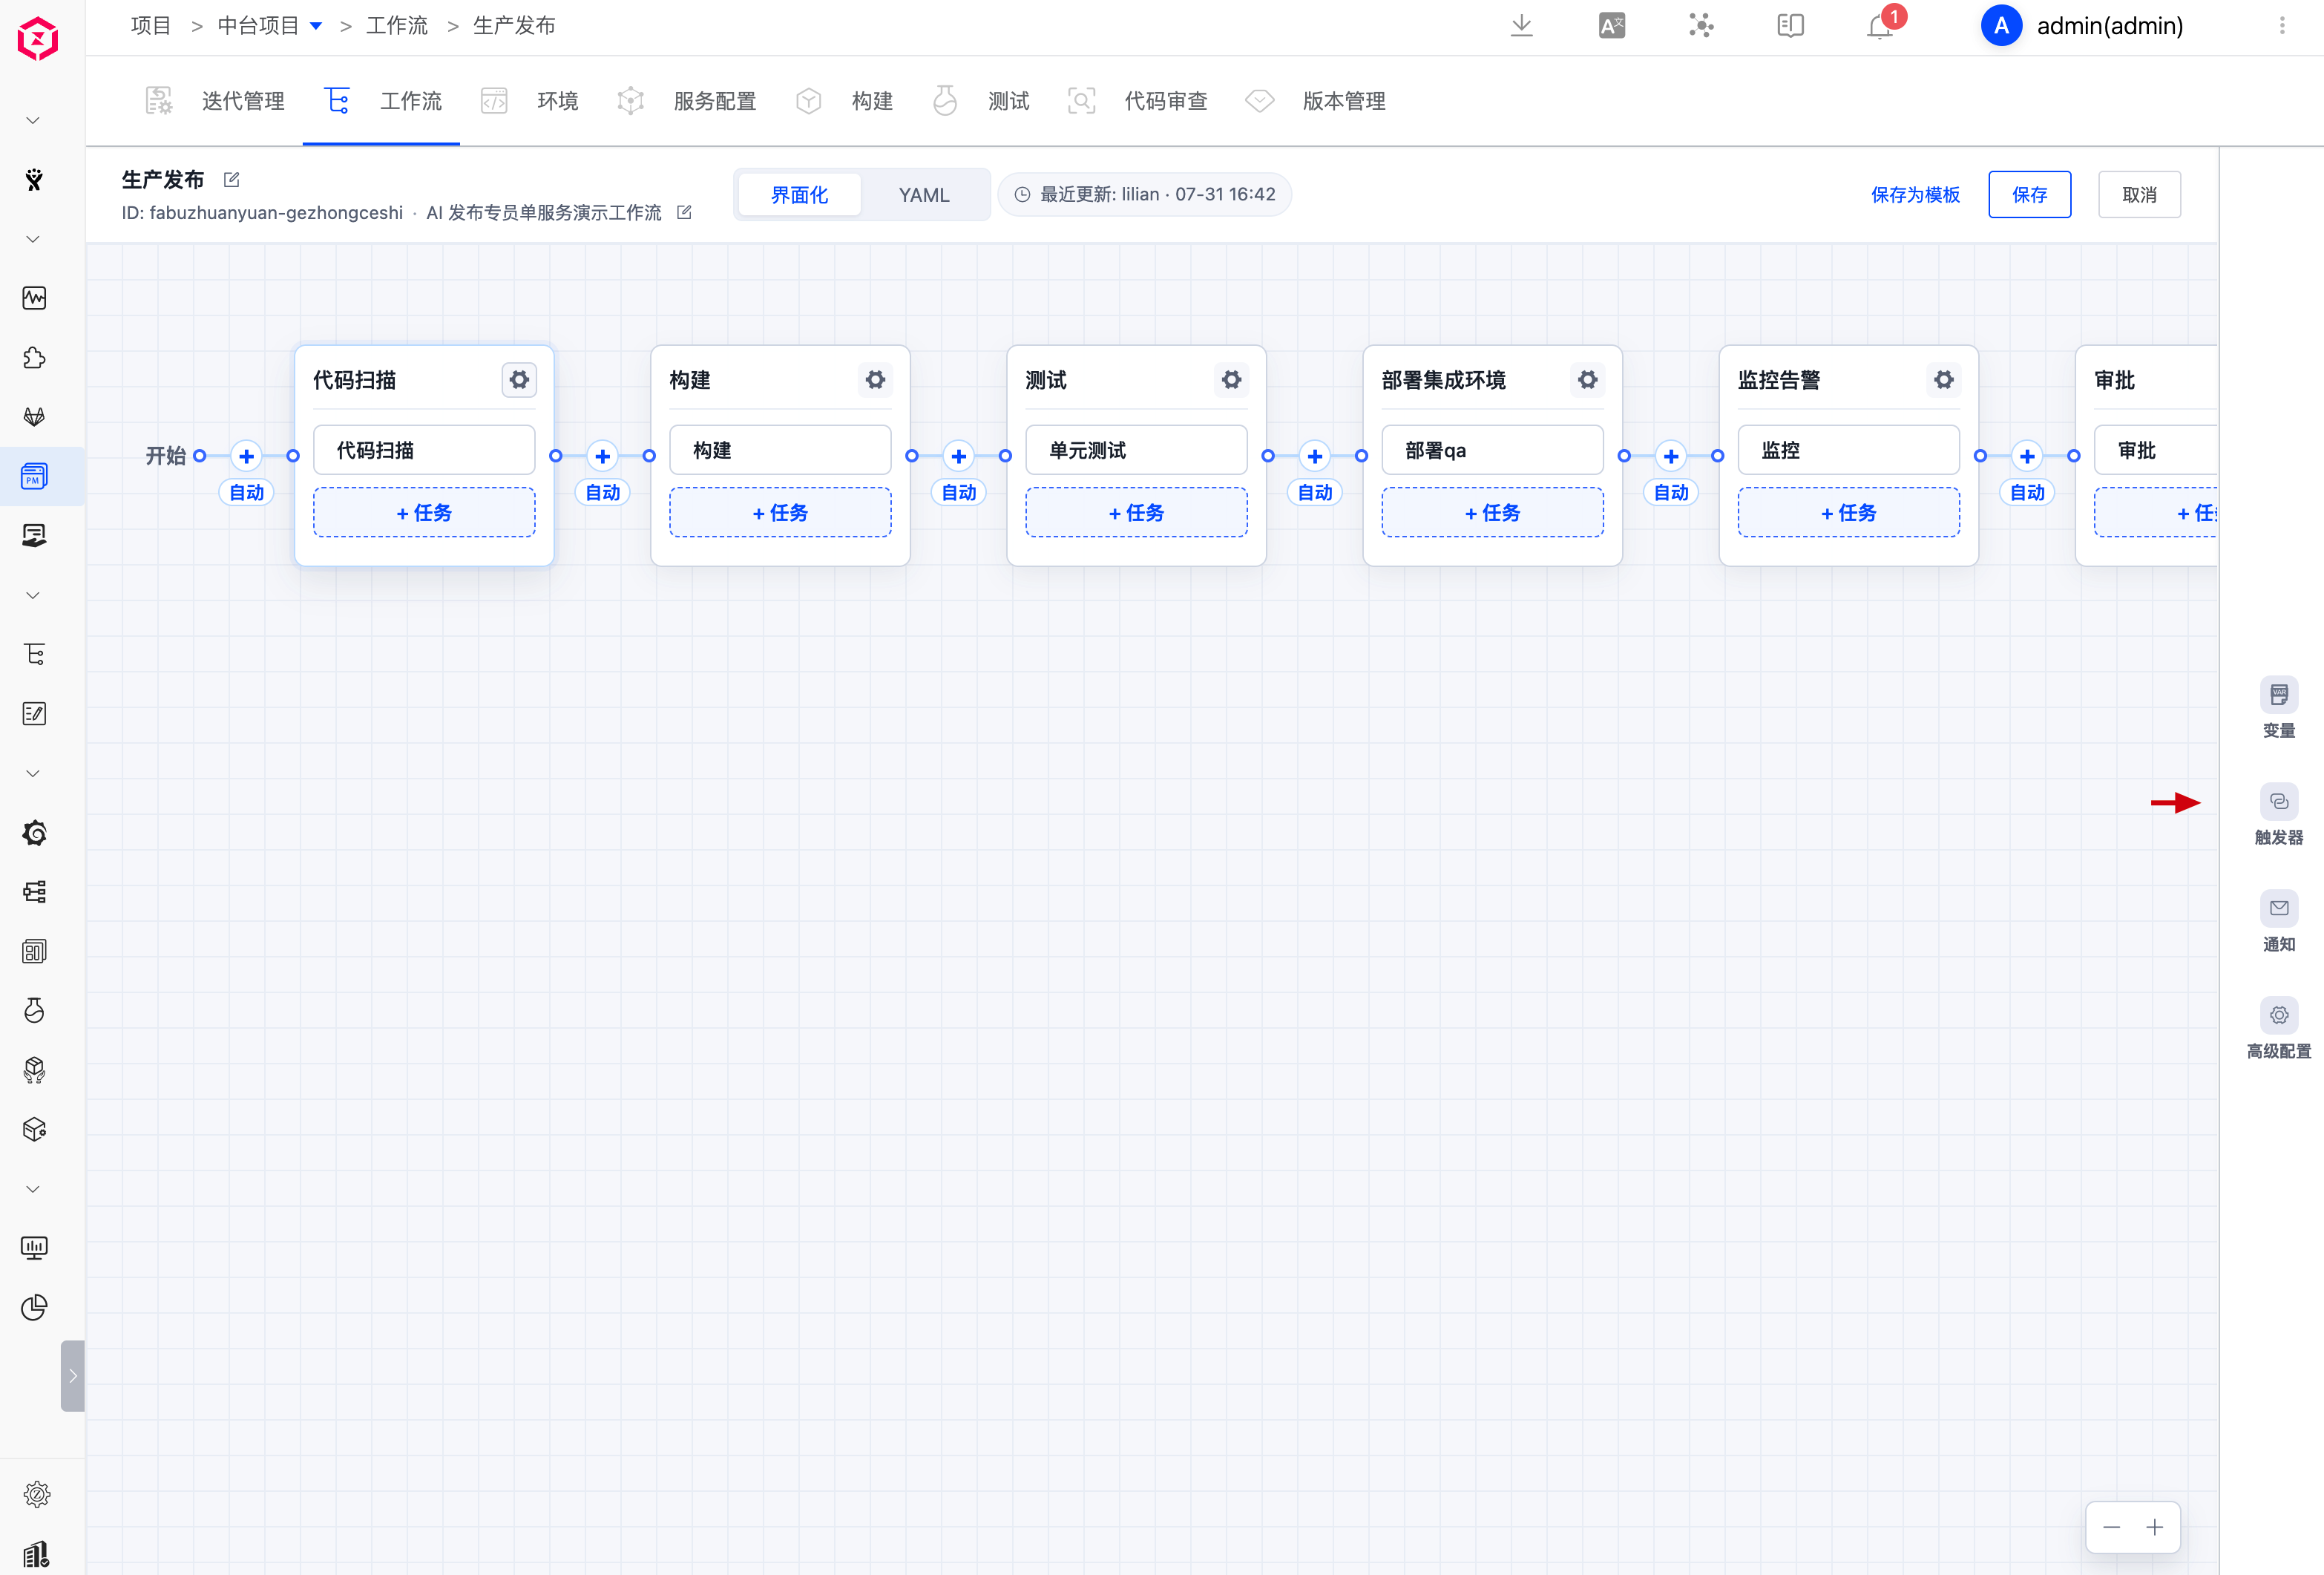
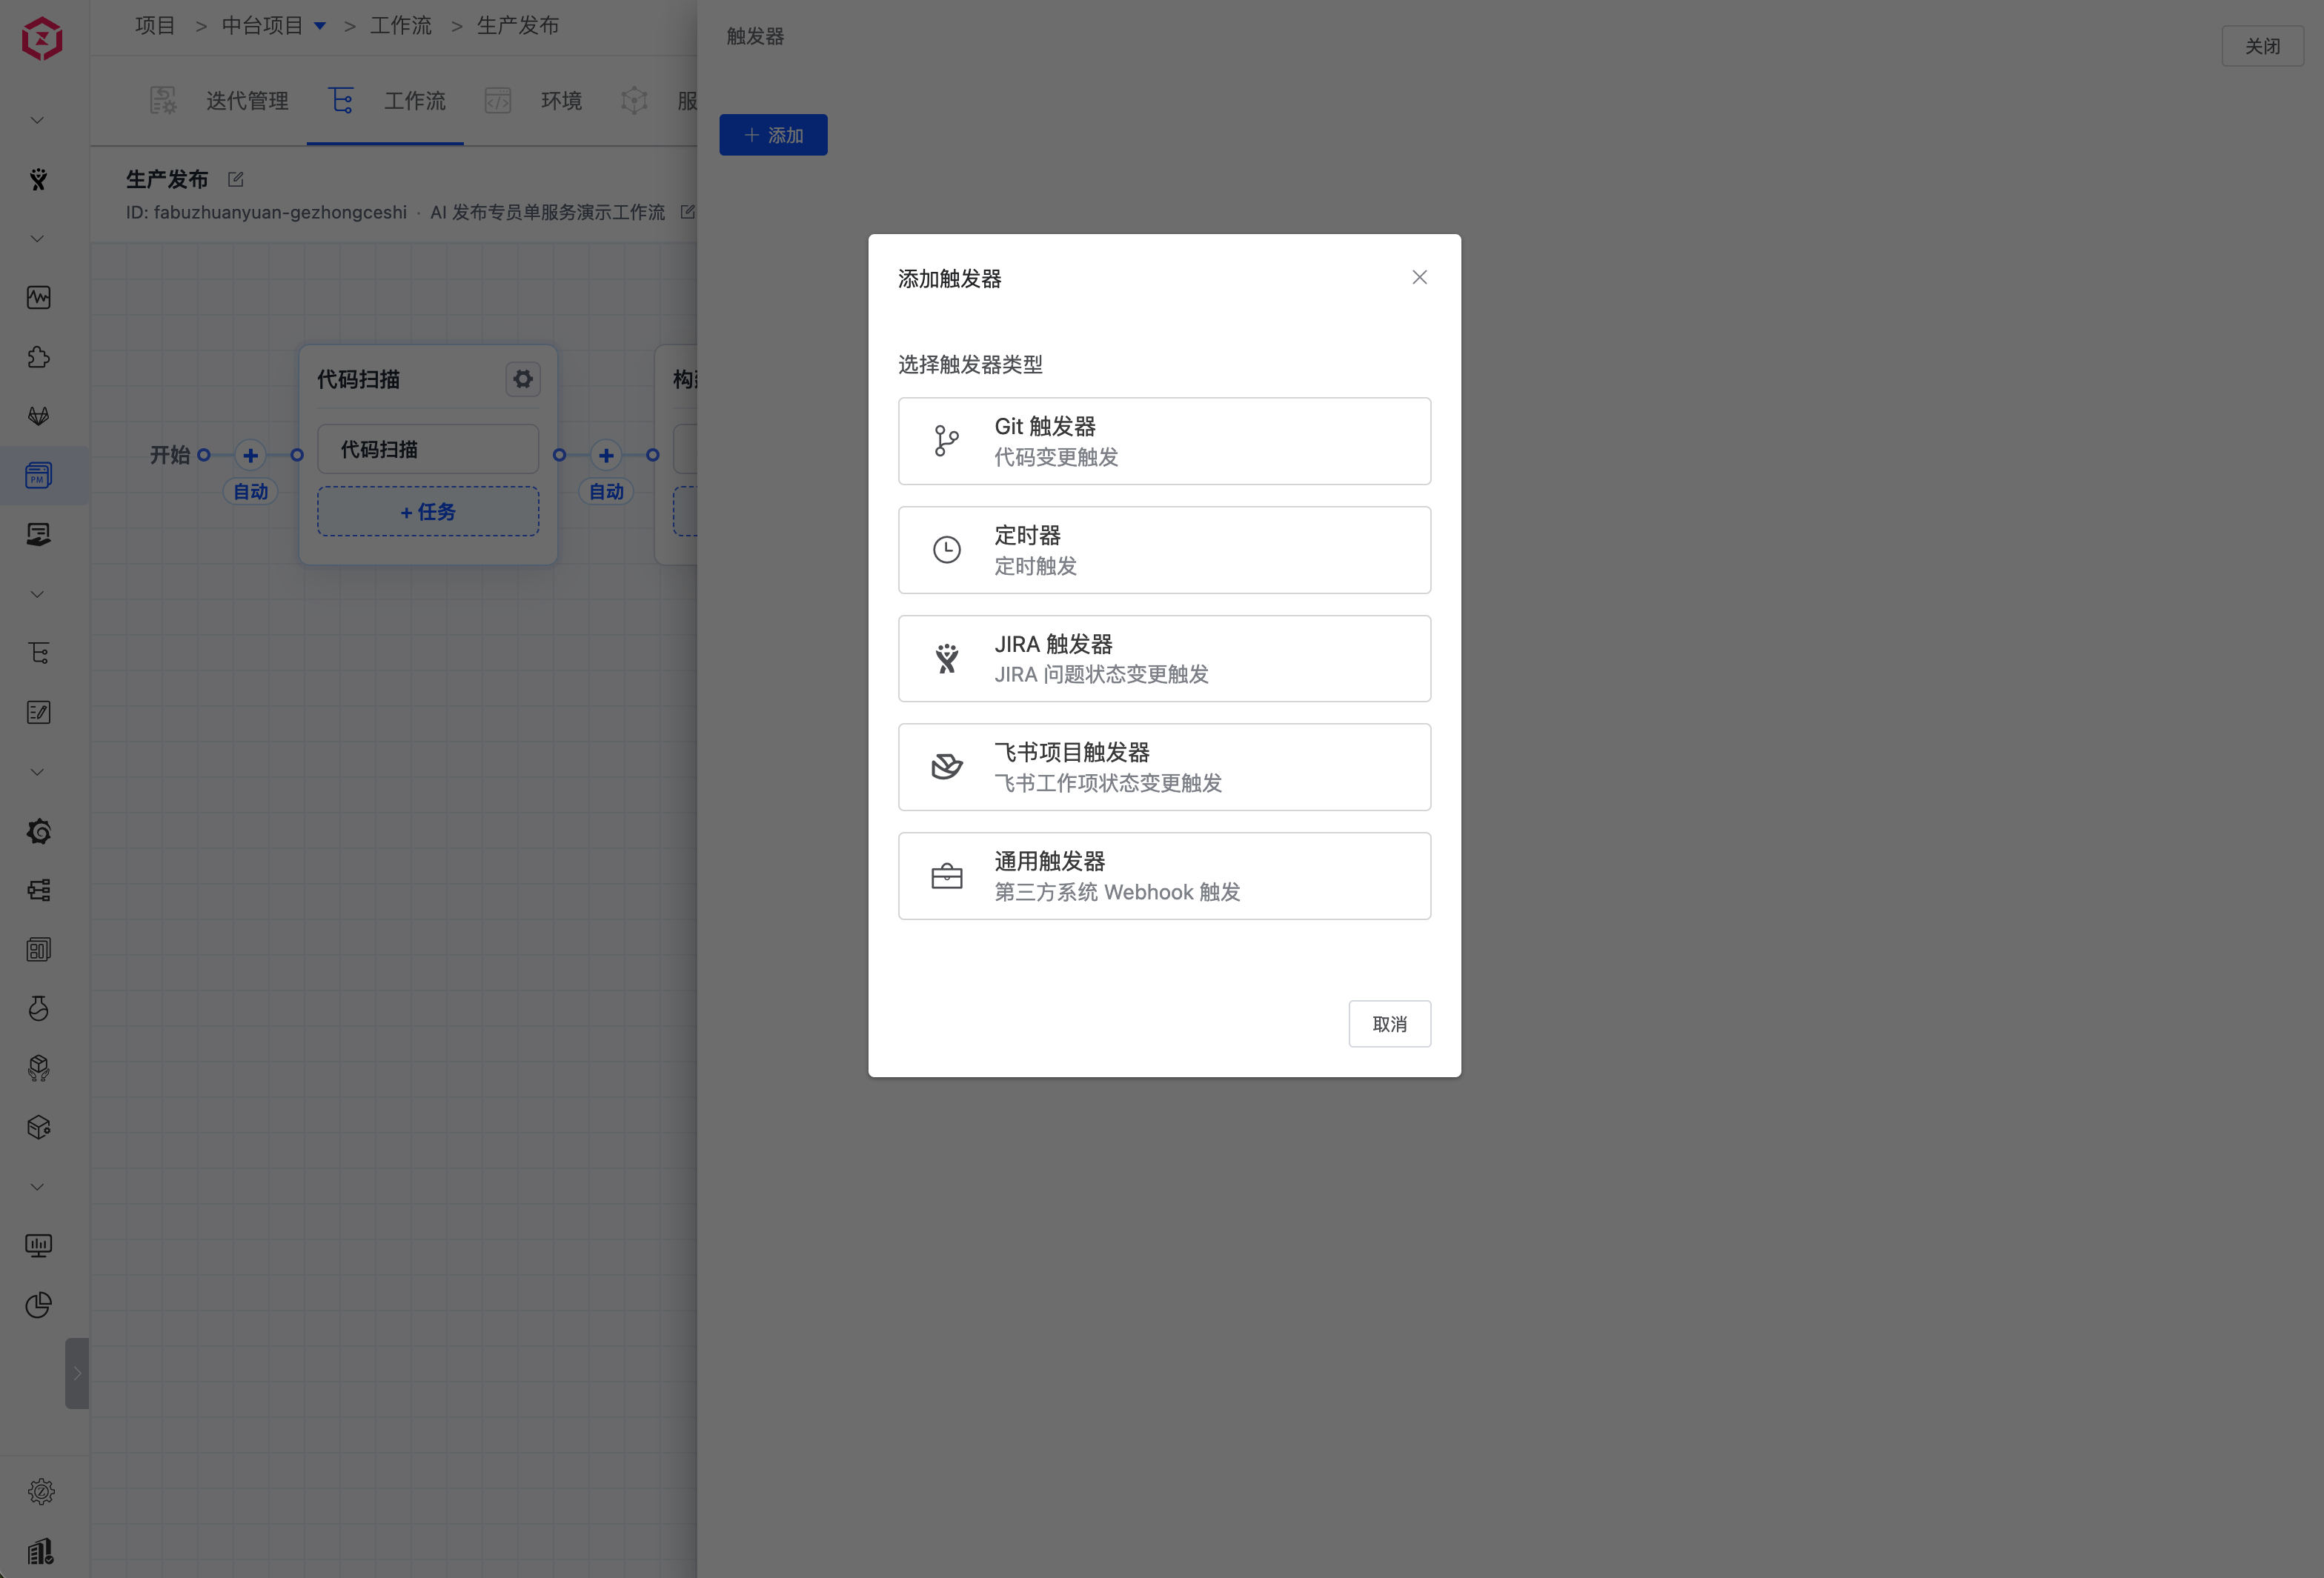
Configure triggers for a workflow. When an event that meets the trigger conditions occurs, the workflow is automatically triggered. Git triggers, timers, JIRA triggers, Feishu Project triggers, and general triggers are supported. For details, see Workflow Triggers.
# Git Trigger
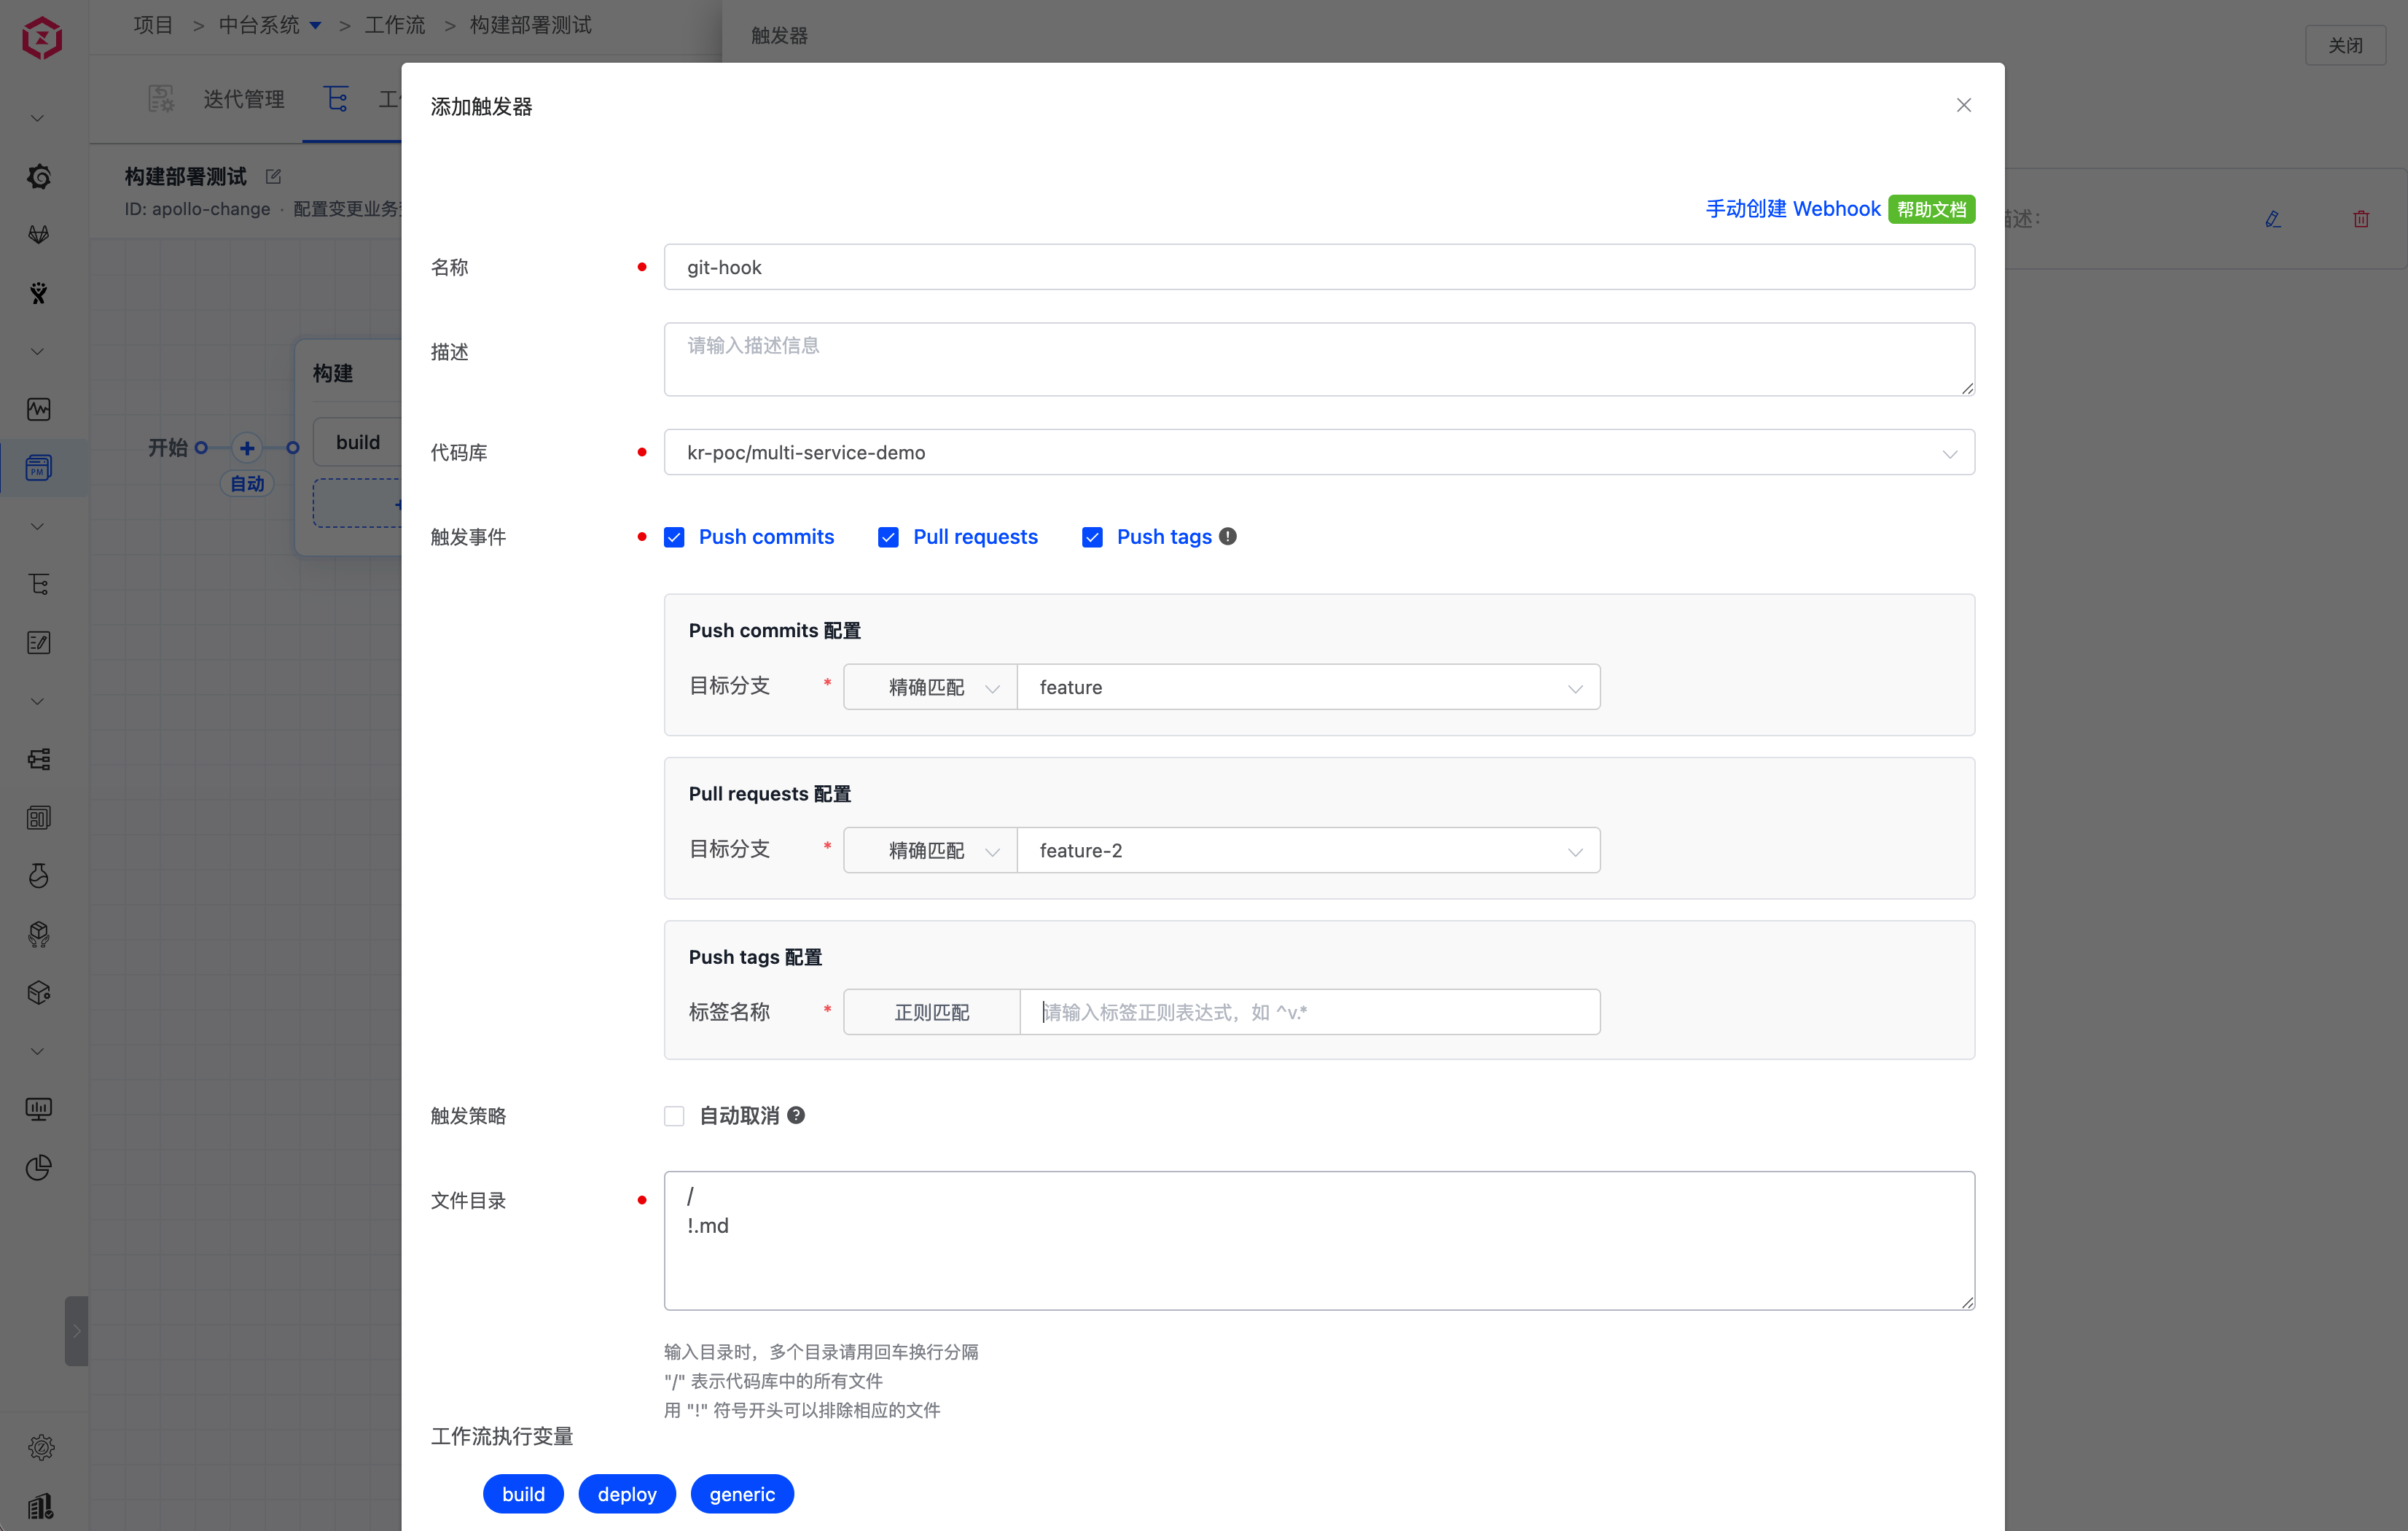
Parameter description:
Repository: The code repository whose trigger events need to be monitored. Different code sources correspond to different trigger events.Target Branch: The base branch when submitting a pull request. Regular expressions are supported. For syntax, see Regexp Syntax(opens new window).Trigger Event: Specifies the Webhook event that triggers workflow execution. Available events are:Push commits: Triggered by push commit events (merge operations). Changes to thedescriptionfield in the code repository are filtered and do not trigger workflow execution.Pull requests: Triggered when a pull request is submitted.Push tags: Triggered after a tag is created.
Trigger Policy: Automatic cancellation is supported forPush commitsandPull requestsevents. If you want only the latest commit to trigger execution, this option automatically cancels earlier running tasks in the queue.Files/Directories: By setting files and directories, you can monitor file and directory changes. When files or directories change (created, modified, or deleted), the workflow is triggered. You can also ignore changes to corresponding files or directories so that the workflow is not triggered.
Take the following repository file structure as an example:
├── reponame  # Repository name
  ├── Dockerfile
  ├── Makefile
  ├── README.md
  ├── src
    ├── service1/
    ├── service2/
    └── service3/
2
3
4
5
6
7
8
| Trigger Scenario | File/Directory Configuration |
|---|---|
| Any file is updated | / |
Files other than *.md are updated | /!.md |
Files outside the service1 directory are updated | /!src/service1/ |
Any file in the service1 directory is updated | src/service1/ |
Files in the src directory are updated, excluding files in the service1 directory | src!src/service1/ |
# Timer
By configuring a timer, you can run workflows periodically. Currently, workflows support the following timer modes:
- Scheduled Loop: Execute a workflow at a specified time, for example, every day at 12:00 or every Monday at 10:00.
- Interval Loop: Execute a workflow periodically, for example, every 30 minutes.
- Cron Expression: Use a standard Linux Cron expression to configure timers flexibly, for example,
"45 4 1,10,22 * *"executes a workflow task at 4:45 on the 1st, 10th, and 22nd day of each month.
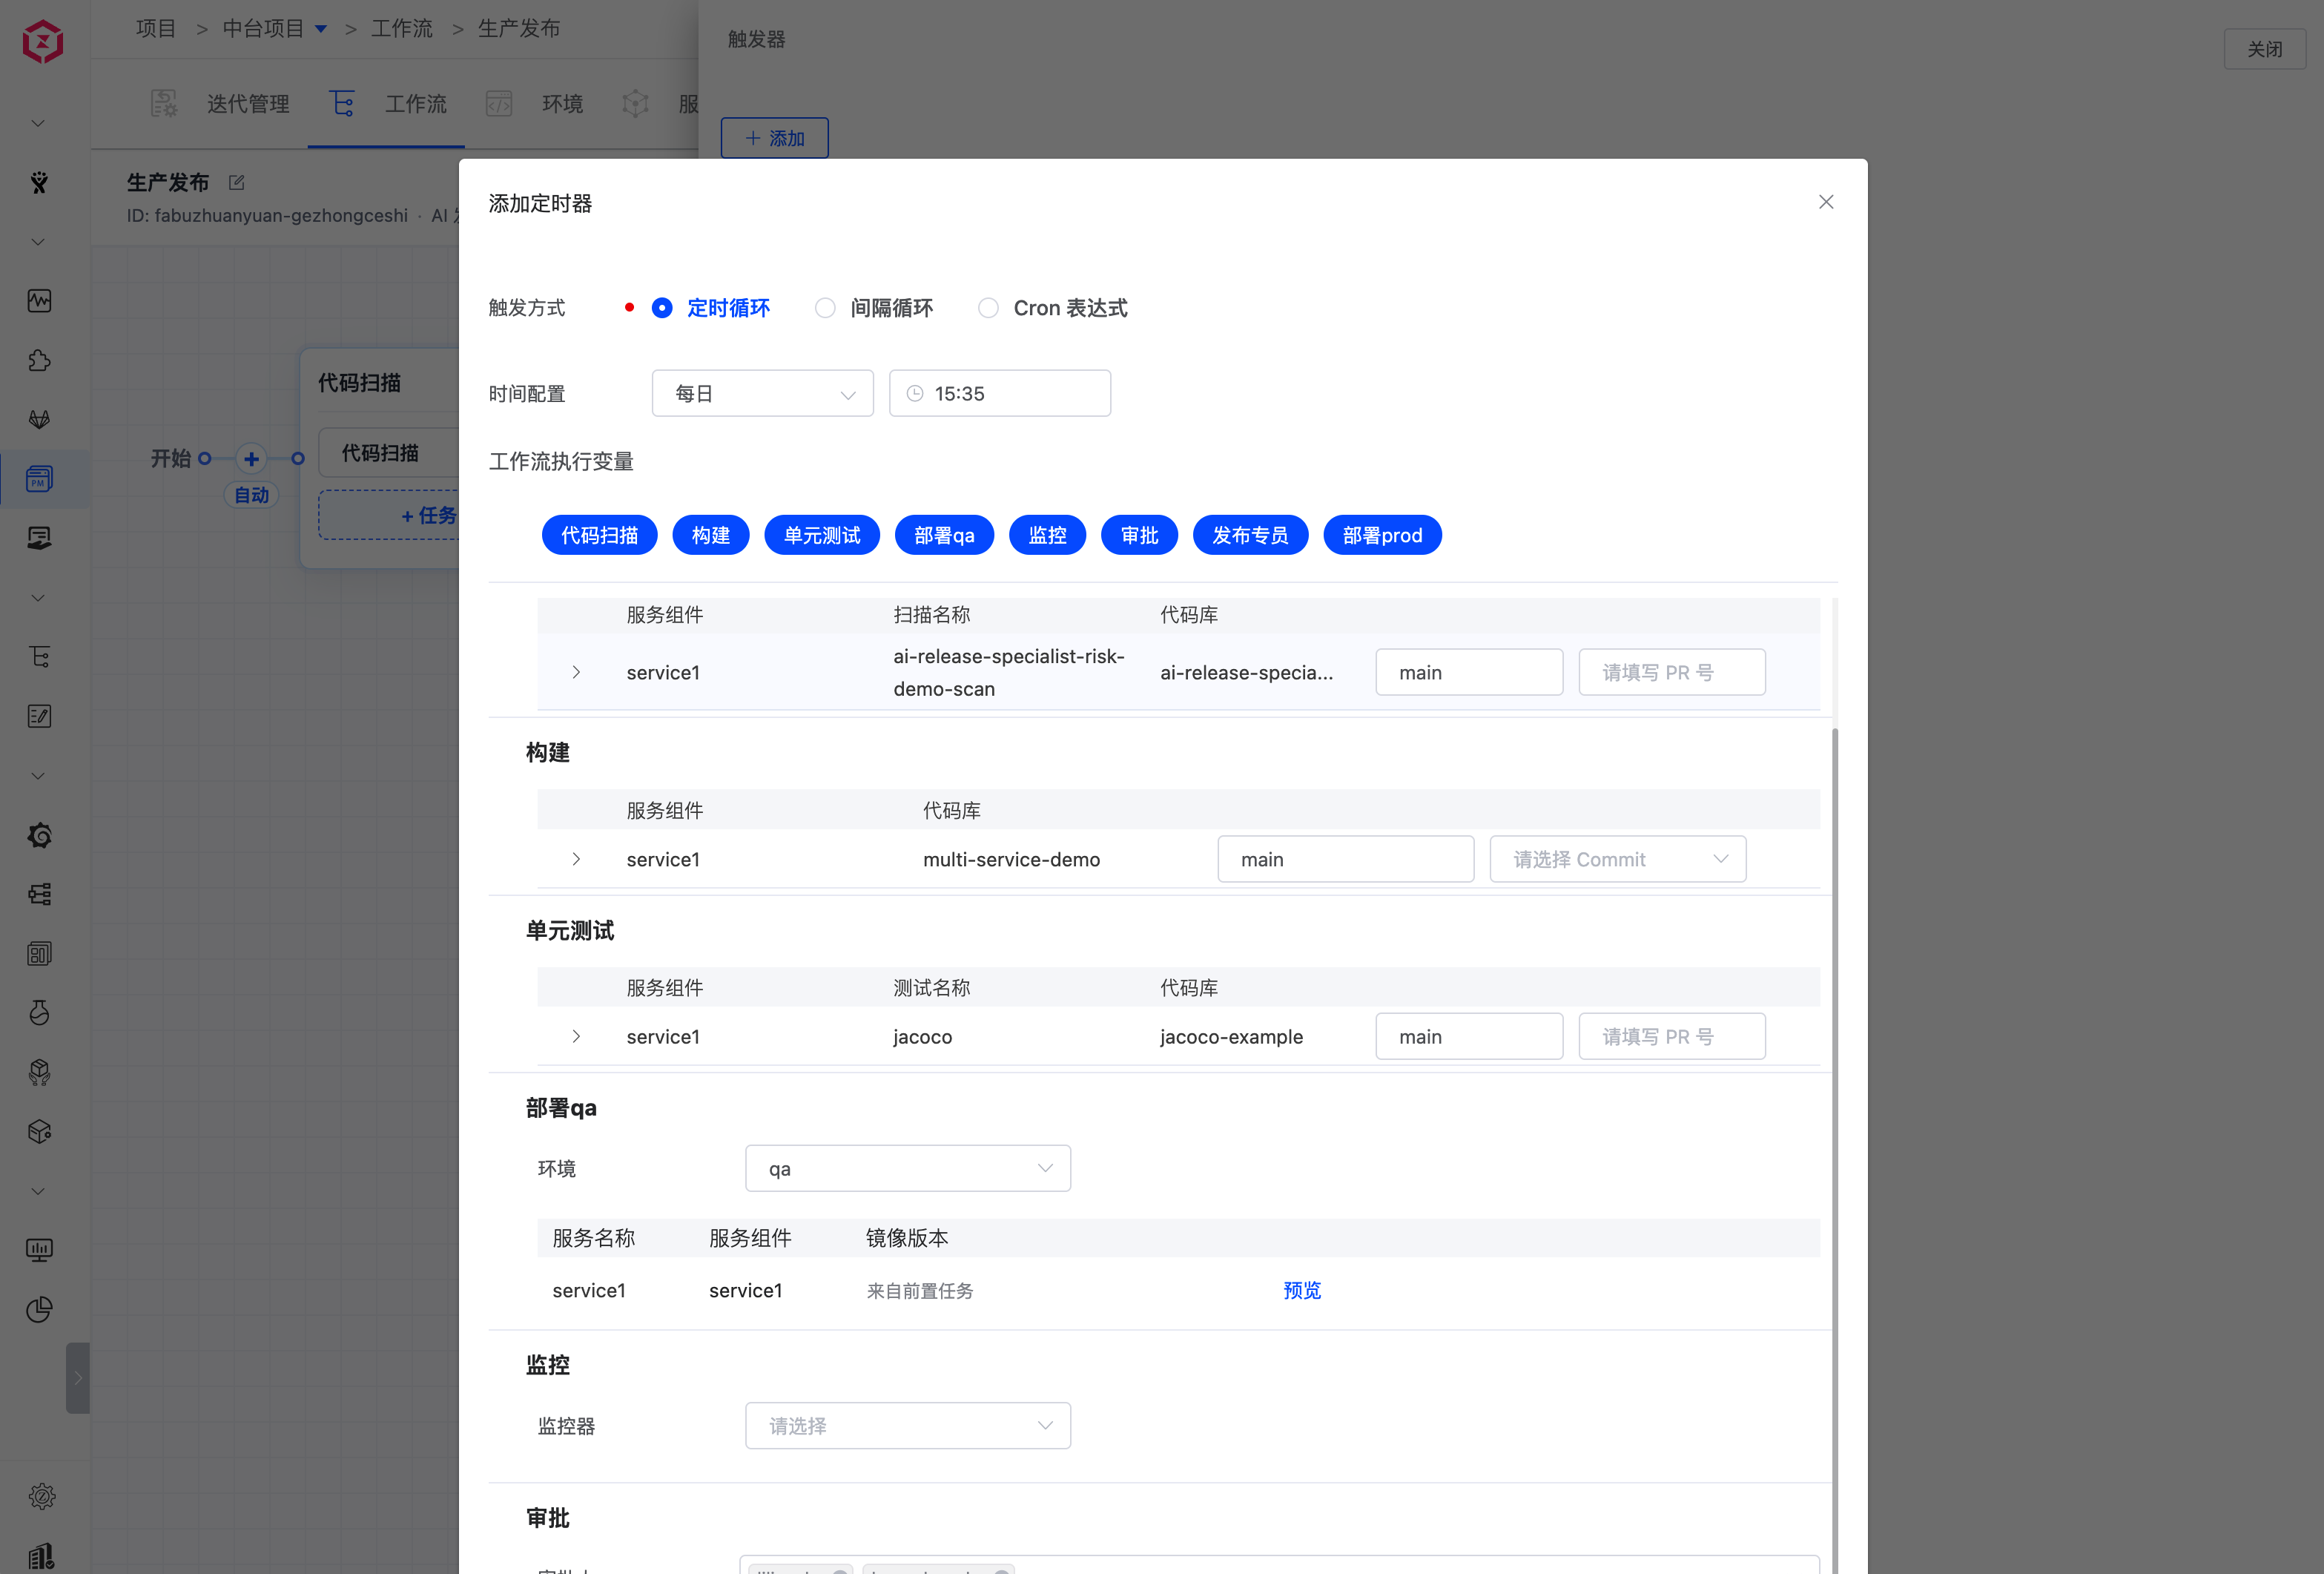
# Scheduled Loop
Procedure:
- Click the add button to add a scheduled loop entry, and select the cycle and time point.
- Set workflow task parameters. The workflow runs with the configured parameters.
# Interval Loop
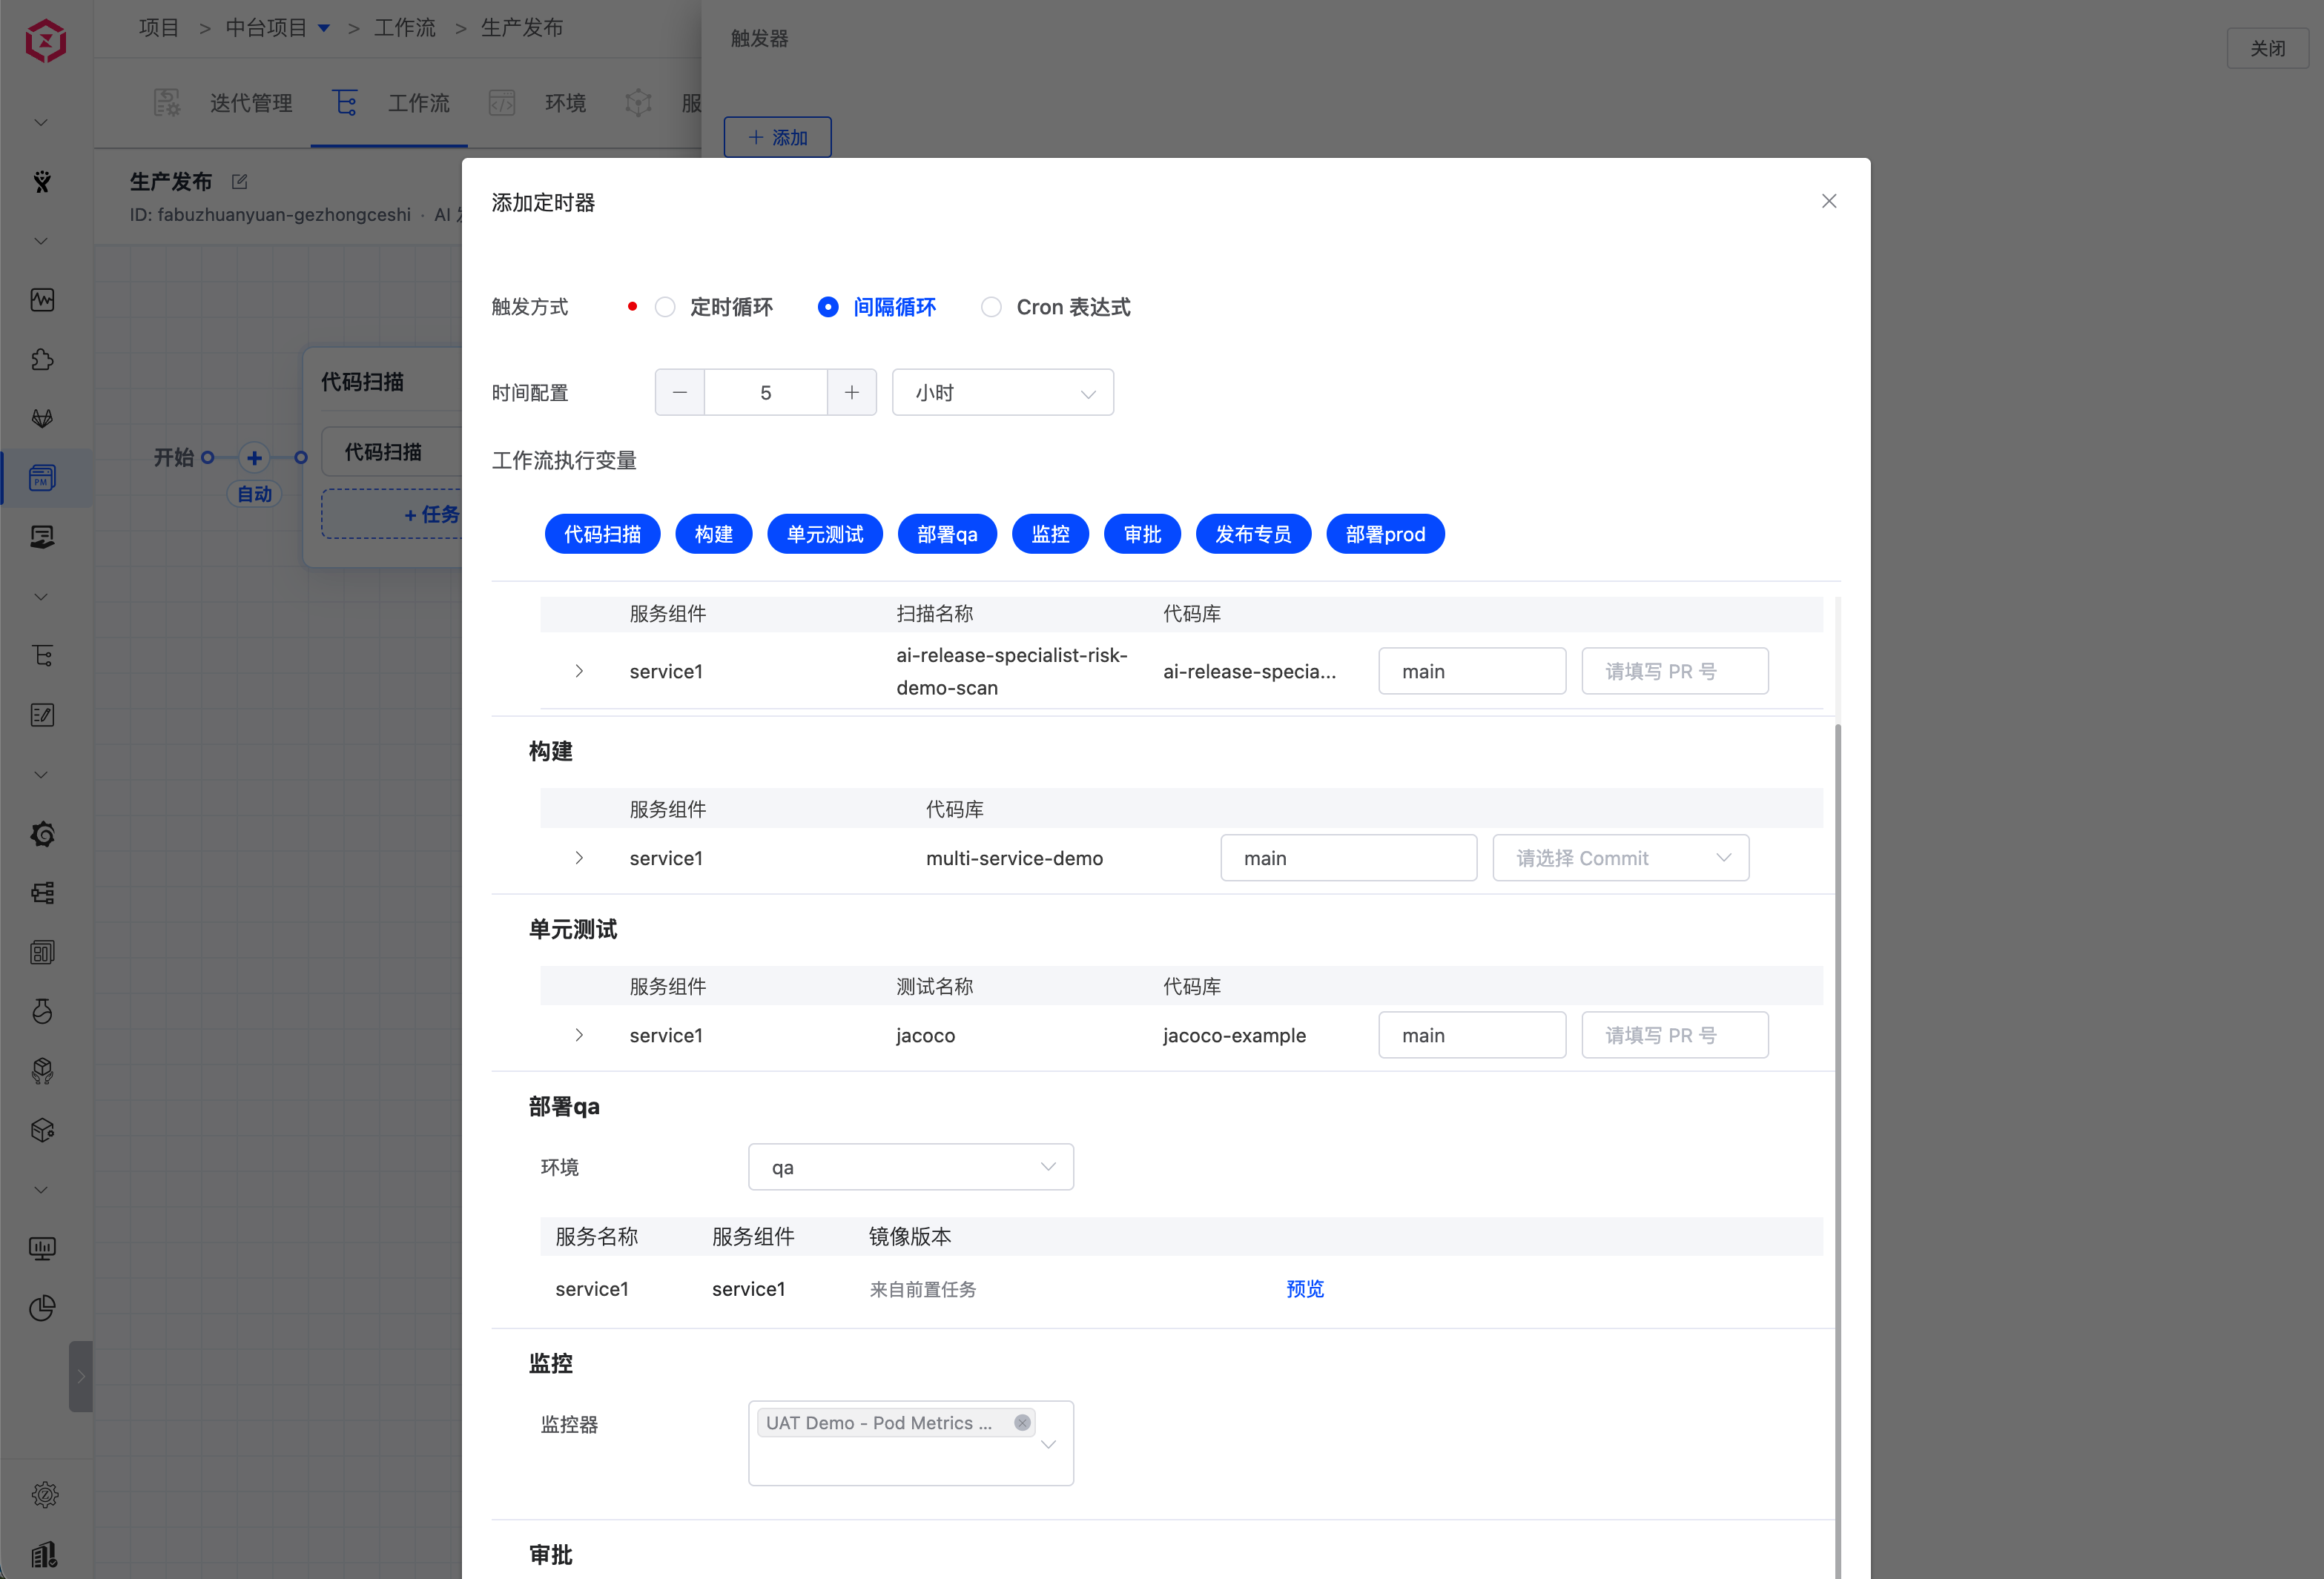
Procedure:
- Step 1: Click the add button to add an interval loop entry, and select the interval and interval unit.
- Step 2: Set workflow parameters. The workflow runs with the configured parameters.
# Cron Expression
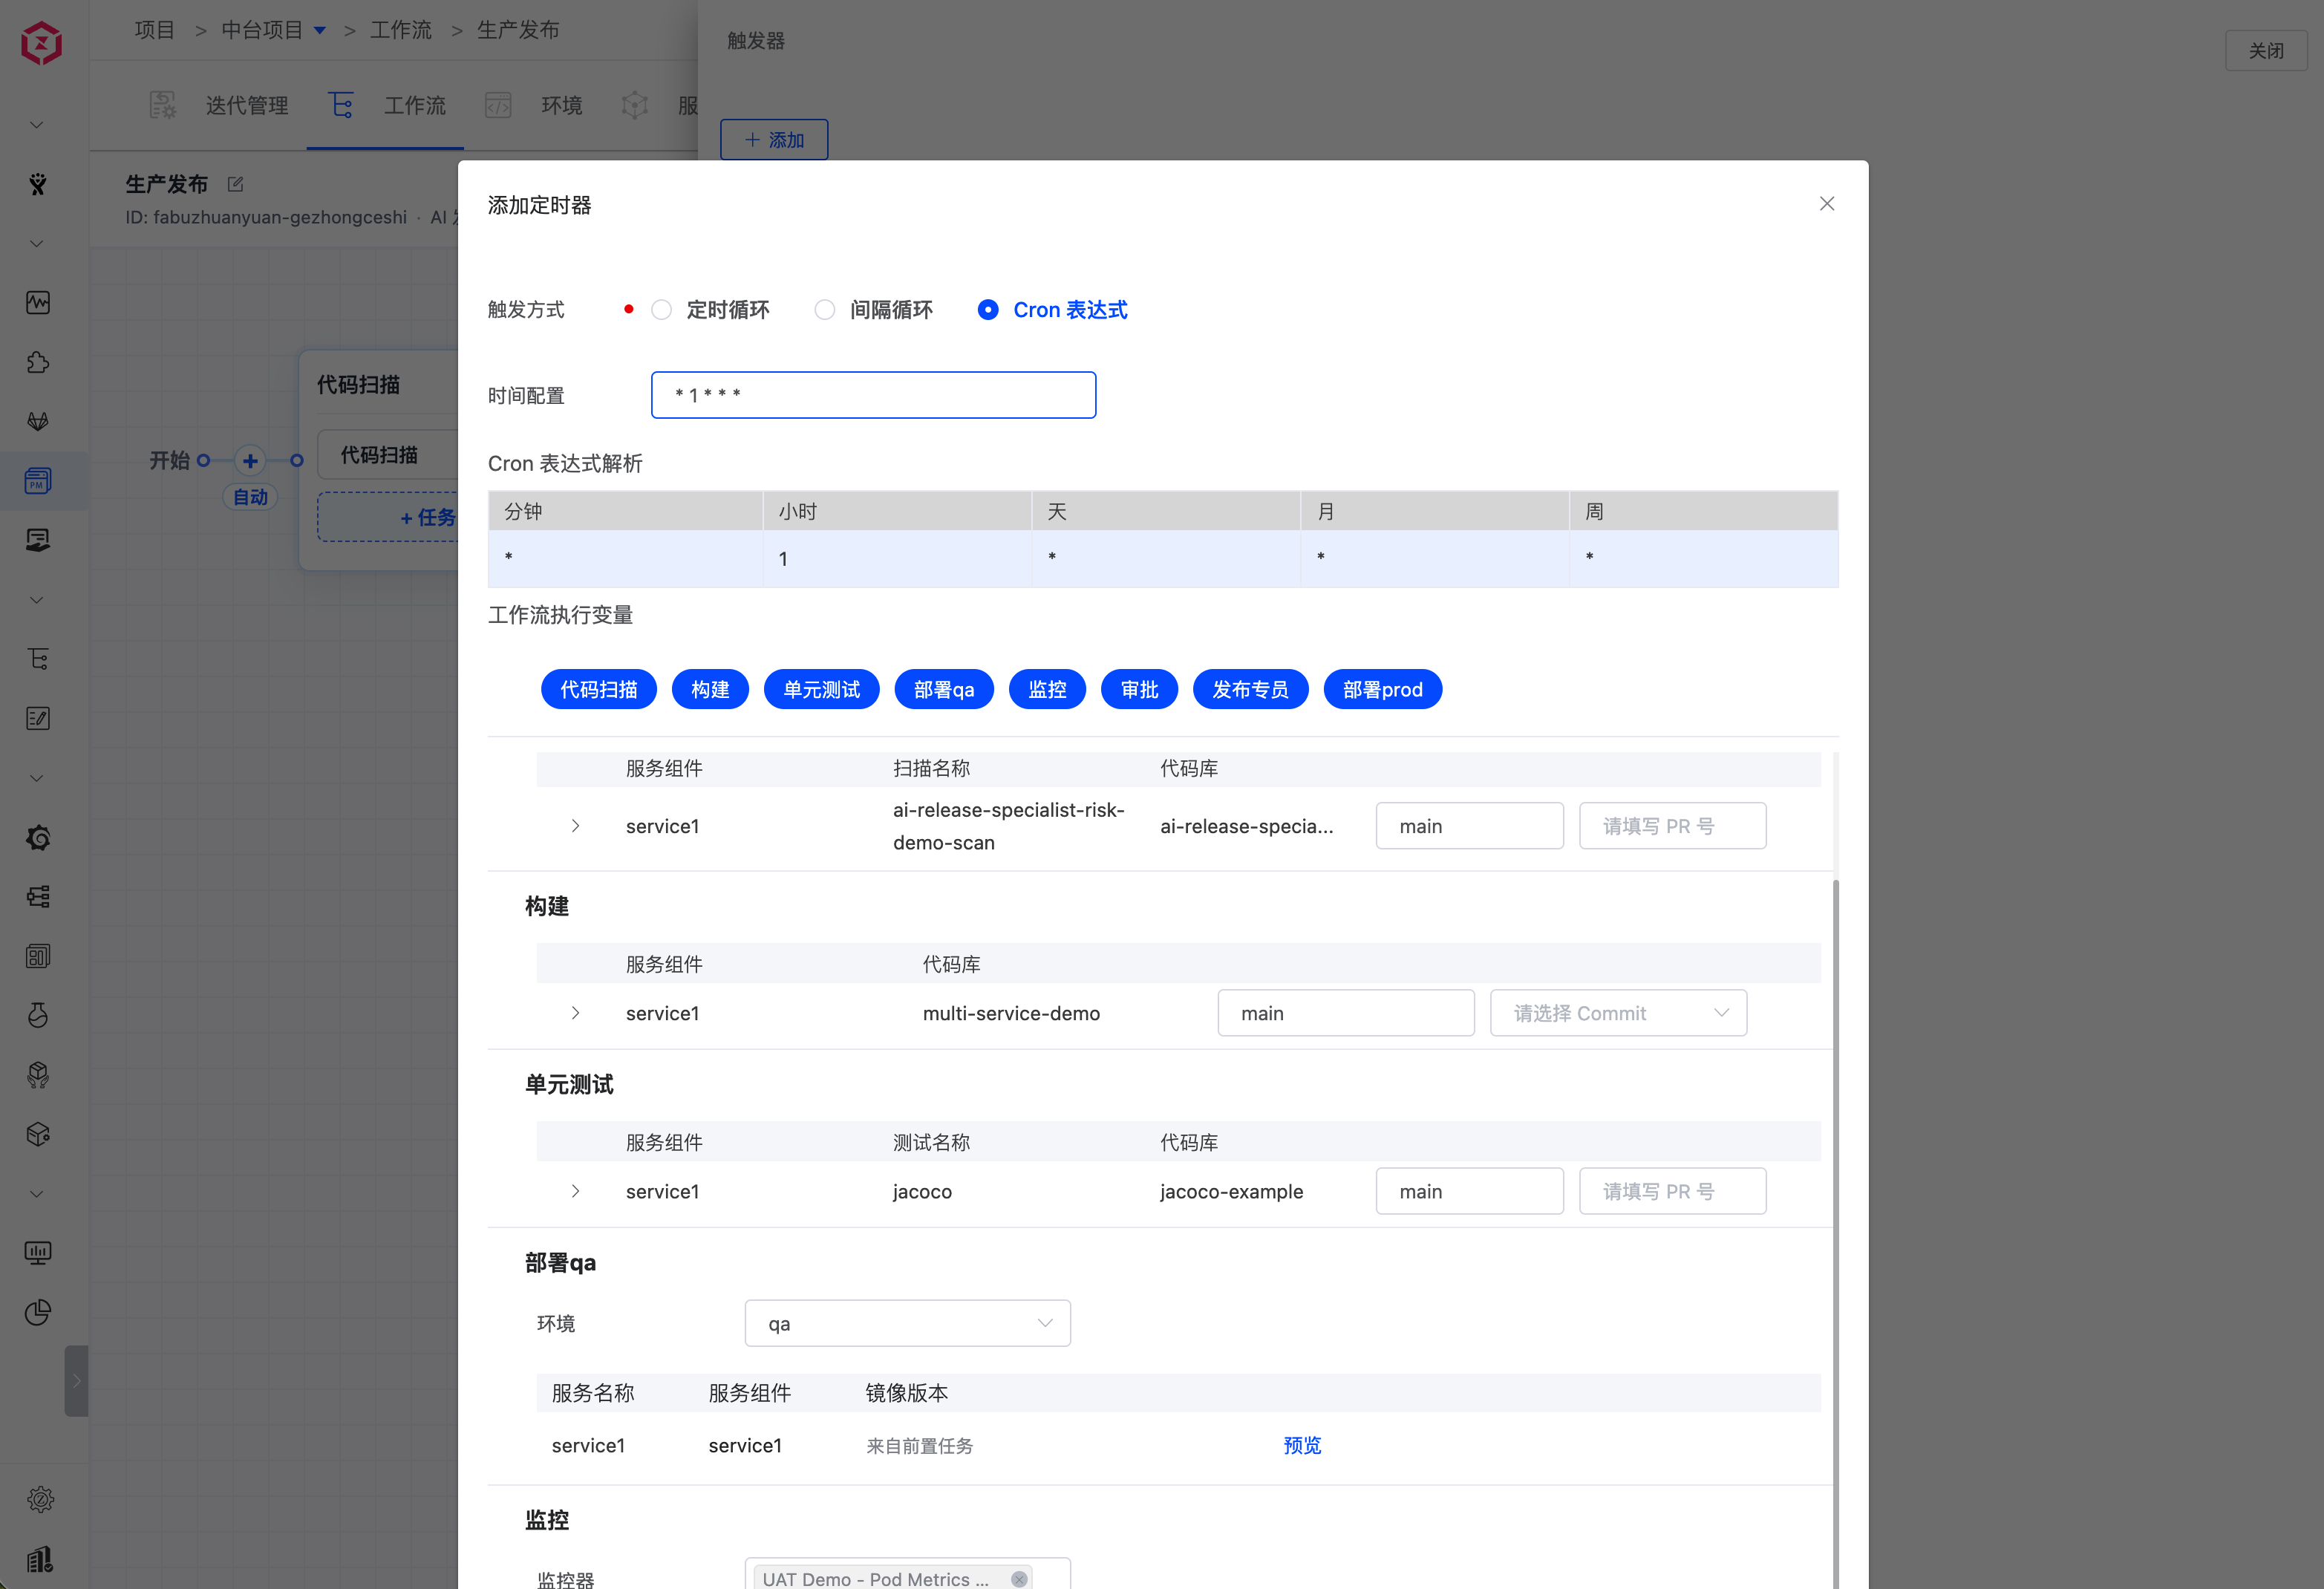
Procedure:
- Step 1: Click the add button to add a Cron expression entry and enter the Cron expression.
- Step 2: Set workflow parameters. The workflow runs with the configured parameters.
# Notification Configuration
Currently, workflow notifications can be sent to email, Feishu, WeCom, DingTalk, and Webhook. For detailed configuration parameters, see IM Status Notifications.
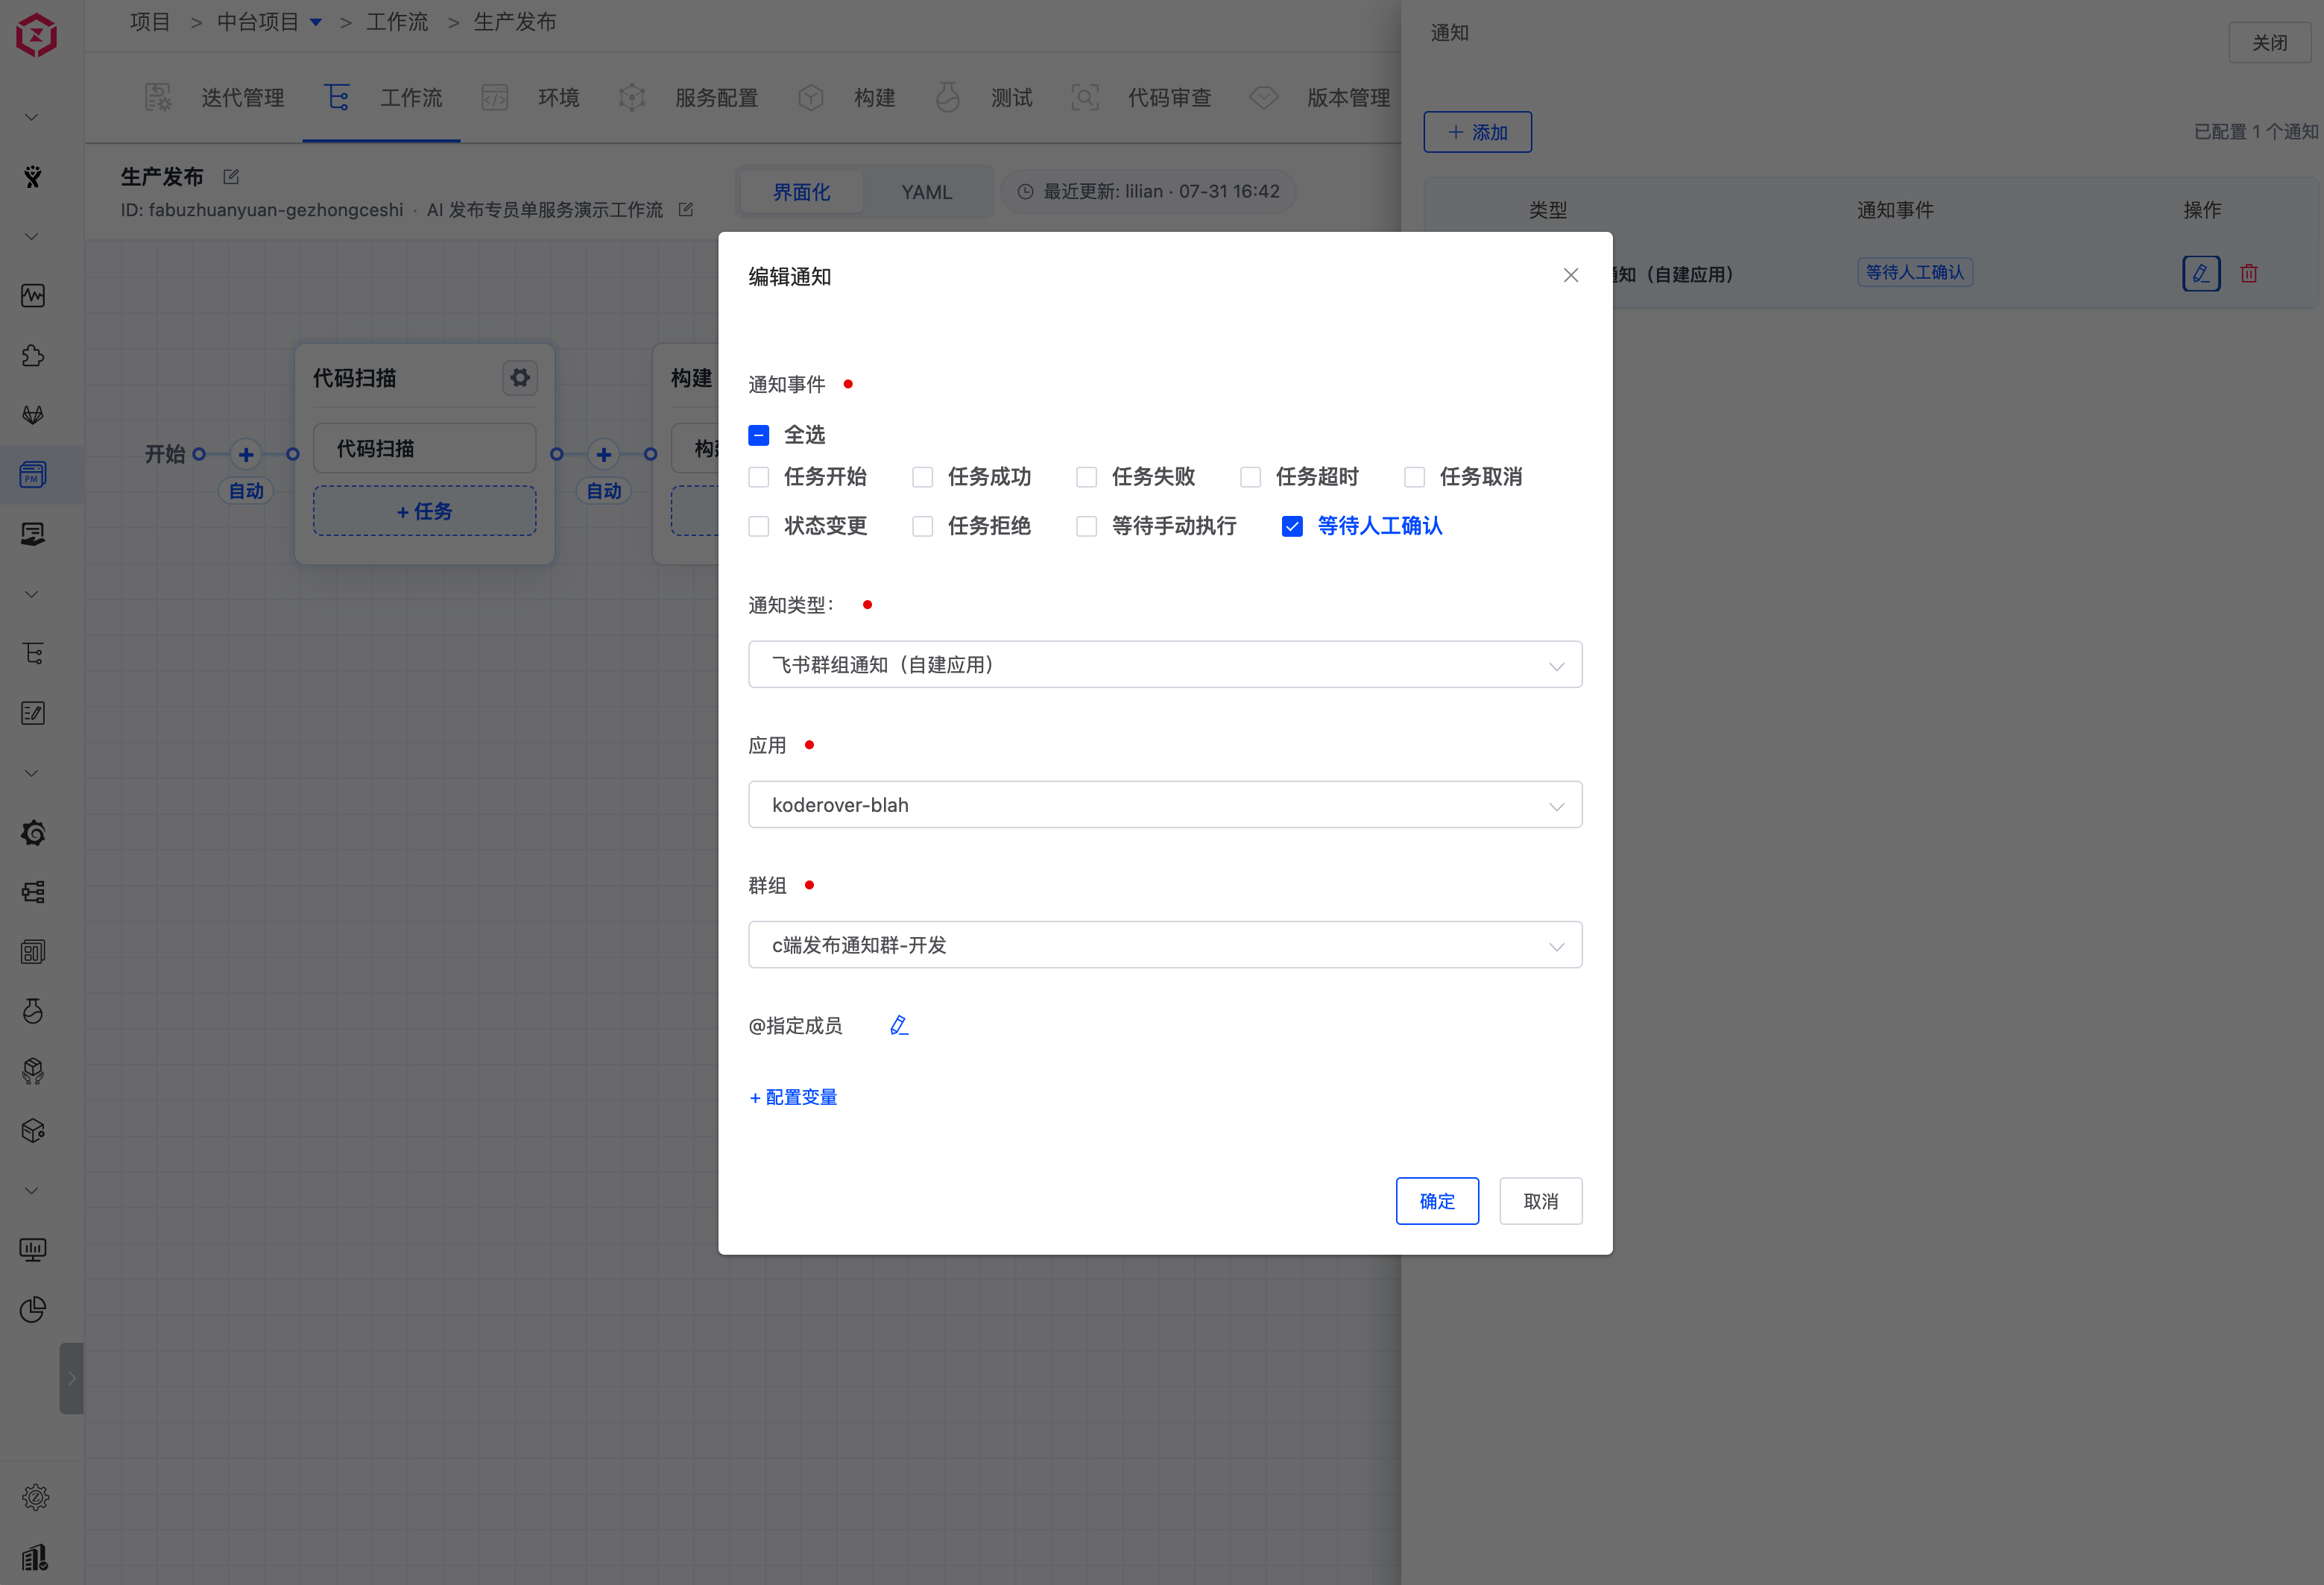
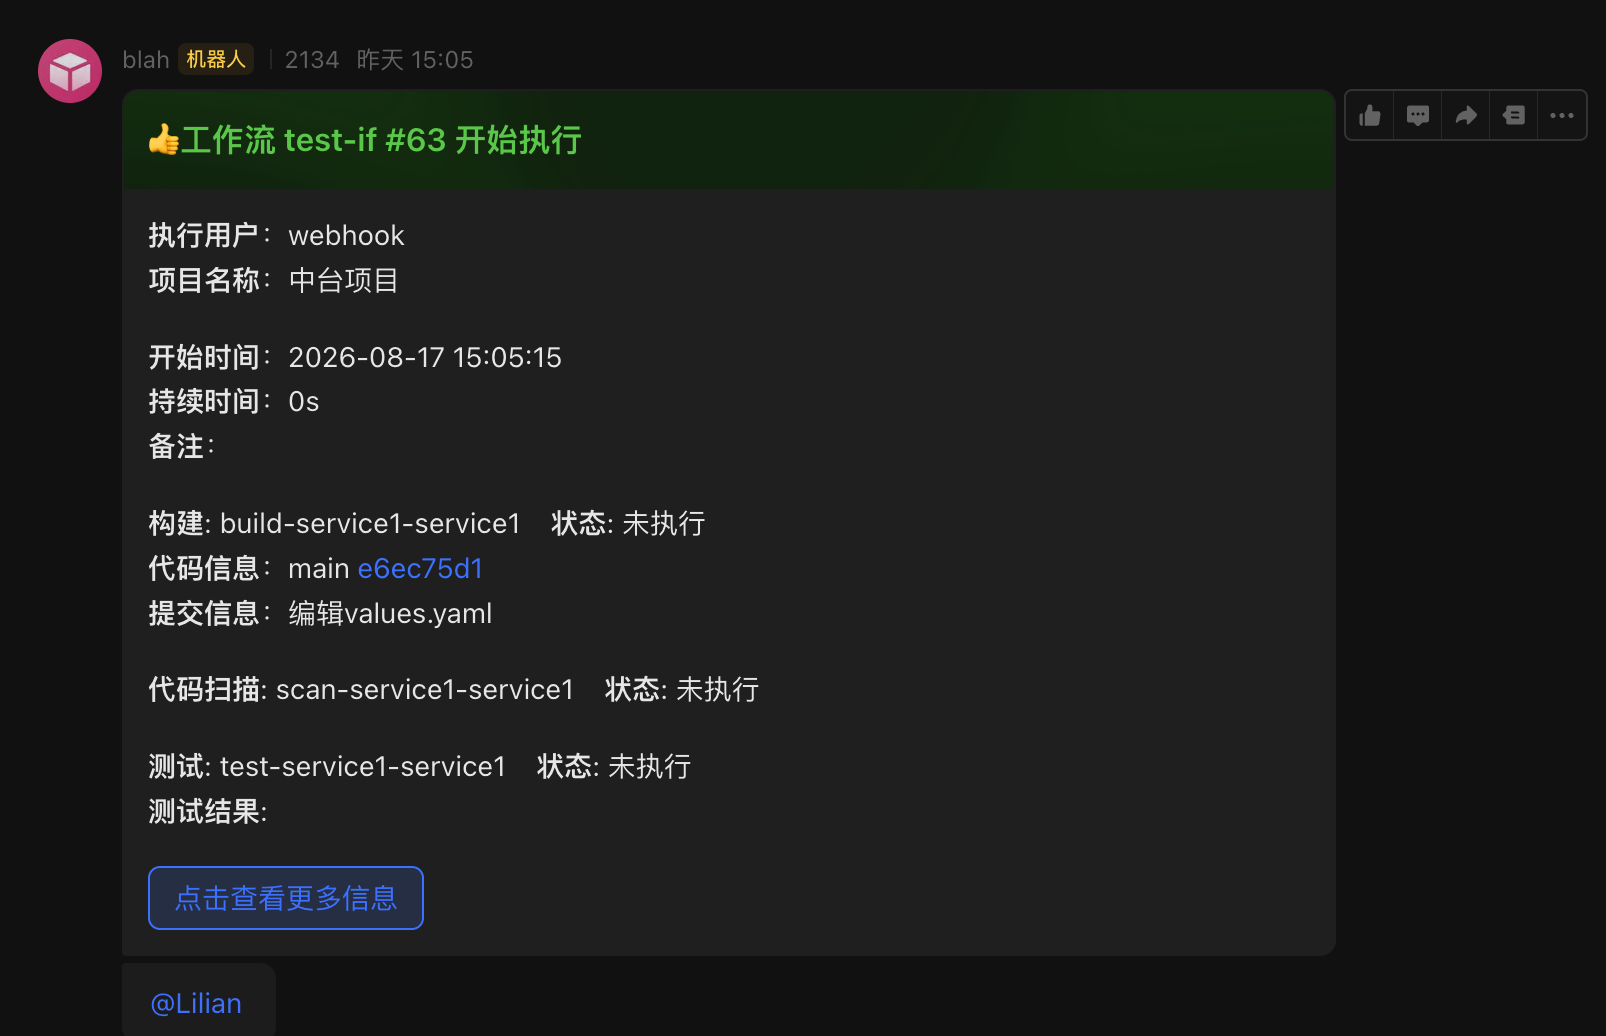
Notification messages include the execution status of all jobs in the workflow. For build, deploy, and test jobs, the name rules in notifications are as follows:
- Build job: service name-service module name-build job name
- Deploy job: service name-deploy job name
- Test job: test name-test job name-random string
Example Feishu notification:
# Execution Concurrency
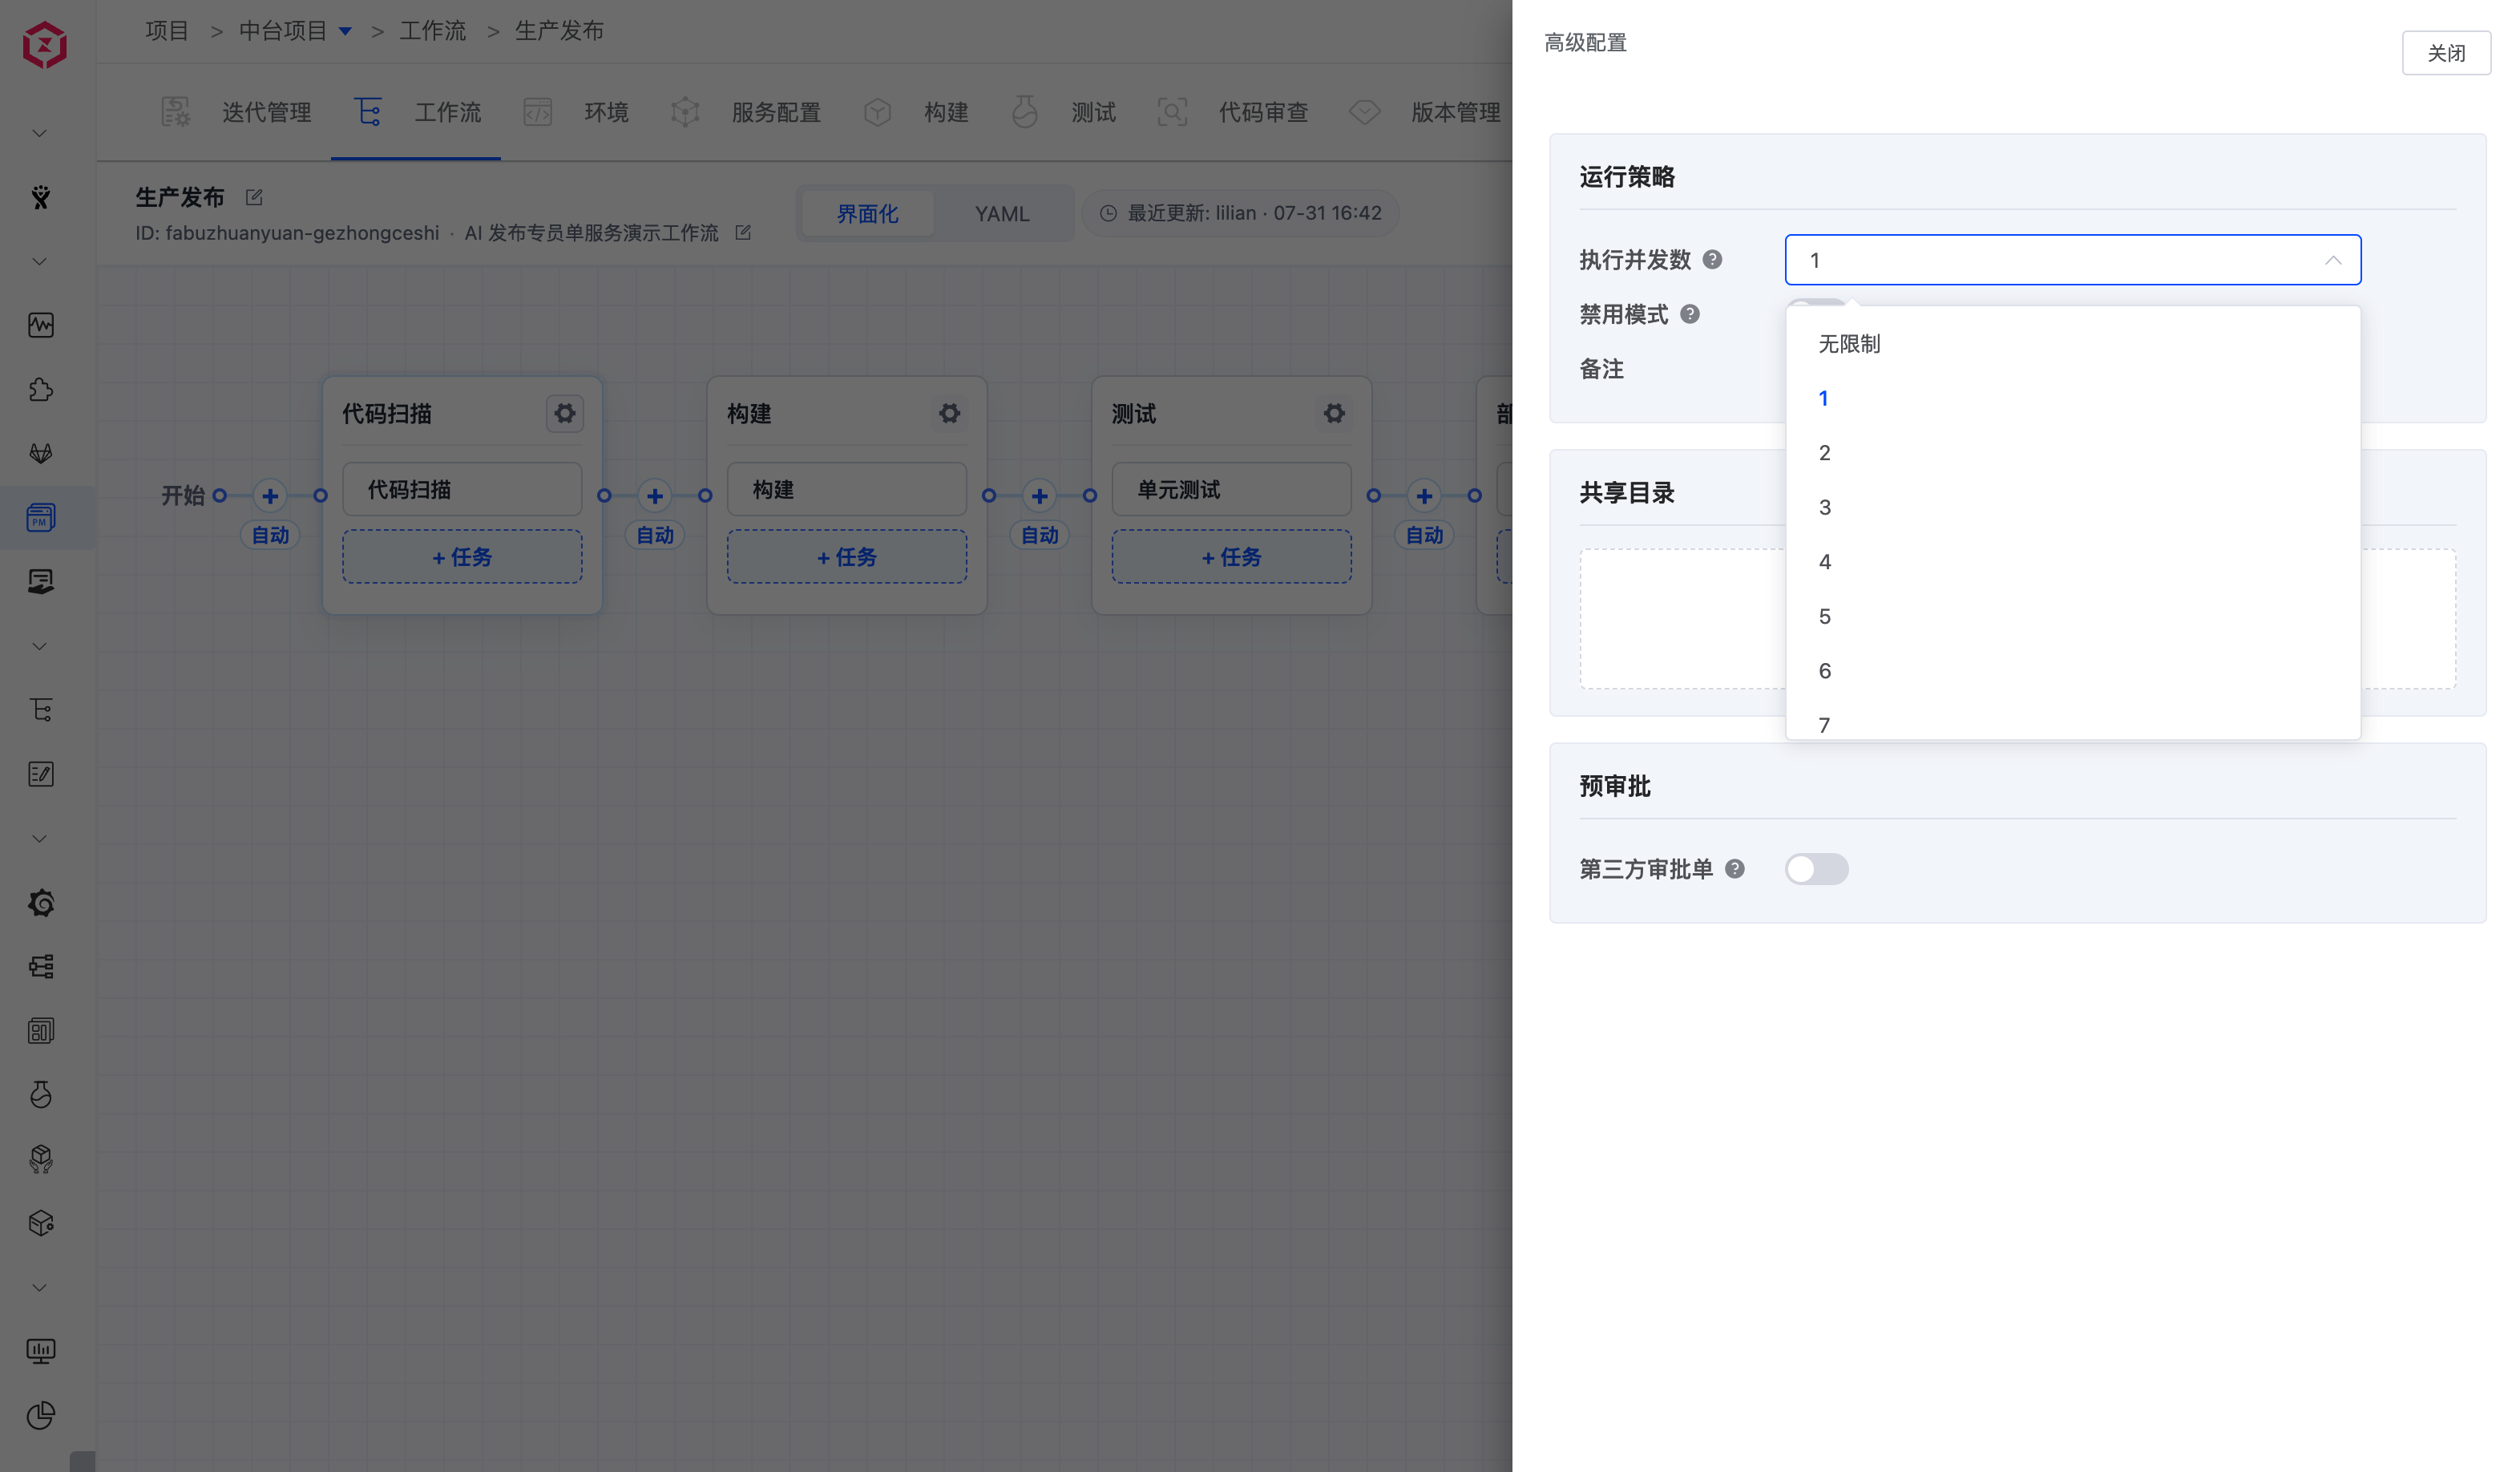
Set the concurrency in Advanced Configuration > Run Policy. Multiple workflow tasks generated by multiple workflow triggers run concurrently, improving workflow execution efficiency.
# Disable
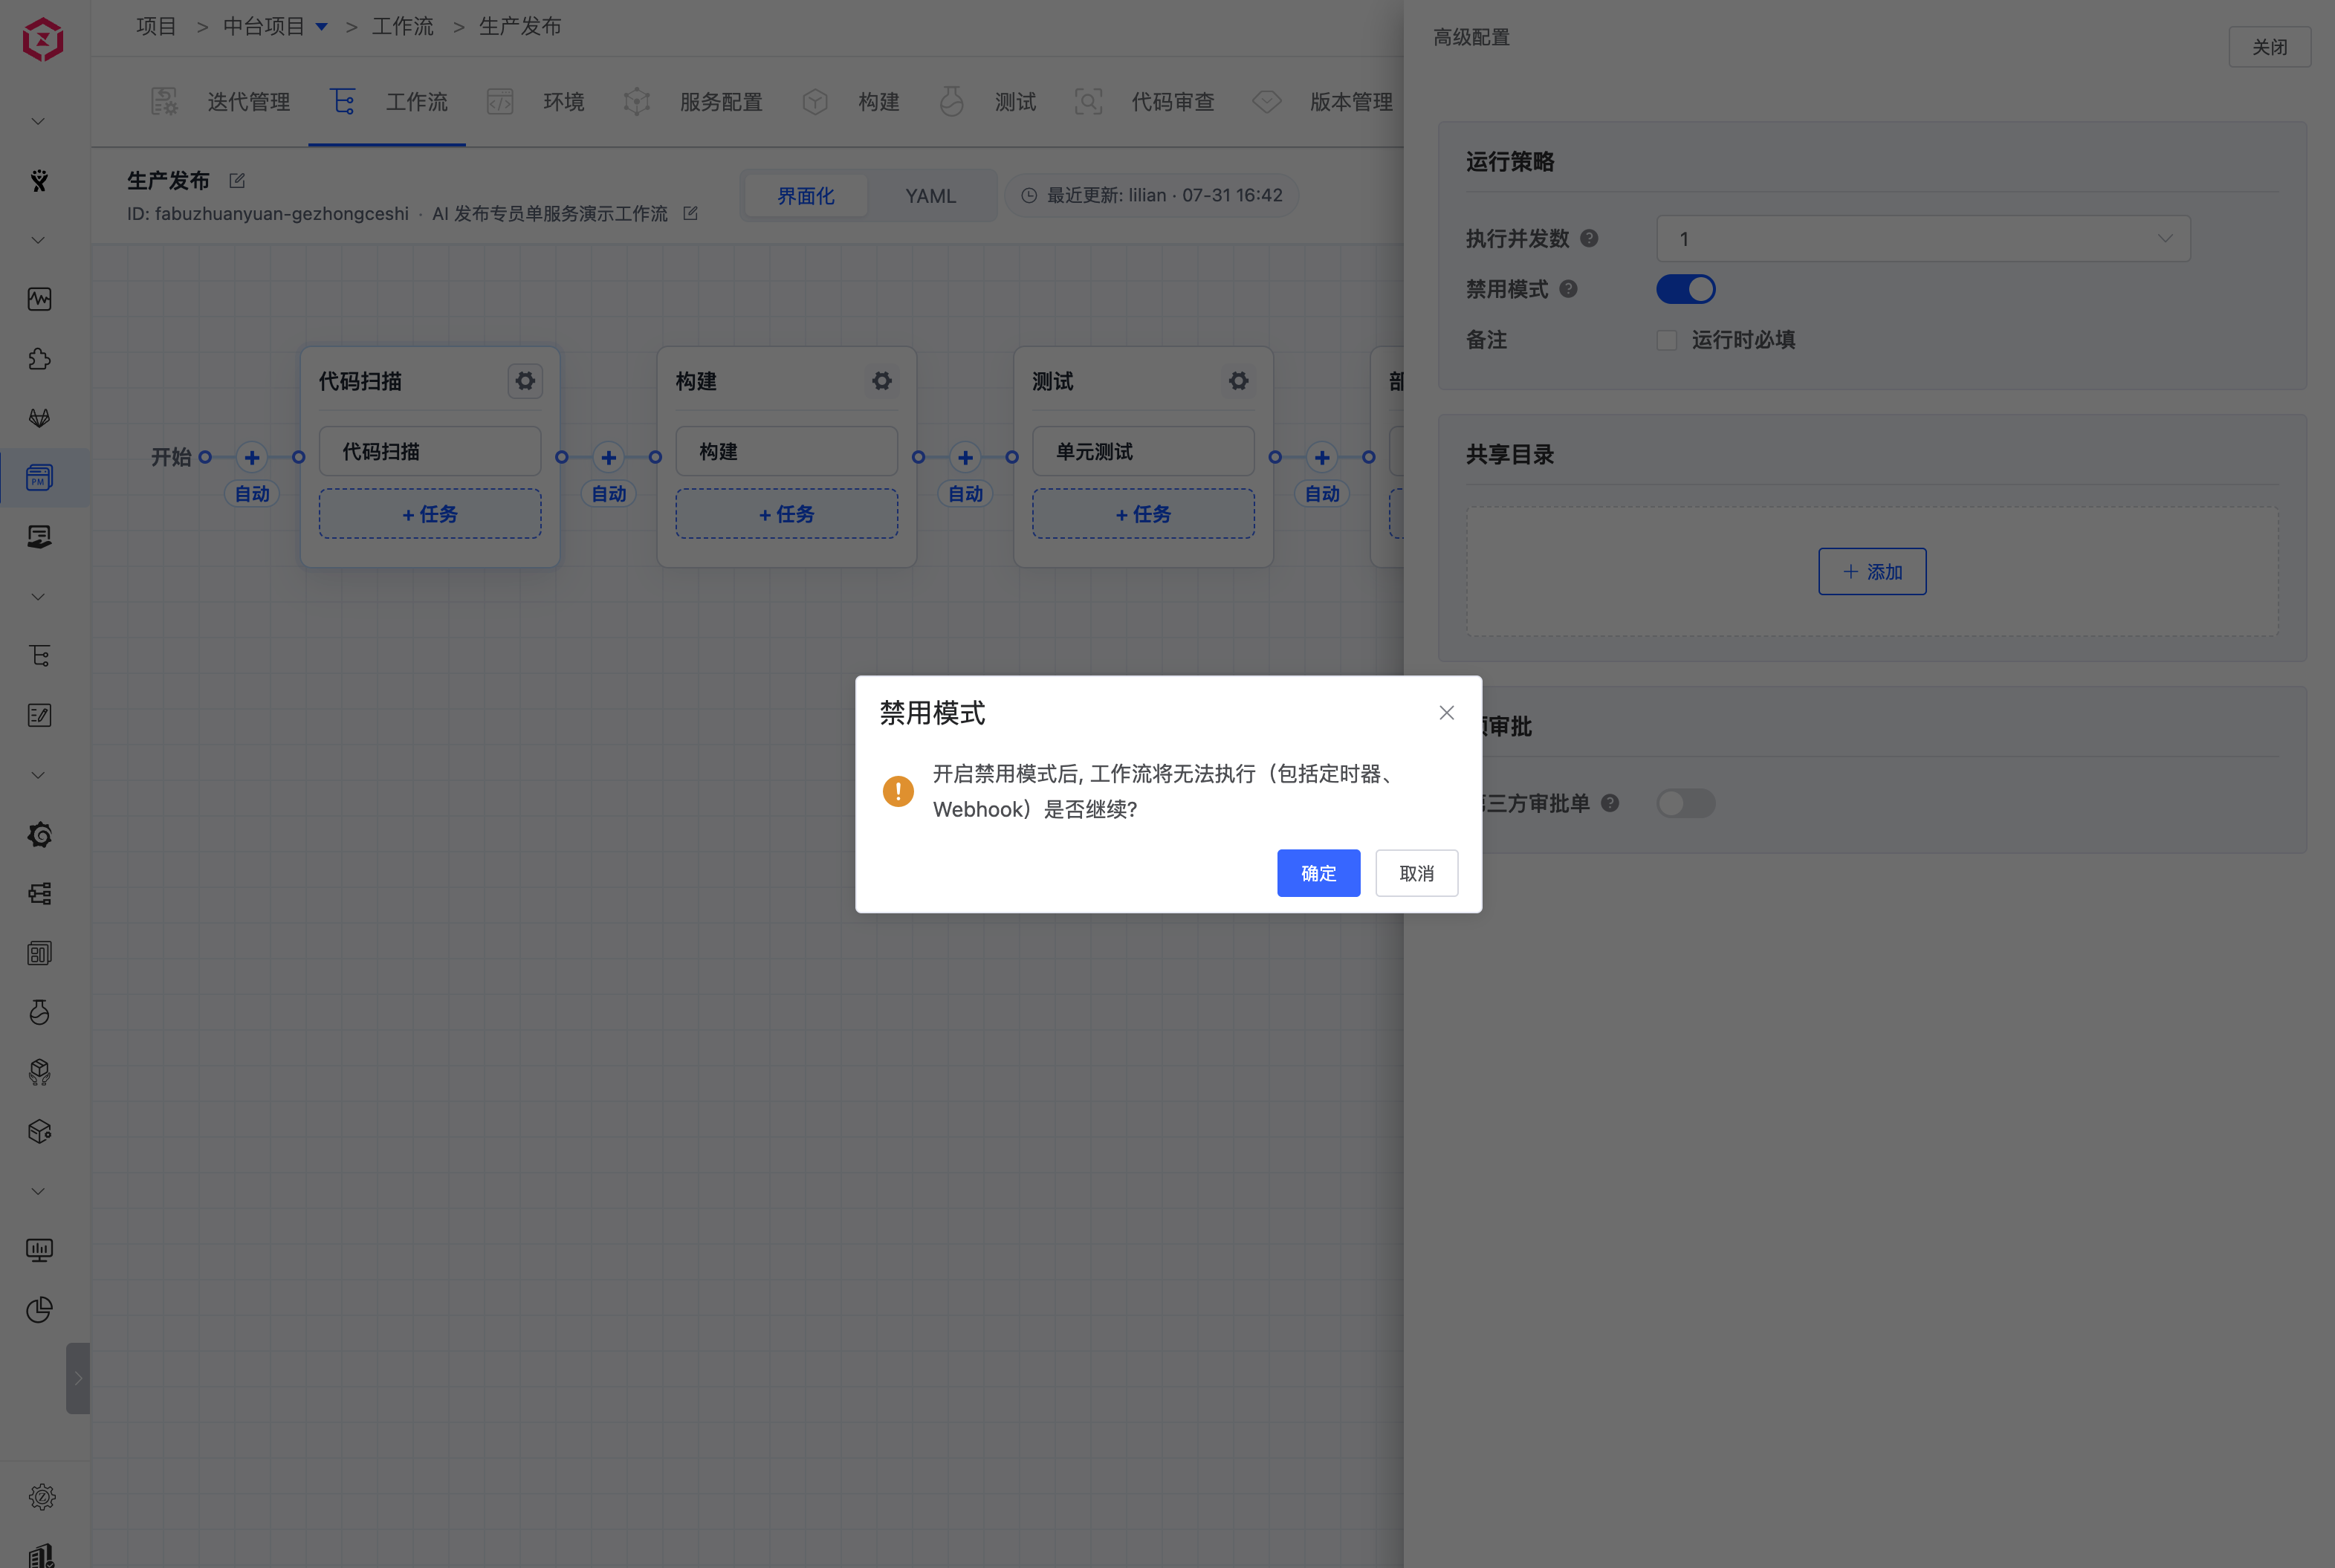
After disable mode is enabled, the workflow cannot be executed, either manually or through triggers.
# Remarks
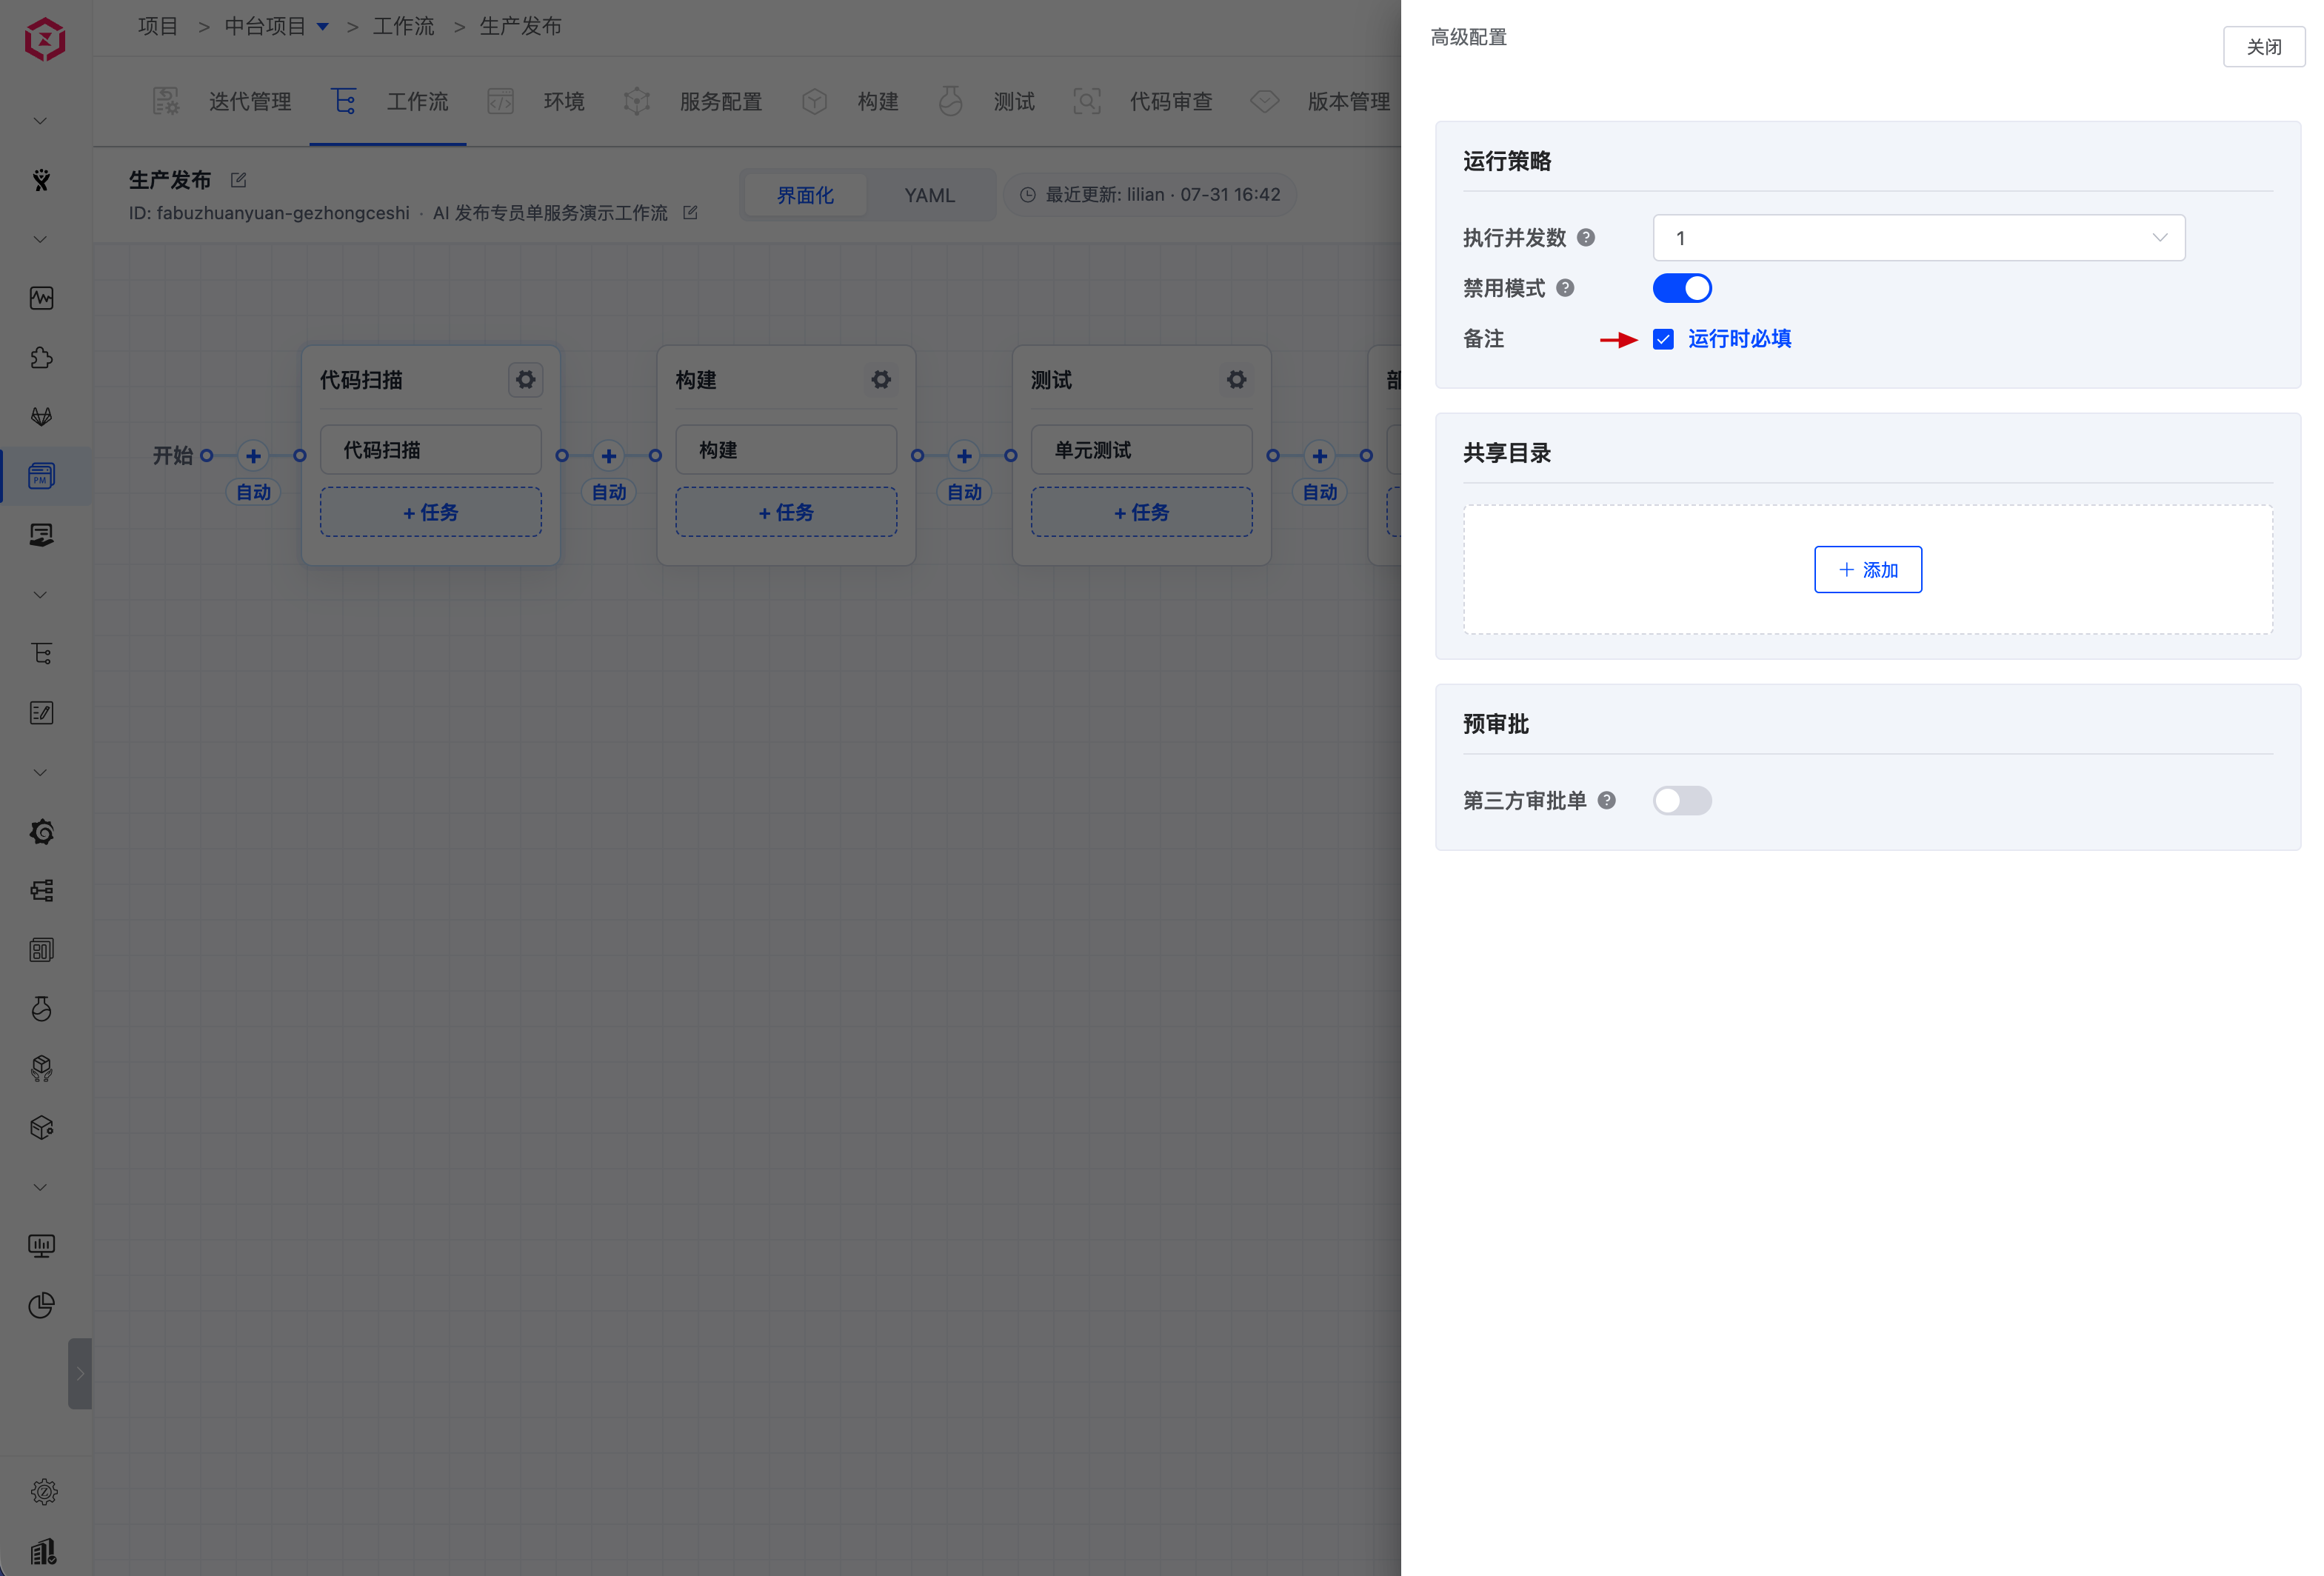
You can enter remarks when running a workflow, making it easier to view workflow execution notes later. Required-at-runtime is supported. After it is enabled, remarks must be entered when running the workflow.
# Debugging
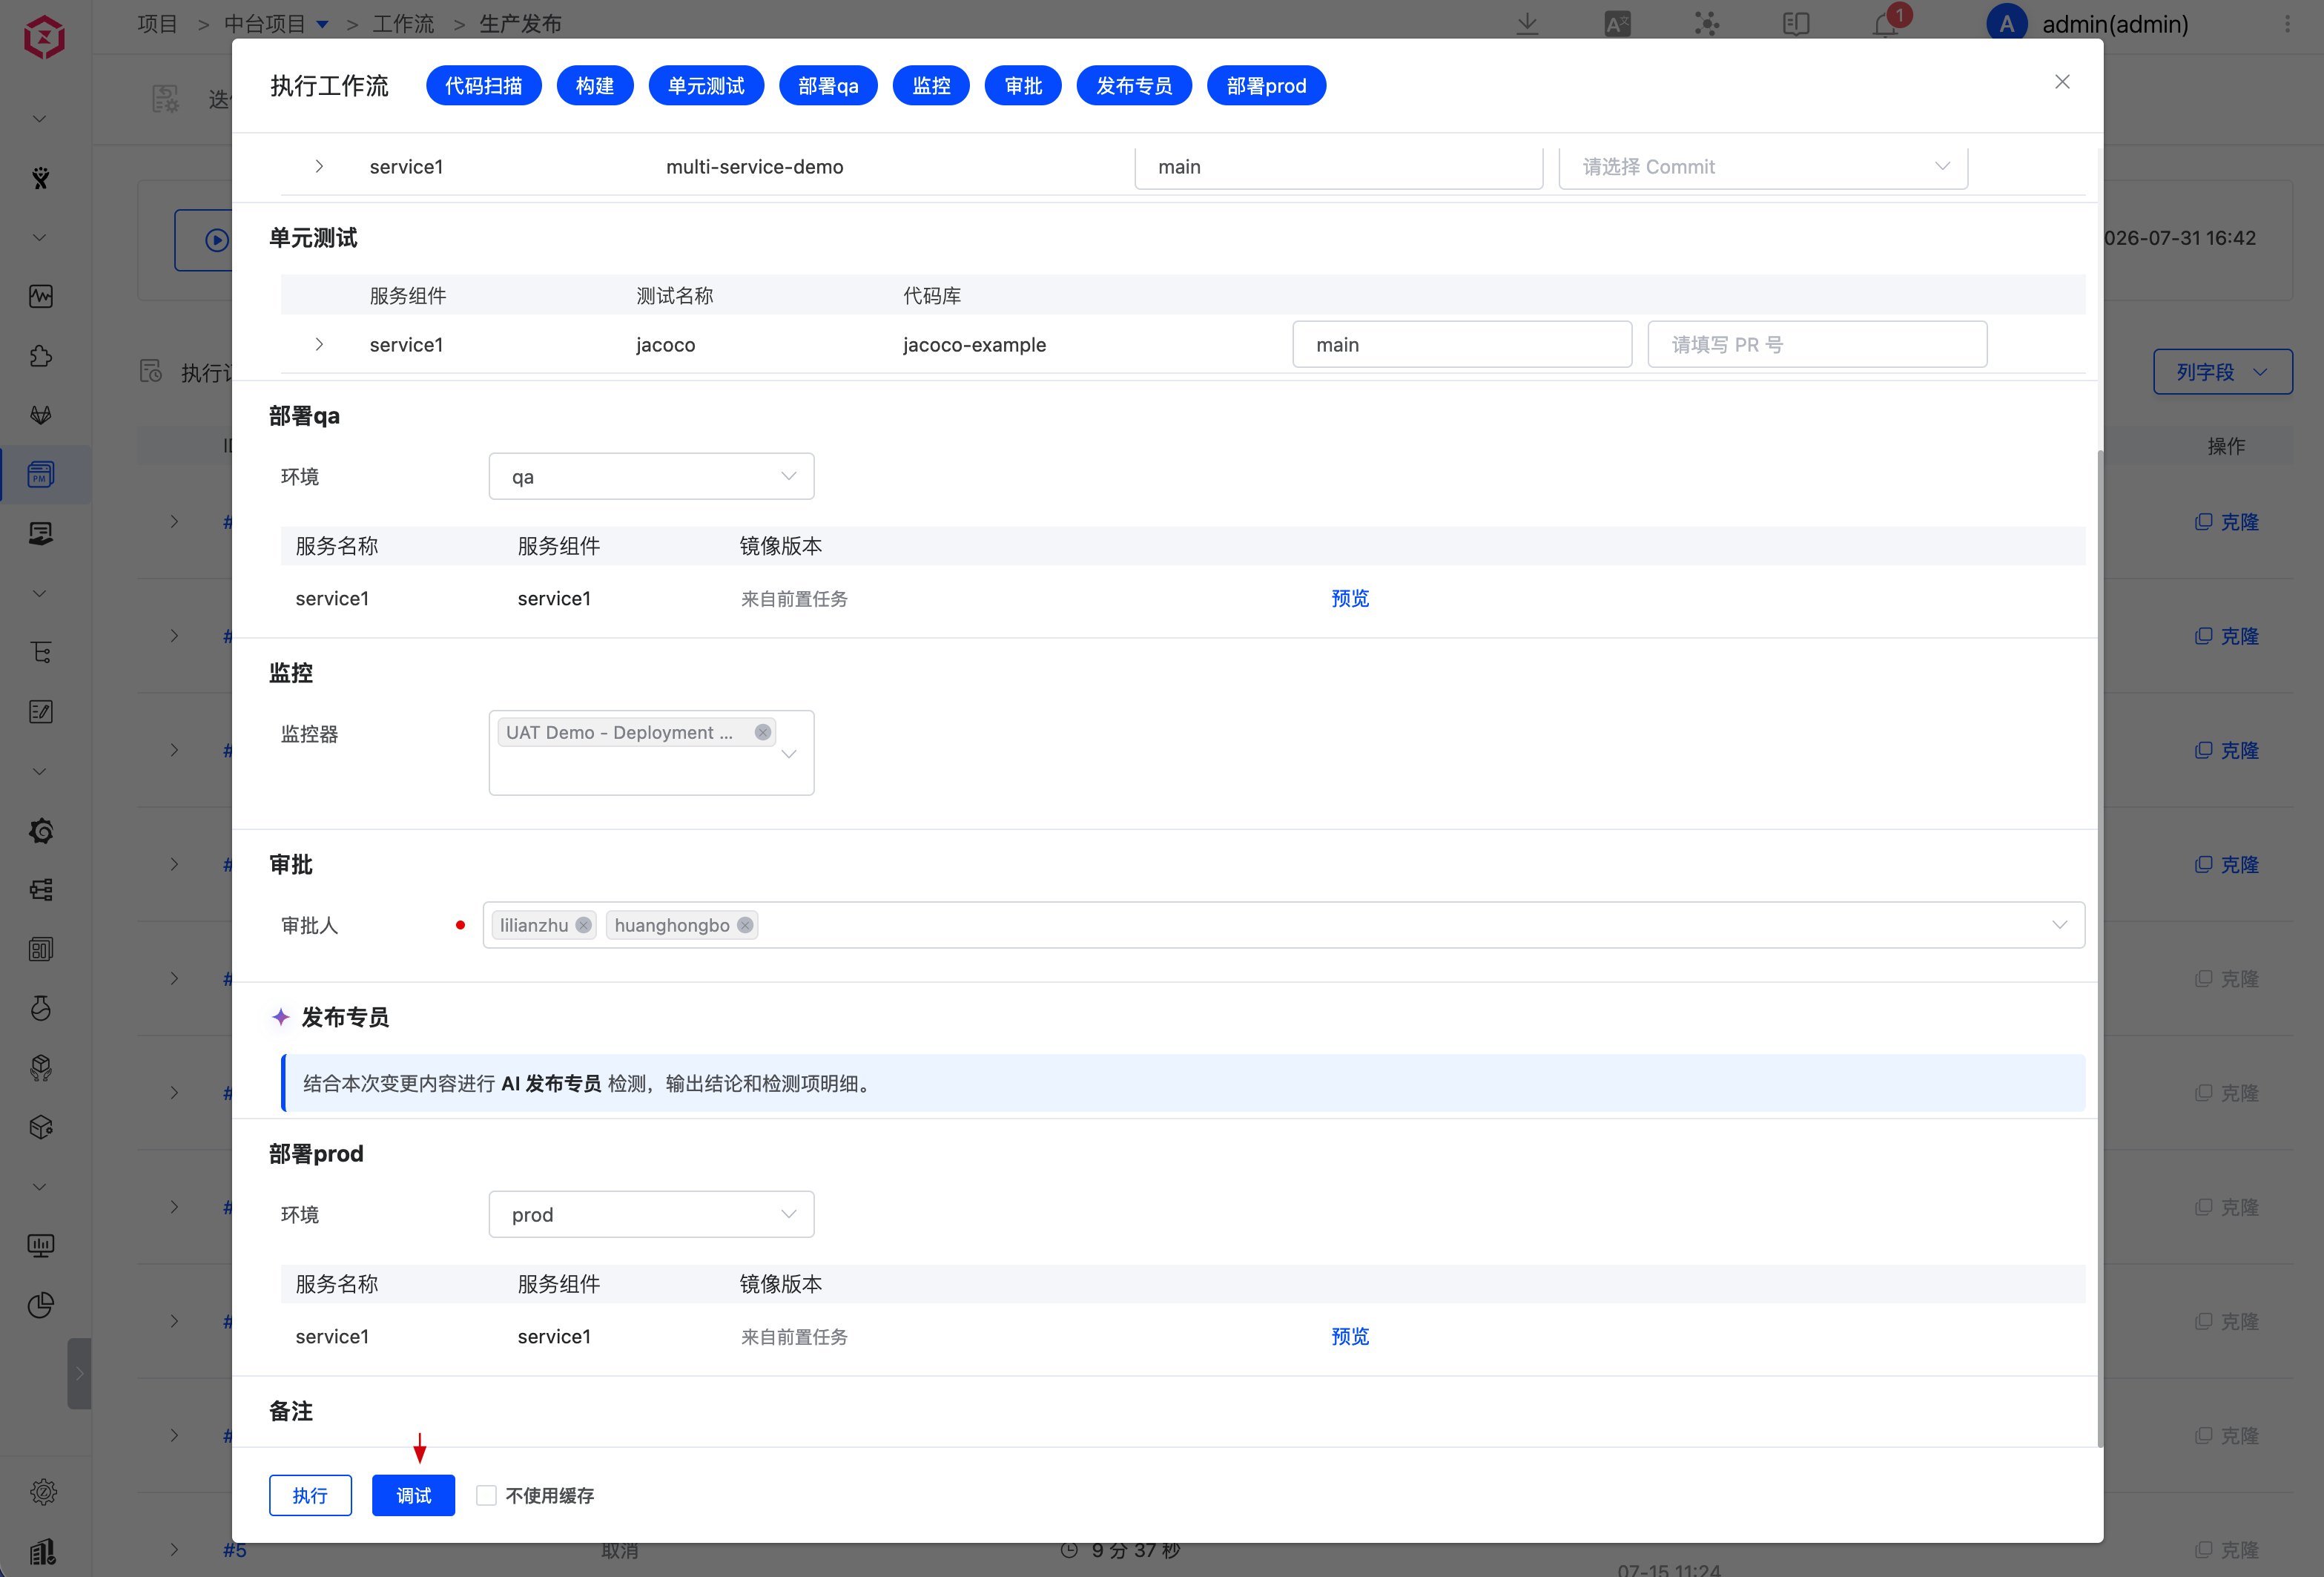
Debugging is supported for build jobs, test jobs, and general script execution.
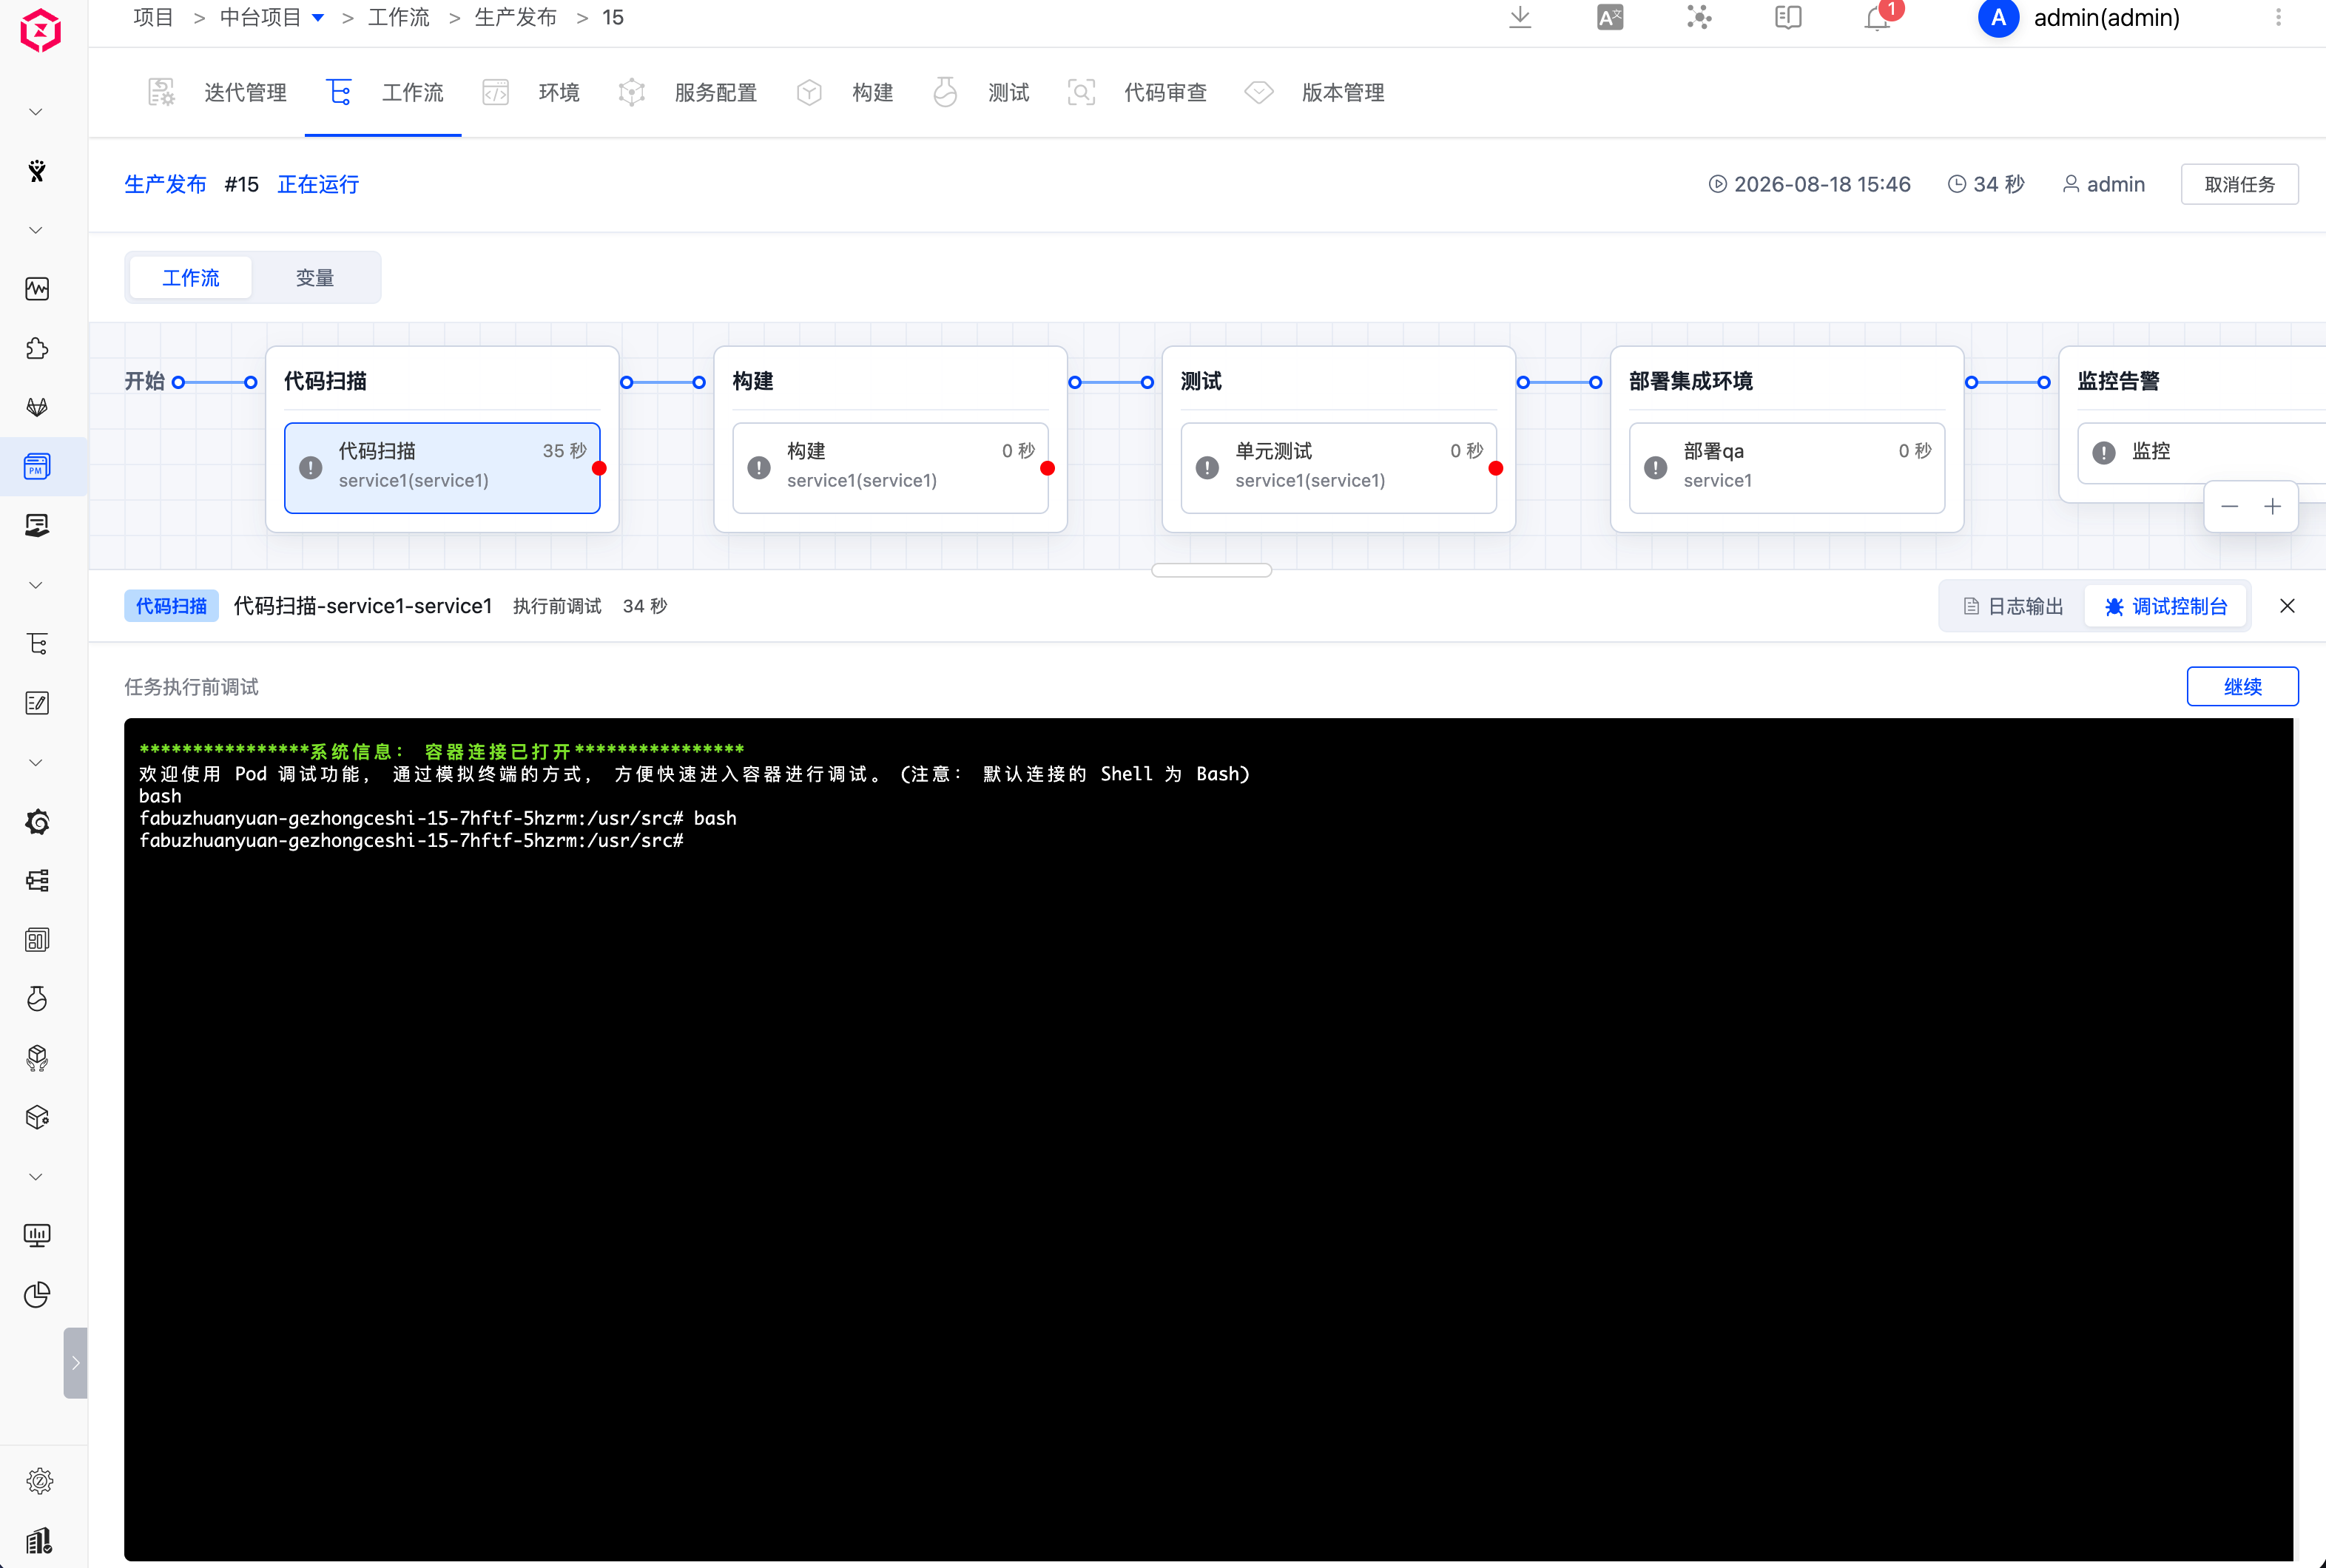
Click Debug to start the workflow in debug mode. You can add breakpoints before the Shell scripts in build, test, and general script execution jobs are executed, which helps debug workflow configuration.
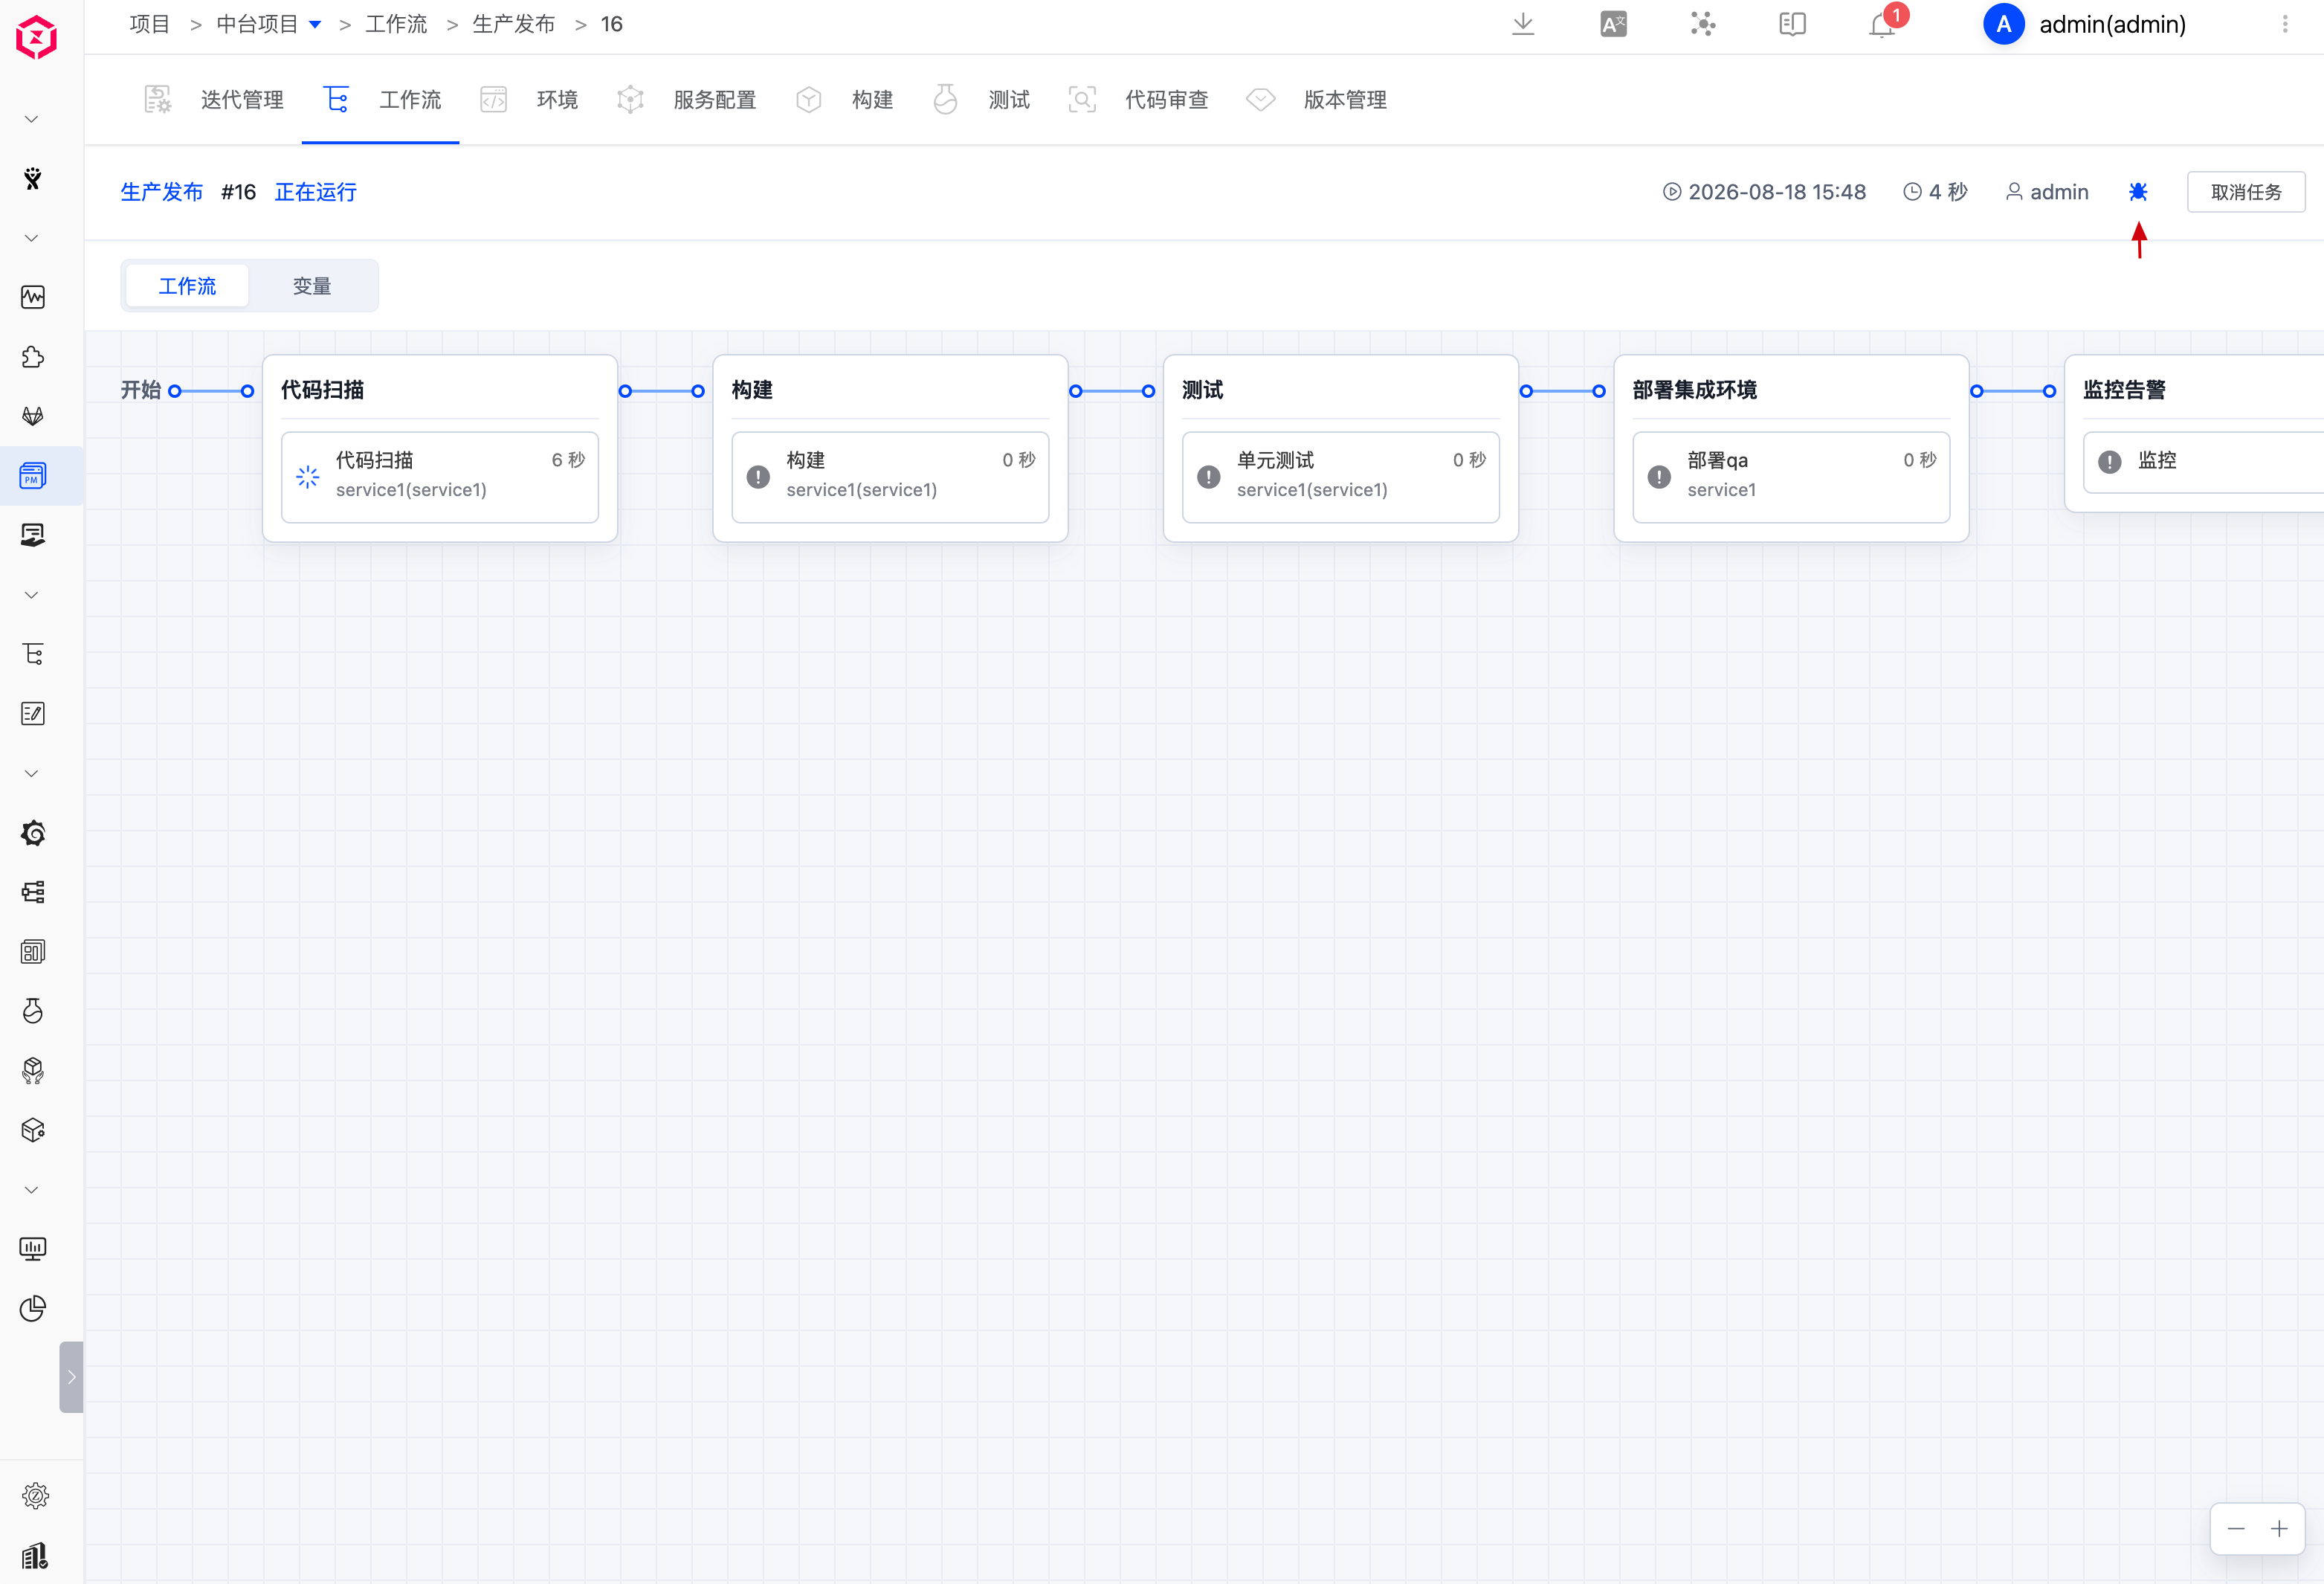
You can also add breakpoint debugging to a specified job after running the workflow. Click the debug icon in the upper-right corner and configure the breakpoint location.
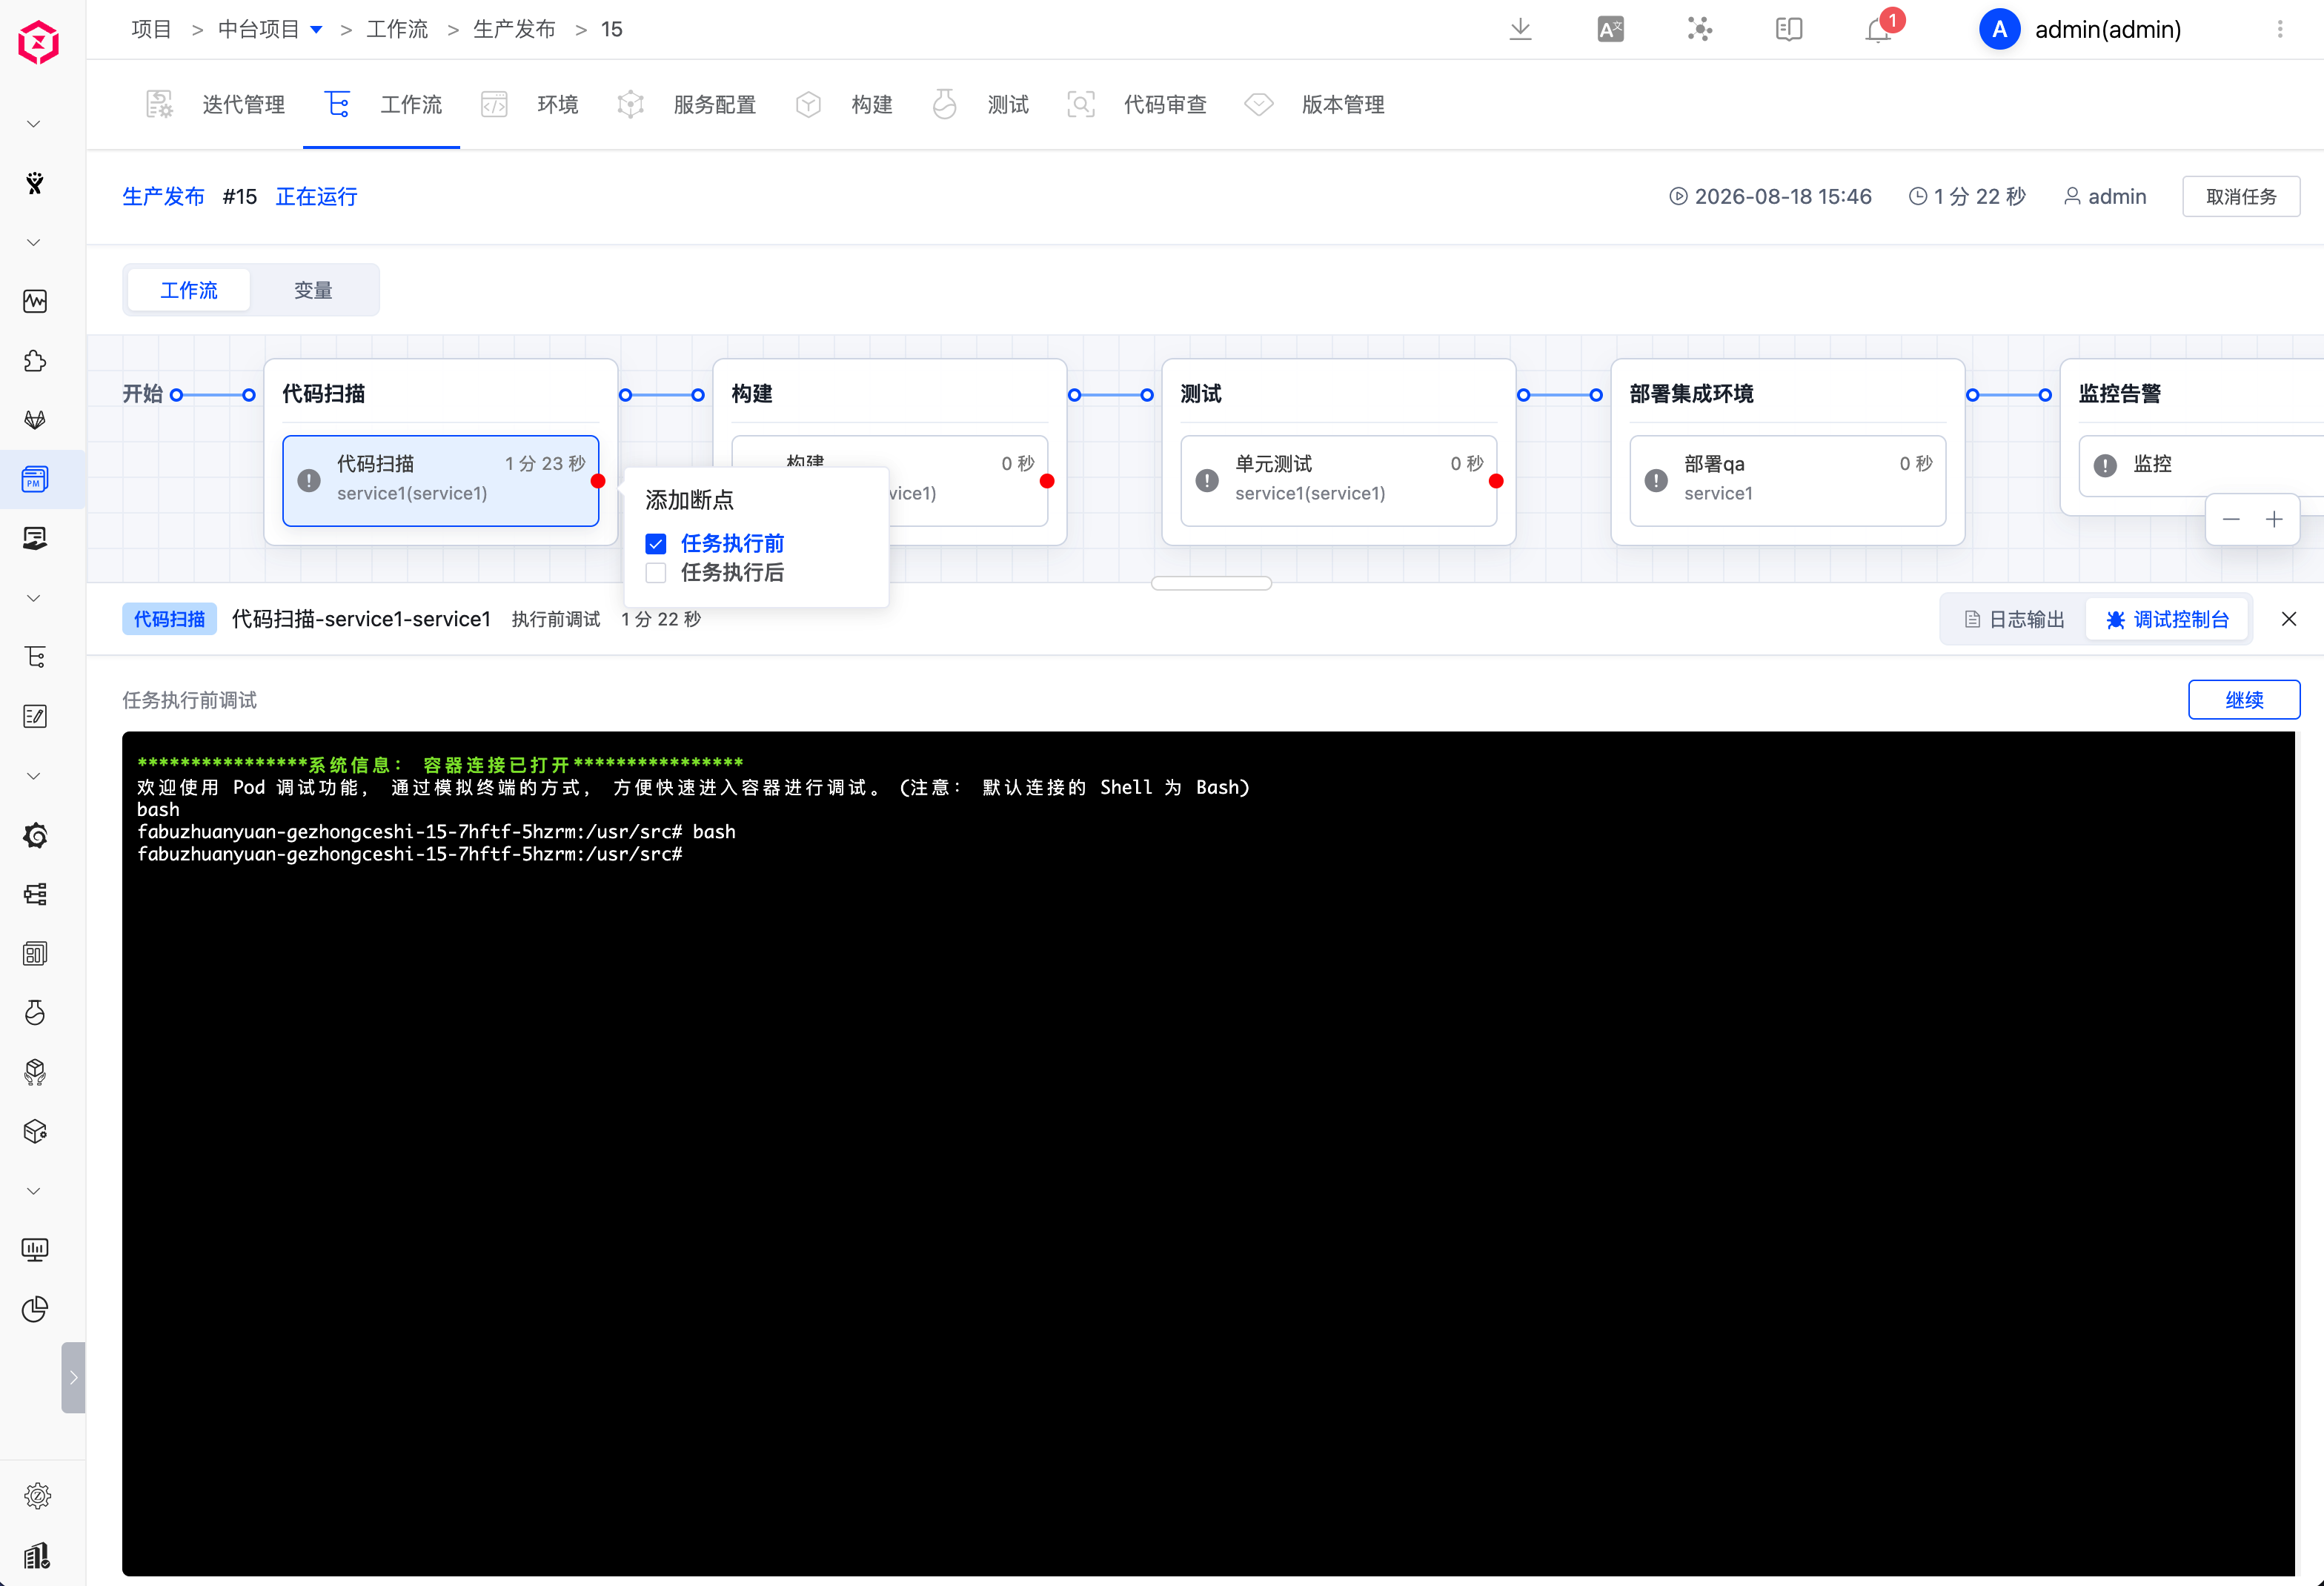
Click Debug Console to log in to the container of the current job. After debugging is complete, click Continue for the workflow to continue.
# Customize Execution Record Columns
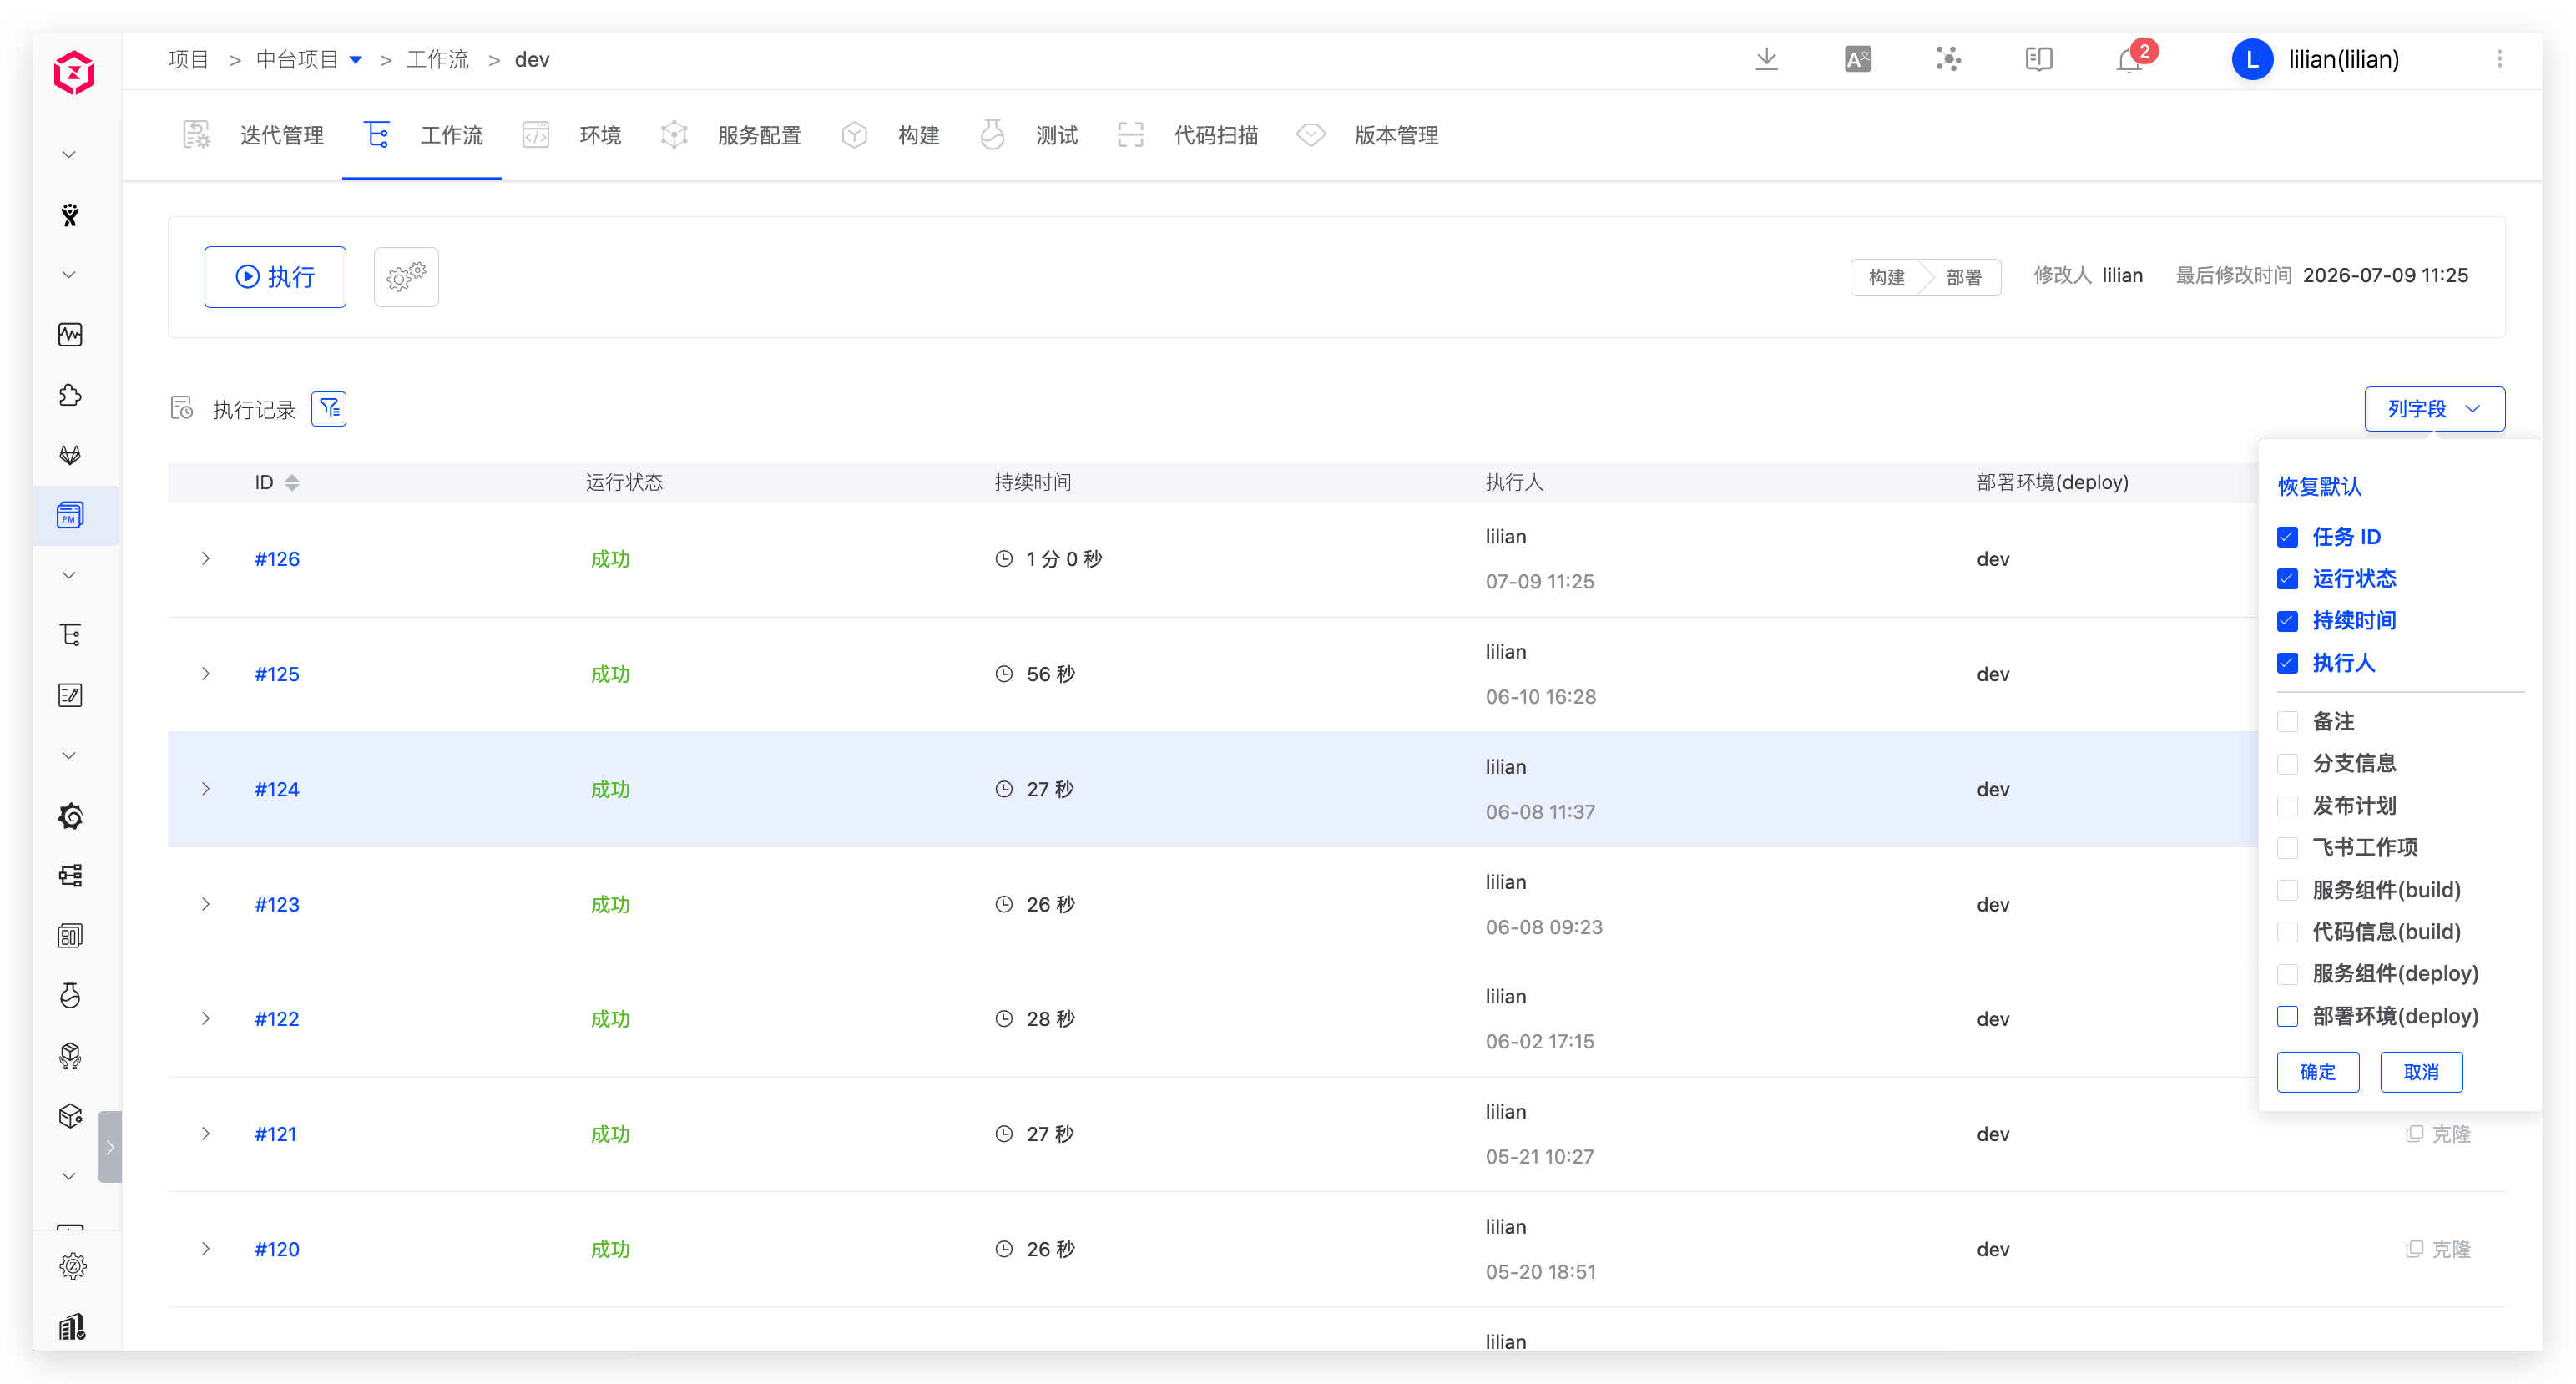
You can customize columns in execution records and add related information from build, deploy, and test jobs to the list. The custom column formats are as follows:
- Service module (build job name)
- Code information (build job name)
- Service module (deploy job name)
- Environment (deploy job name)
- Test result (test job name)
- Remarks
- Branch information
- Release plan
- Feishu Project
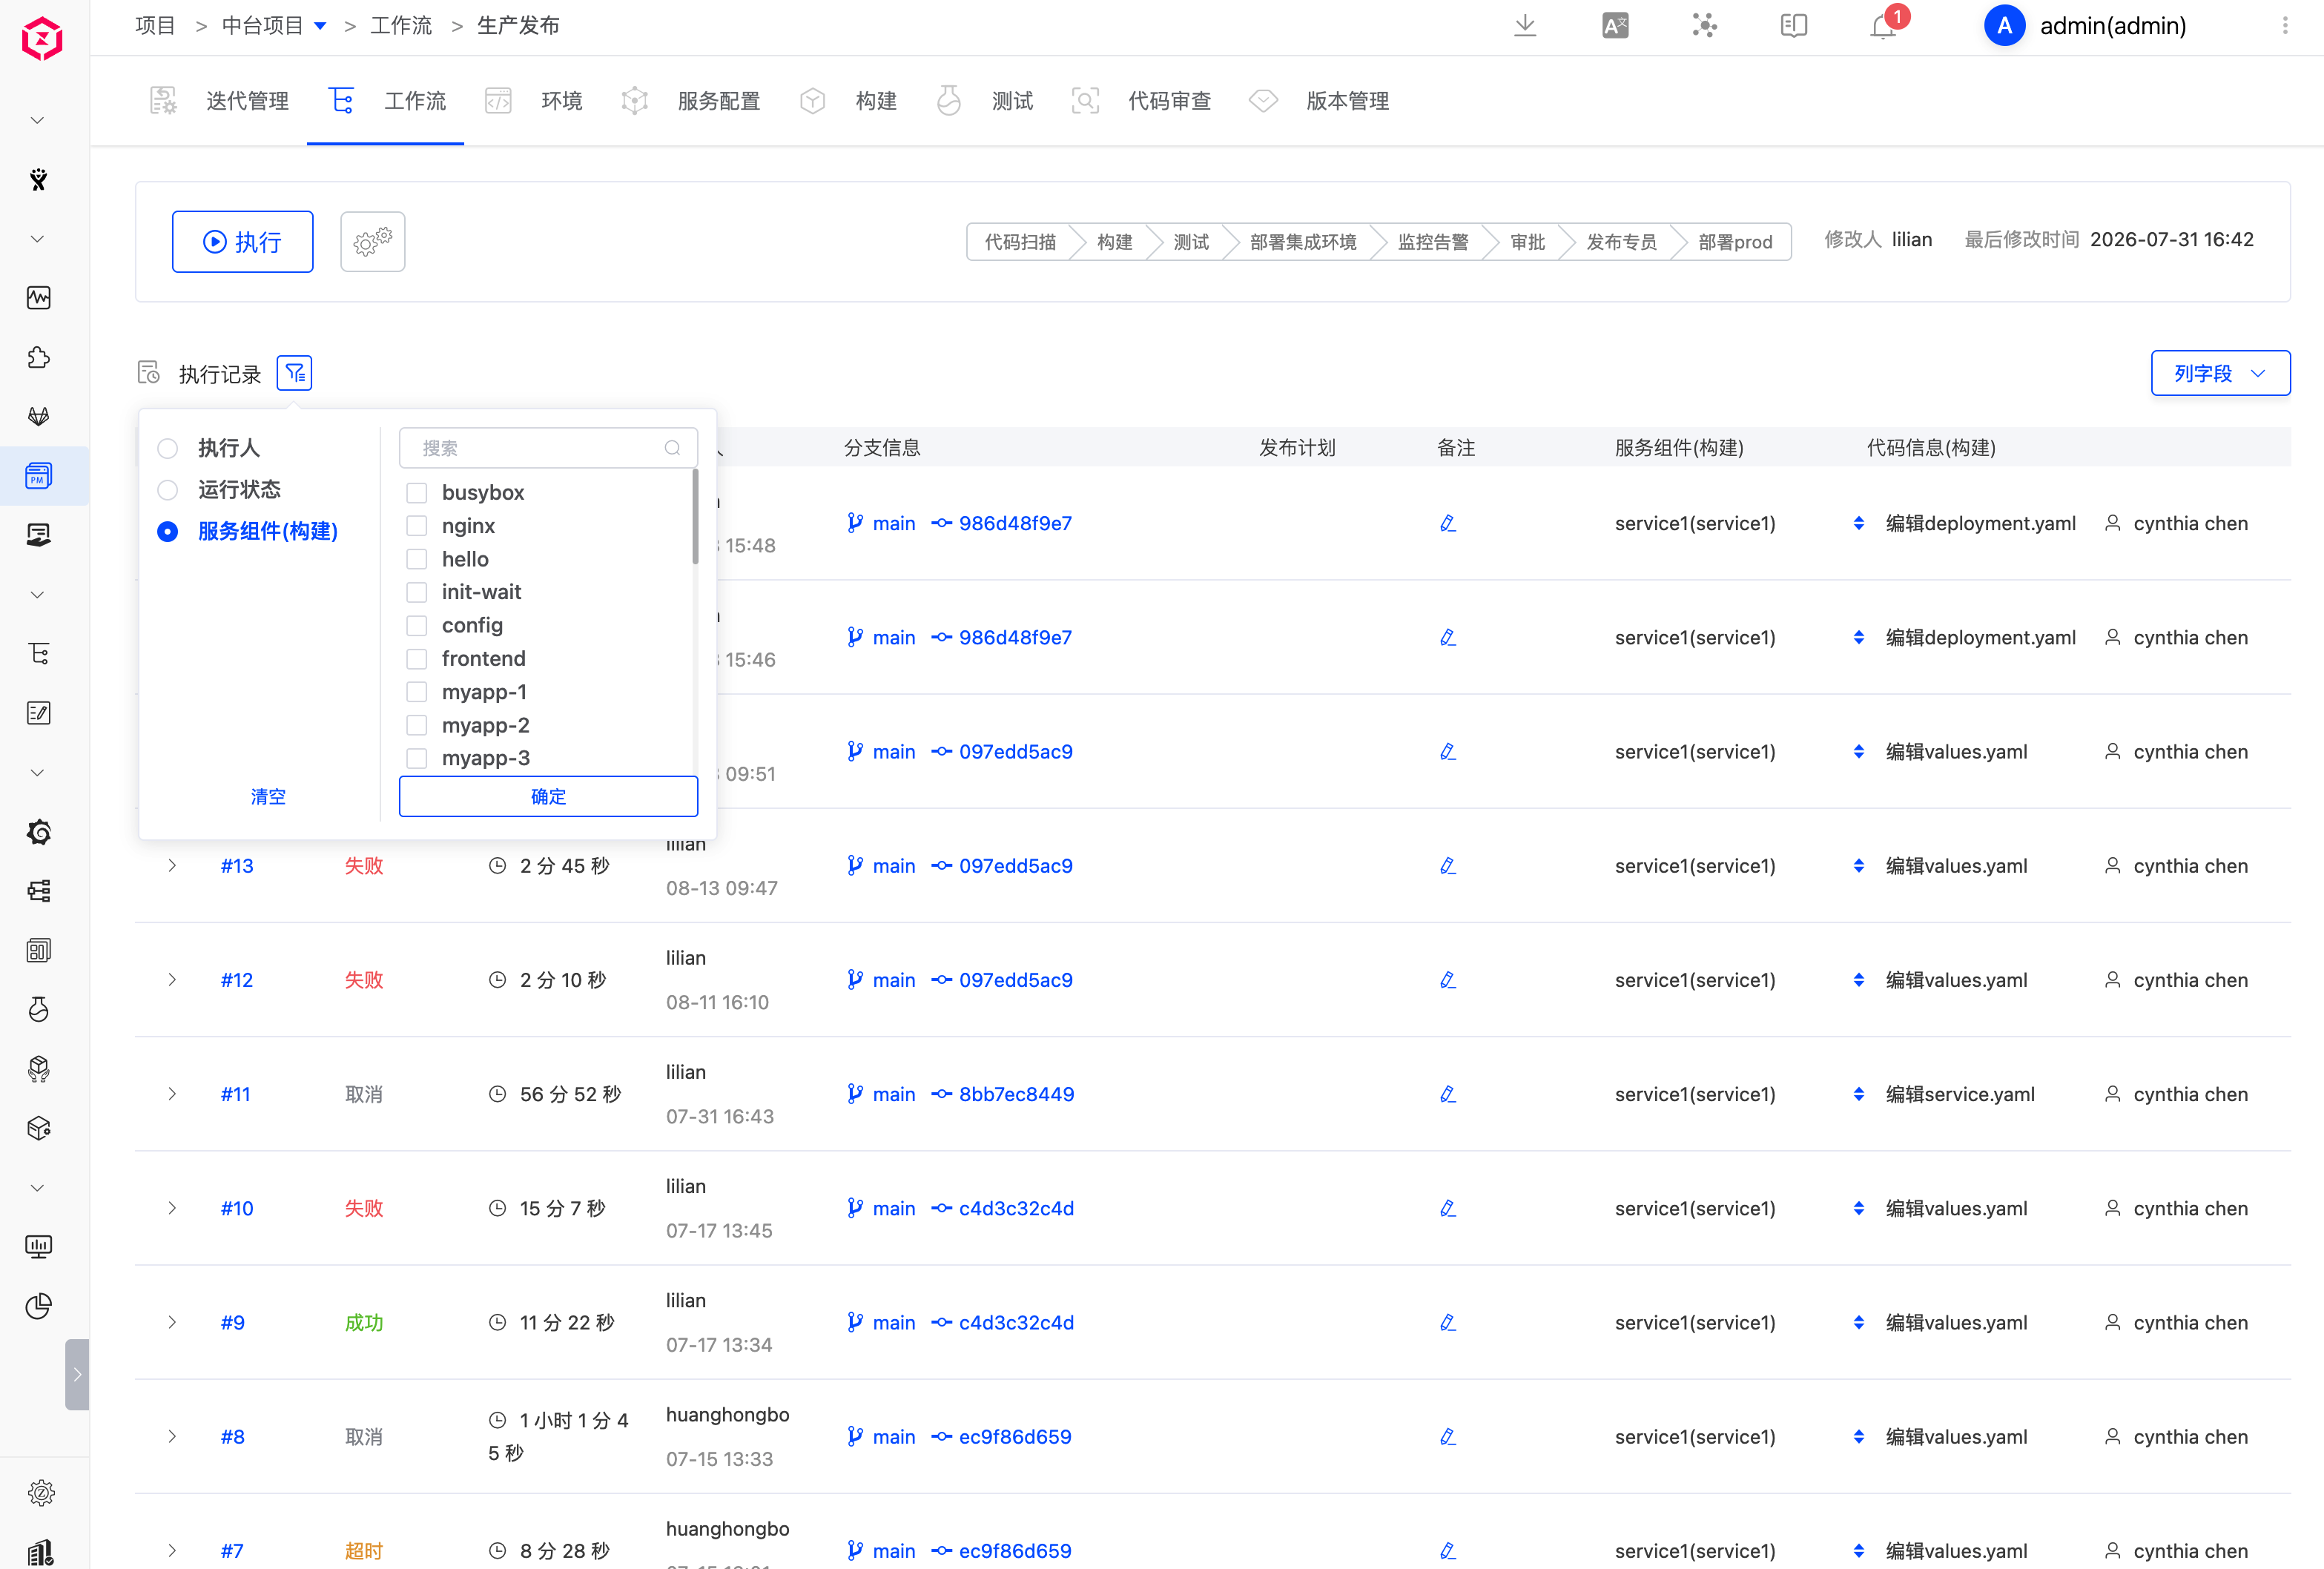
You can quickly filter workflow tasks by custom fields.
# Shared Storage
Zadig now supports shared storage in workflow jobs. The procedure is as follows:
- Configure cluster resources and define shared storage resources.
- Configure the workflow and add shared directories.
- Enable and apply shared storage in workflow jobs to share storage between jobs.
# Cluster Resource Configuration
See Cluster Shared Storage Resource Configuration.
# Workflow Configuration
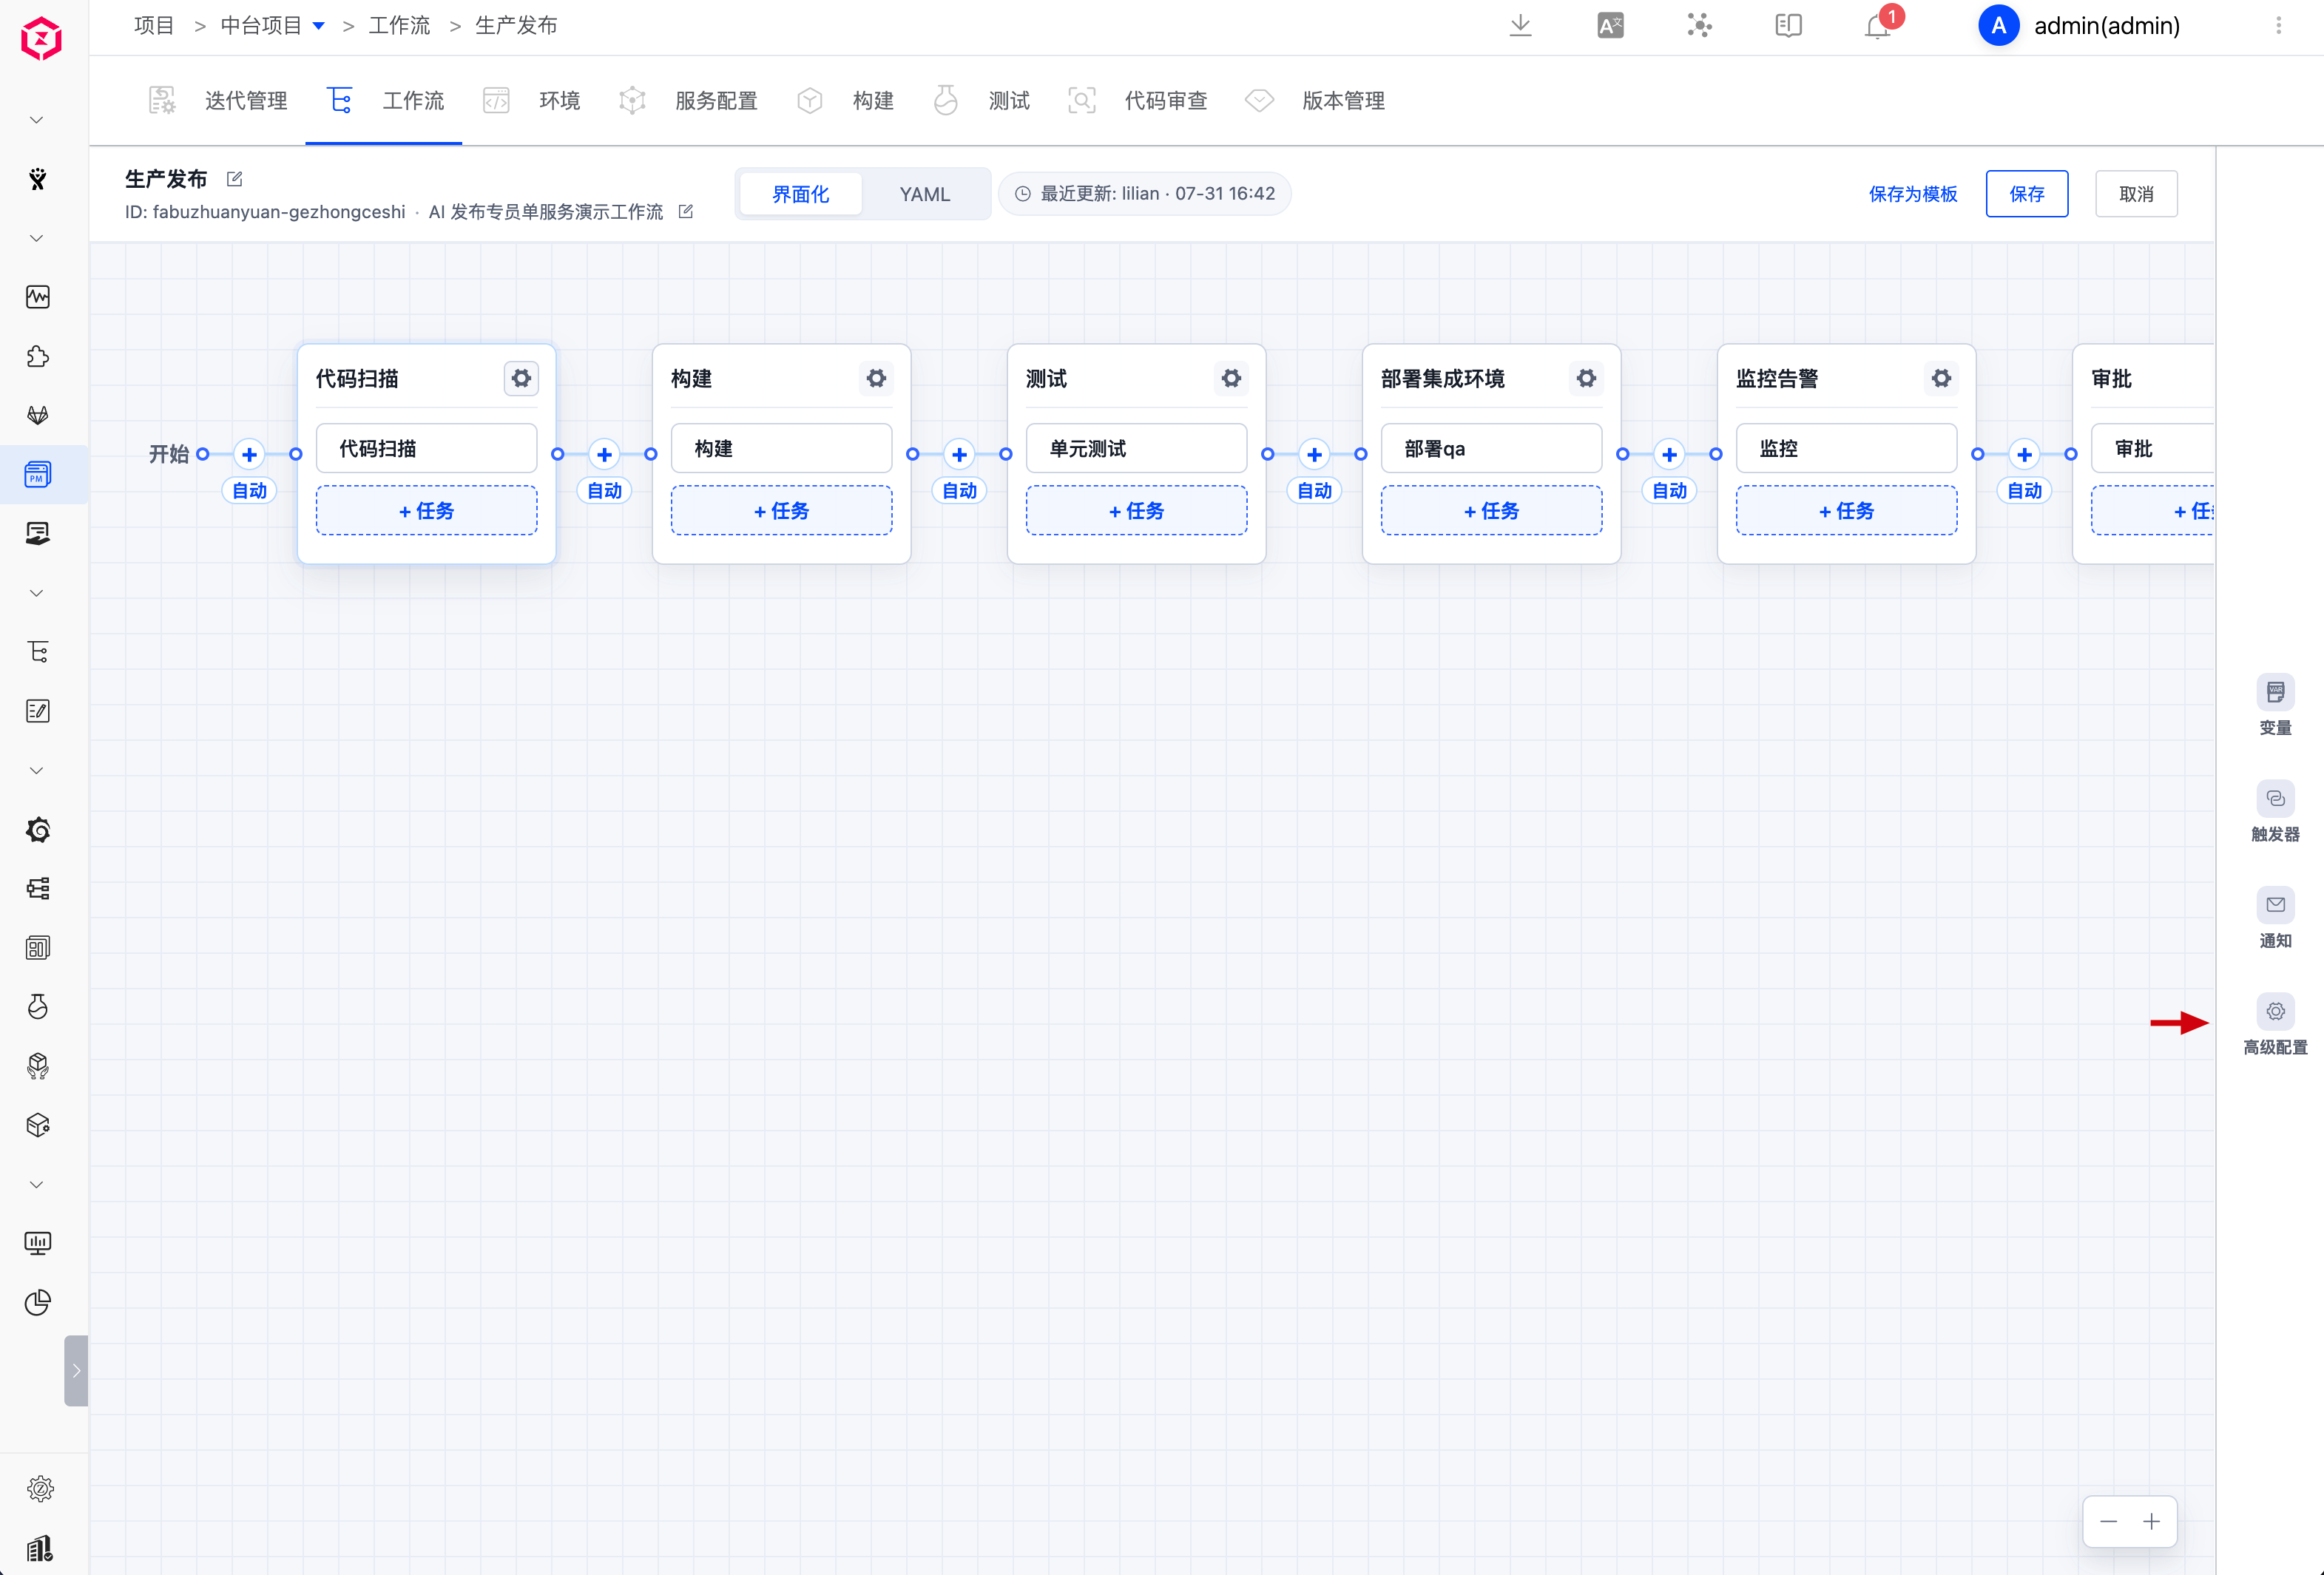
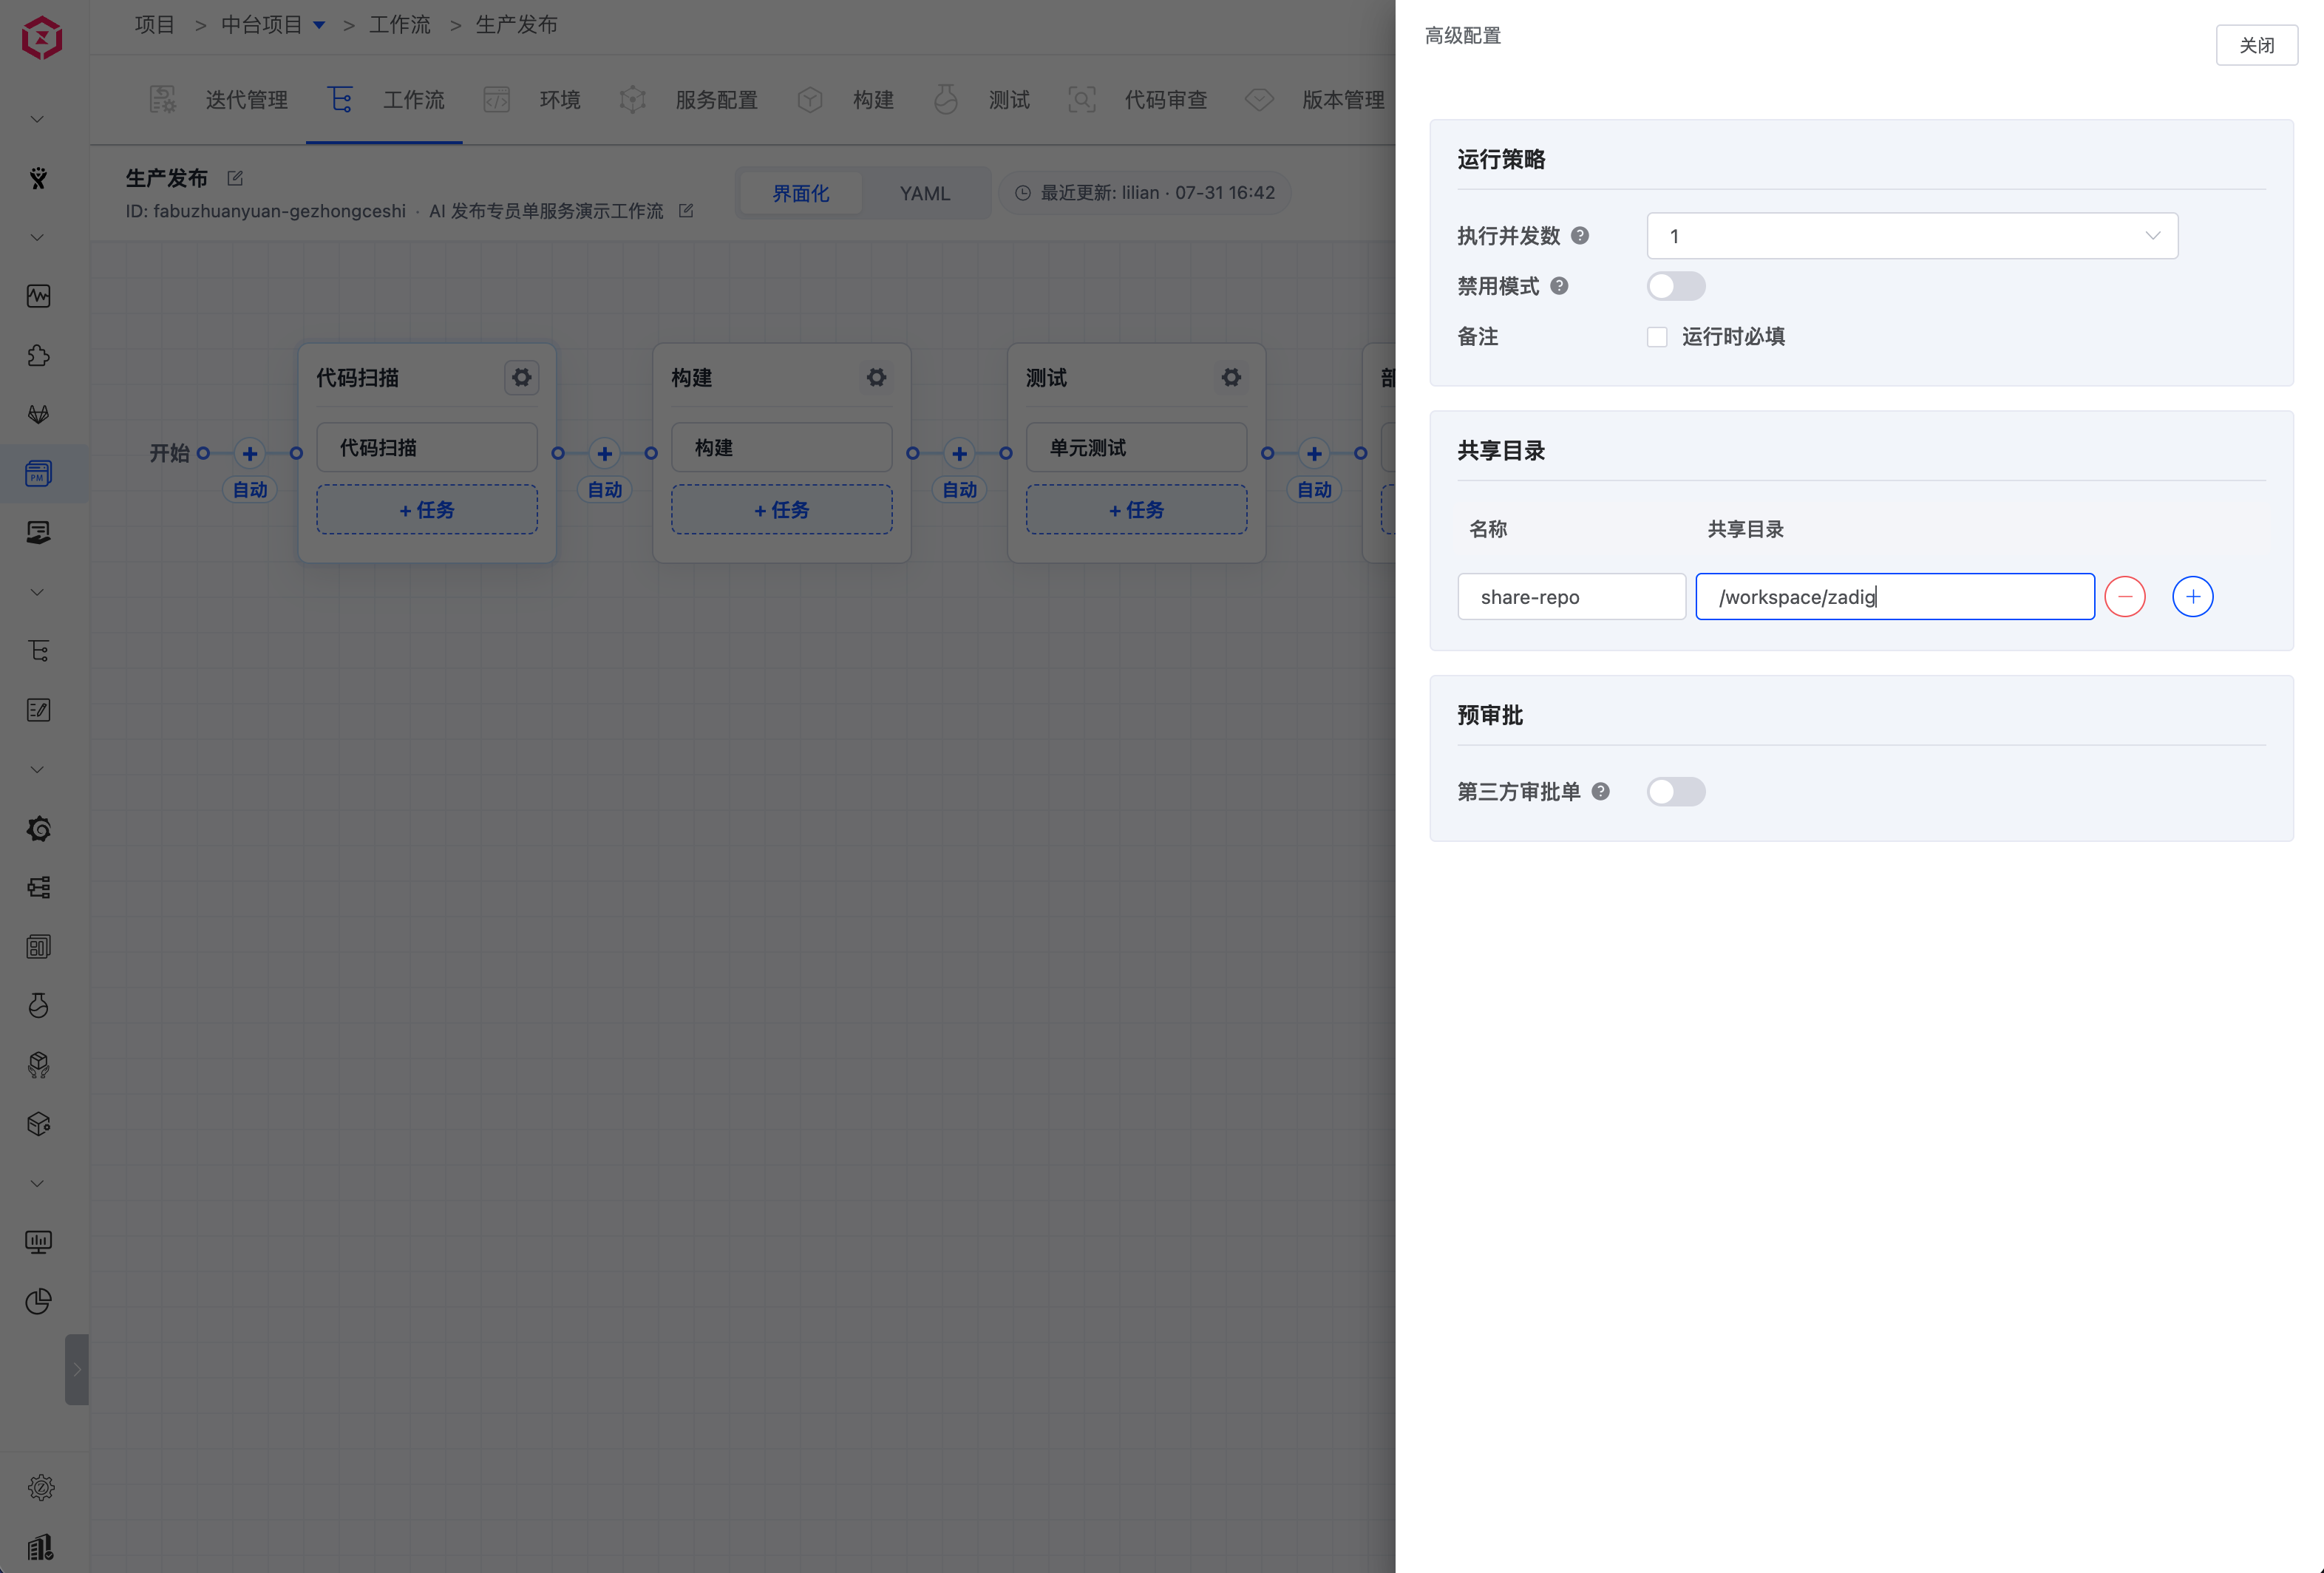
Edit the workflow, click Advanced Configuration, add a shared directory, and save.
# Workflow Job Configuration
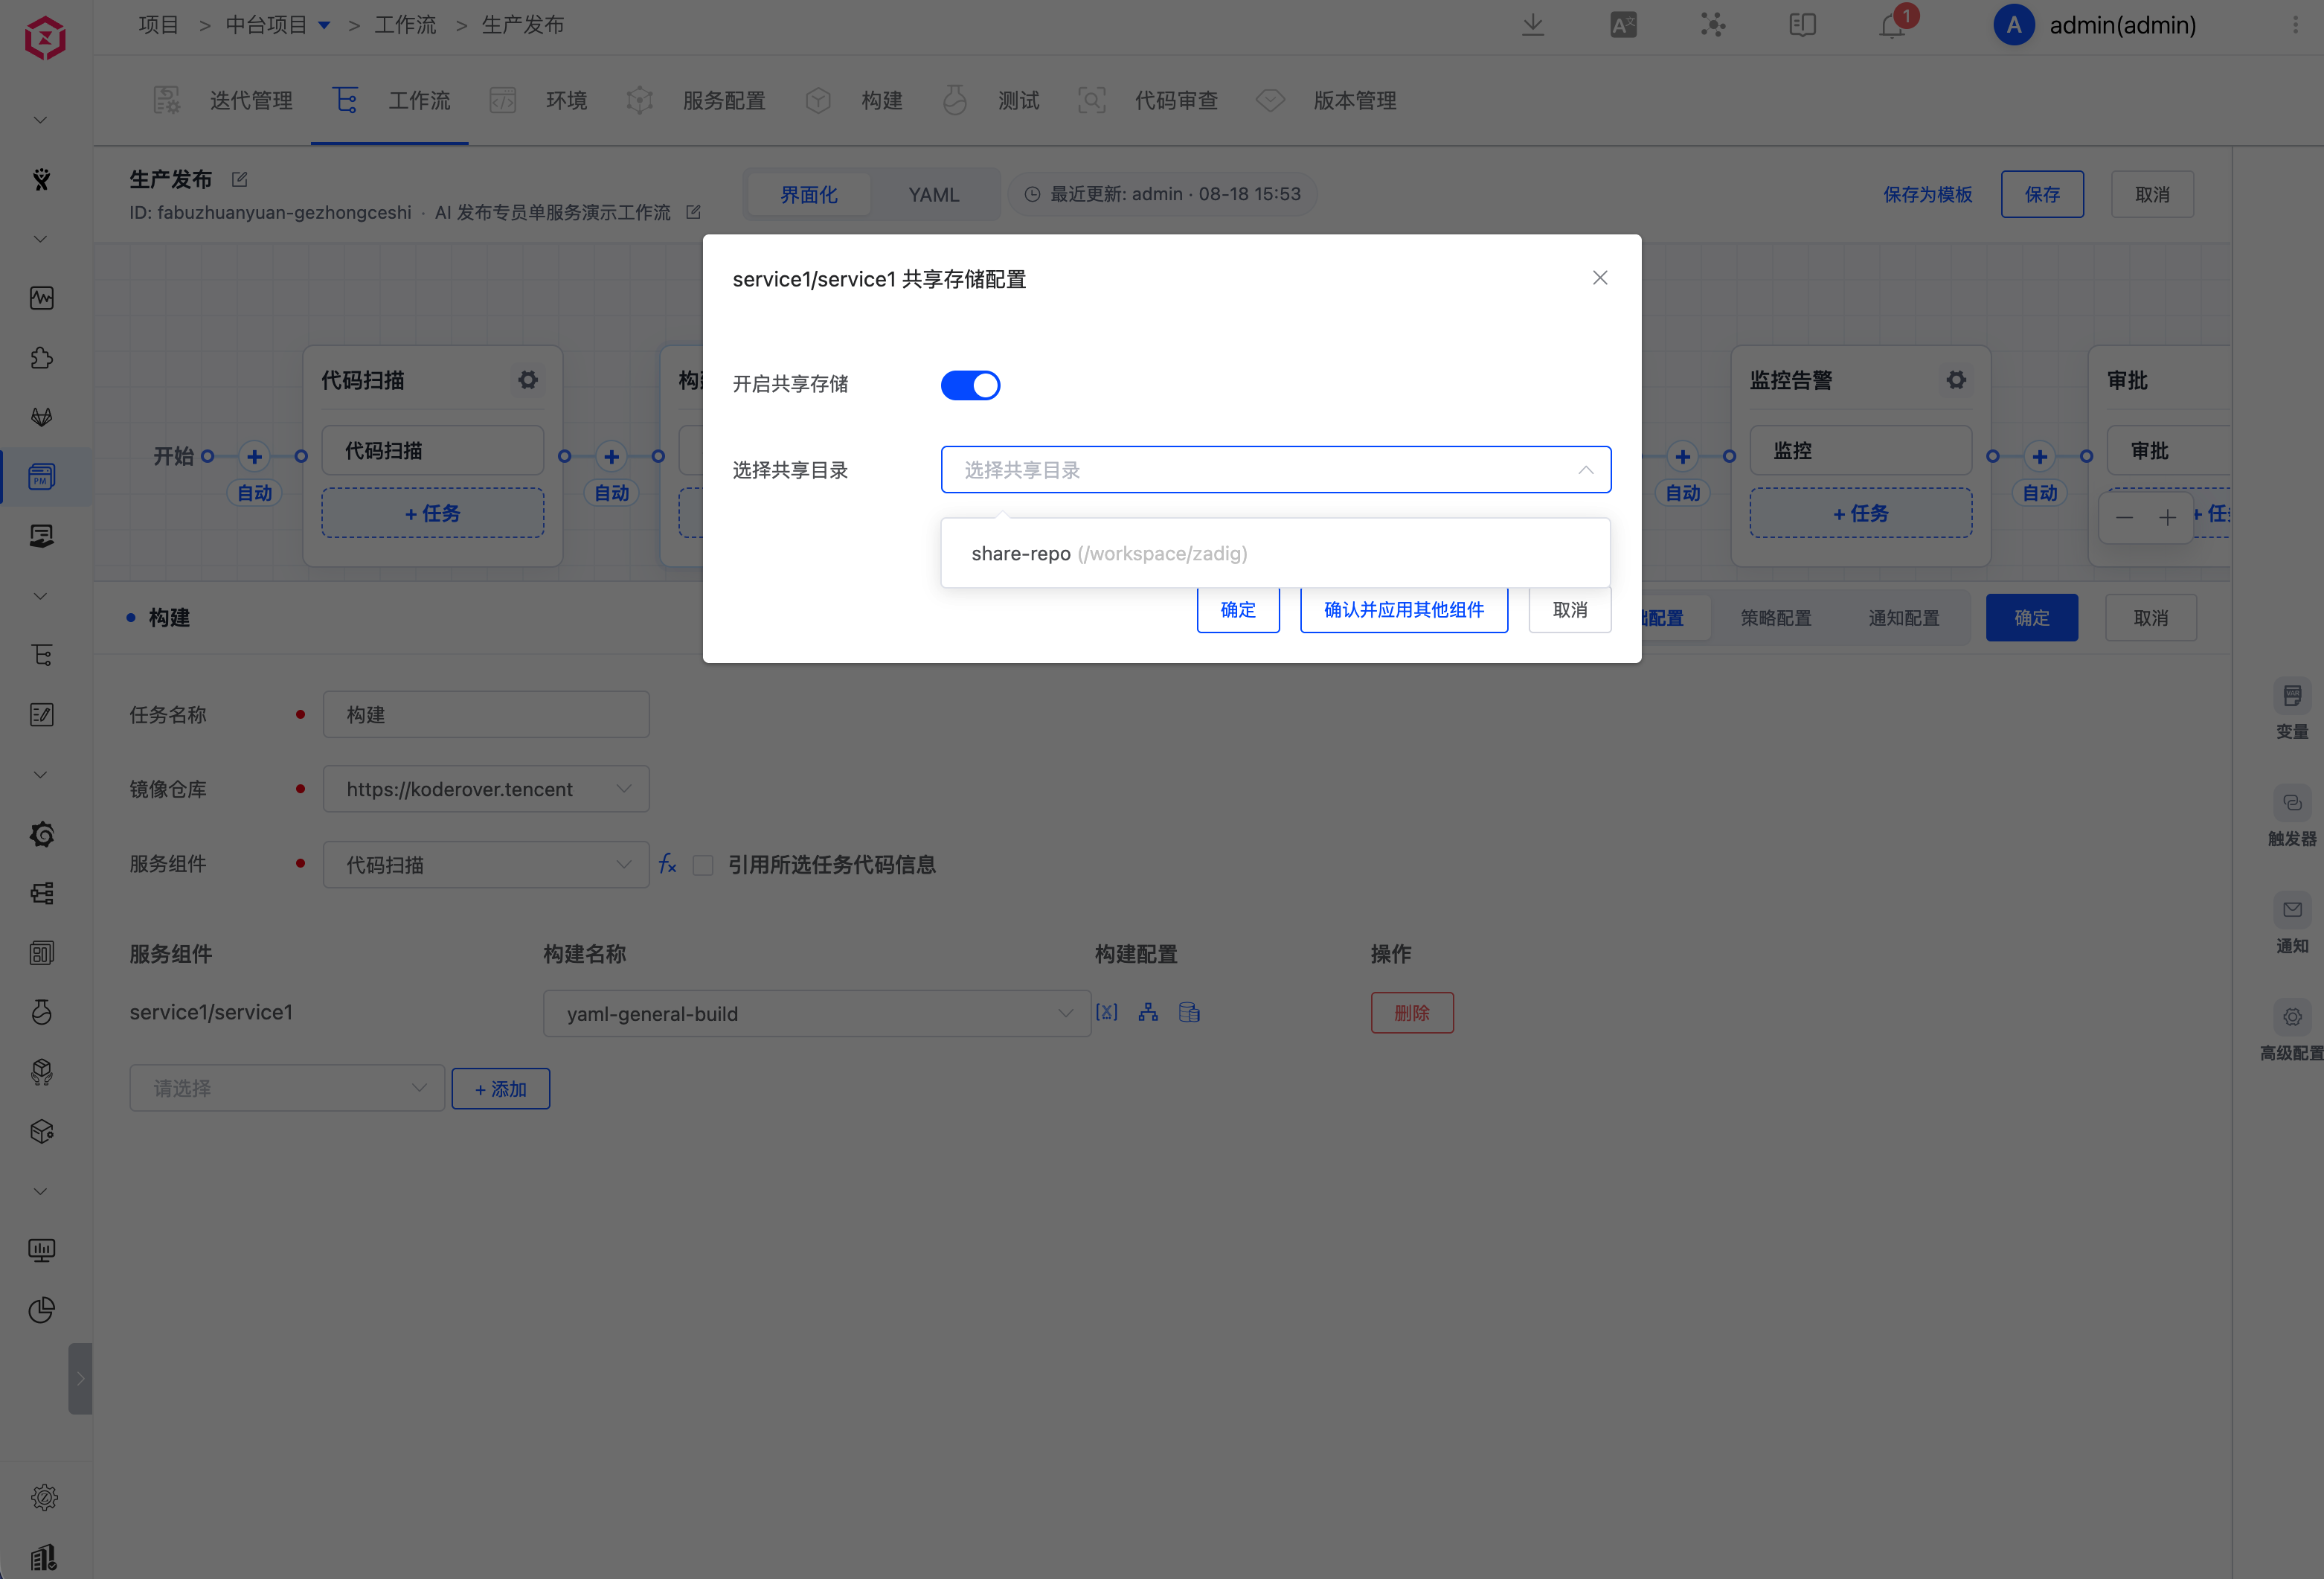
For build, test, and code scan jobs, click the shared storage icon in the corresponding job to enable shared storage and configure a shared directory. The following example uses a build job:
For jobs that support advanced configuration, enable shared storage in advanced configuration, select a shared directory, and configure the shared directory. The following example uses general script execution:
For jobs that support advanced configuration, see Advanced Configuration.